Showing posts with label algorithms. Show all posts

Daily Tech Digest - November 12, 2026

Quote for the Day
“You can’t fix a team by fixing individuals; you fix a team by fixing interactions.”
— Esther Derby
Audio Edition — Listen to Today’s Digest
Narrated version of the Daily Tech Digest
Article Thumbnail

The Rise of AI Site Reliability Engineers – Can Autonomous Agents Handle Production Incidents

The role of Site Reliability Engineering is undergoing a major shift as AI-driven autonomous agents take on the responsibility of managing production incidents. While traditional automation simply executed static scripts, modern AI tools can read logs, spot anomalies, and actively reroute traffic or roll back deployments without human intervention. This capability drastically accelerates incident recovery and reduces alert fatigue, allowing minor outages to be fixed before users ever notice them. However, relying entirely on autonomous systems introduces hidden dangers to overall stability. AI agents lack the situational context and intuition required for messy, unprecedented failures, and their speed means a wrong decision can instantly cascade across an entire infrastructure. Moreover, these automated quick fixes can easily mask deeper underlying infrastructure problems that silently worsen over time until a massive failure occurs. Consequently, the future of system operations is not a fully human-free environment. Instead, human engineers are transitioning from frontline firefighters to strategic architects. Their new focus is on setting boundaries, designing guardrails, and managing the AI systems to ensure that automation acts safely and effectively when standard procedures inevitably fail.

Read Original Article →

Moving from organisational implementation to scaling of AI

As organizations rapidly adopt artificial intelligence, the next major hurdle is scaling that technology to achieve measurable impact, according to a recent global survey by BearingPoint. While many companies successfully launch small AI pilots to automate tasks and increase capacity, deeply integrating these solutions across the enterprise remains rare. Without proper planning, businesses risk falling into an "AI productivity trap," where new technology fails to improve financial performance or support sustainable growth. Moving from a pilot to widespread use requires strict attention to governance, regulatory compliance, data accountability, and adapting workforce structures to support new capabilities. The report highlights that organizations must balance the agility to experiment with the discipline required to build strong foundations for scaling. Interestingly, Irish organizations are particularly ambitious, prioritizing agentic AI and actively assessing their skills gaps, though they still face challenges in enterprise-wide rollout. Ultimately, successful AI scaling depends on connecting investment to clear financial goals and treating workforce strategy as an integral part of the AI roadmap, ensuring that technological capacity is converted into genuine, long-lasting organizational value.

Read Original Article →
Article Thumbnail

Choosing QuePaxa, an unusual consensus algorithm

Cloudflare explains why it chose QuePaxa, a relatively new consensus algorithm, for Meerkat, its experimental distributed service for managing a global control plane. Traditional approaches such as Raft and Paxos often depend on a leader to coordinate decisions. They work well when networks are stable, but a slow, disconnected, or failed leader can stall the system while other machines detect the problem and elect a replacement. This becomes difficult across global networks, where latency and temporary connectivity problems are common. QuePaxa takes a different approach: its leader is optional, other machines can continue proposing decisions, and proposals cooperate rather than repeatedly blocking one another. Under good network conditions, the leader can still reach agreement quickly. When conditions deteriorate, the system may slow down but can continue processing requests without waiting for formal failure detection. Cloudflare says its Meerkat evaluations across widely distributed servers showed this behaviour in practice. The trade-off is maturity: QuePaxa has not been tested as extensively as established alternatives. Cloudflare is therefore using formal verification, simulation, and fault-injection testing as it develops the implementation further.

Read Original Article →

Measuring AI’s Unintended Consequences

As teams increasingly adopt AI to accelerate software development, measuring its unintended consequences becomes critical for long-term sustainability. While AI tools boost delivery speed, heavy reliance on them can generate complex code that humans struggle to understand, potentially causing developer burnout, vendor lock-in, and rising maintenance costs. The core metric to monitor these hidden costs is the "cost of change," which acts like a tax on every software update you make. To gauge this effectively, engineering leaders should track their value-add percentage—the ratio of time spent building new features versus non-value-add tasks like bug fixes and technical debt. While a certain baseline of maintenance is unavoidable, a declining value-add percentage indicates that AI-generated code is increasing organizational drag. Other helpful indicators include standard deployment metrics and individual AI token usage patterns. Because these data points are inherently noisy and can take months to reveal clear trends, organizations should supplement them with forward-looking maintenance models and scenario planning. Ultimately, relying on both data tracking and strategic models allows leaders to make informed judgments and protect their teams' capacity for meaningful work.
Read Original Article →
Article Thumbnail

Building the infrastructure of consent for India’s digital economy

The growth of India’s digital economy depends on building a robust infrastructure of consent. At its core, the Data Empowerment and Protection Architecture (DEPA) forms the foundation of this ecosystem by changing how user data is managed and shared across sectors. Instead of keeping data locked in rigid, isolated systems, this framework places control back in the hands of the individual. Through a network of licensed account aggregators, users can securely share their financial or personal information with service providers they trust—and they can revoke that access at any time. This approach not only simplifies compliance for businesses but also builds deep trust with consumers by offering transparency and choice. By prioritizing privacy alongside progress, India is setting a global standard for digital rights. For businesses, adopting these transparent practices means better customer relationships and a streamlined approach to offering personalized services. Ultimately, building a secure, consent-based infrastructure ensures that innovation serves everyone fairly, turning data protection from a simple regulatory checklist into a fundamental driver of a thriving, inclusive digital economy.

Read Original Article →

The Cyber Resilience Act clock doesn’t stop for weekends

In a recent Help Net Security interview, Copla CEO Aurimas Bakas explores the demanding reality of the EU Cyber Resilience Act (CRA) and its stringent vulnerability reporting mandates. While many company boards fixate on the CE marking deadline of December 2027, they overlook that active vulnerability reporting obligations already took effect in September 2026. This timeline gap creates significant risk, as non-compliance carries massive penalties. To prepare, organizations must develop a comprehensive register of every product version currently running in customer environments, including legacy firmware. Bakas emphasizes that the 24-hour reporting clock begins the moment a company becomes aware of an exploited flaw. This makes it critical to define what “awareness” means internally and clearly designate who has the authority to initiate the countdown—even at 2 a.m. on a Sunday. He advises CISOs to contractually bind suppliers to strict reporting timeframes matching their regulatory requirements. Finally, conducting unannounced tabletop exercises on weekends can reveal whether a team can realistically execute a handover, verify their multi-factor authentication, and draft an early warning within the mandatory 24-hour window.
Read Original Article →
Article Thumbnail

US Democrats prepare to scrutinize federal biometric surveillance

With Democrats set to take control of Congress, federal use of biometric surveillance and digital identity systems is about to face intense scrutiny. Lawmakers are preparing to investigate existing surveillance infrastructure, particularly within the Department of Homeland Security, focusing on facial recognition, mobile biometric identification, and the commercial data brokers that support these systems. However, they face a complicated reality. Billions of dollars in previously approved funding are already locked in for border security and immigration enforcement technologies, making it difficult to simply defund these programs. As a result, Congress is expected to lean heavily on its investigative powers to demand accountability and transparency from agencies and their private contractors. The core challenge will be determining which biometric applications are legitimate and establishing clear boundaries for their use. While some lawmakers advocate for strict moratoriums on facial recognition and new federal privacy laws to regulate how companies handle sensitive data, others recognize the need to modernize digital identity infrastructure to prevent fraud. The upcoming legislative session will likely focus on finding a balance between security needs and privacy protections.
Read Original Article →
Article Thumbnail

The iOS Crash We Could Not Reproduce

Debugging intermittent production crashes in iOS applications can often be a frustrating experience, especially when the logs lack a clear stack trace and local testing fails to reproduce the issue. This scenario unfolded in a large-scale consumer app where a vague SIGBUS error tied to NSAttributedString appeared randomly, resisting all initial attempts to pinpoint the failing code. While early defensive fixes—such as tightening object ownership and updating concurrency patterns with async/await and MainActor—lowered the overall crash rate, they merely altered the timing of the defect rather than solving the underlying problem. The turning point occurred when a QA engineer managed to probabilistically reproduce the crash on a specific device, transforming speculative debugging into testable engineering work. This controlled fault isolation eventually revealed that HTML imports through NSAttributedString have a strict main-thread requirement, which is easily overlooked when the call is nested within asynchronous screen preparation. Ultimately, implementing a shared main-actor abstraction proved to be a much stronger and more reliable safeguard than expecting developers to remember a nuanced framework threading rule at every single call site.

Read Original Article →
Article Thumbnail

Why does old access outlive the job?

Organizations consistently struggle with lingering access rights because granting permissions is fast and driven by clear business needs, while removing them is an overlooked administrative chore. When employees change roles, their new access is typically approved within hours so they can start working. However, their old permissions often remain active simply because no one takes ownership of revoking them. During routine security reviews, managers frequently rubber-stamp existing access levels because dashboards rarely show if the permissions are actually being used, and removing them might accidentally break a process. To fix this dangerous oversight without adding expensive new software, companies need to treat every internal job transfer as an offboarding event where old managers explicitly confirm what is no longer needed. Additionally, assigning clear expiration dates and named owners to all permissions prevents endless access creep. Finally, displaying the last login timestamp directly on security review screens makes it much easier for managers to confidently delete dormant accounts. By treating permission removal with the same urgency as granting it, organizations can dramatically shrink their security vulnerabilities.

Read Original Article →
Article Thumbnail

eMudhra Revokes 8 More CAs It Previously Declared Unaffected by Key Compromise

The Python script responsible for eMudhra's October key compromise has now resulted in the revocation of eight additional intermediate certificate authorities (CAs), despite earlier claims that they were unaffected. According to the company's recent incident report, these eight CAs were revoked after an internal investigation revealed that their RSA keys were processed through the same flawed python script during a key ceremony in April 2025. Although the script did not shorten these RSA keys to a single byte—the critical error that compromised the original eight ECDSA keys—the private keys were still exposed in the memory of the ceremony computer. Because eMudhra cannot definitively prove that this handling met its own strict compliance standards or verify exactly how the key material was managed, the company was forced to revoke the CAs. These certificates were used for websites and code signing across various organizations. As a broader response, eMudhra is currently exiting the publicly trusted TLS certificate business, with major browsers like Microsoft, Google, and Apple scheduled to phase out trust in their remaining root certificates by late November.

Read Original Article →

Daily Tech Digest - October 29, 2026

Quote for the Day
“The most expensive software is the one that doesn’t meet the needs of its users.”
— Karl Wiegers
Audio Edition — Listen to Today’s Digest
Narrated version of the Daily Tech Digest
Article Thumbnail

When prevention fails: Why cyber resilience is the next big test of trust

The article explains that even well‑protected organizations can be thrown into chaos when a serious cyberattack disrupts basic operations, leaving leaders unsure which systems or data can still be trusted. It argues that prevention alone is no longer enough, because no control is perfect and attackers often find ways around strong defenses. Cyber resilience, therefore, becomes the next major test of trust: the ability to keep essential functions running, recover safely, and restore confidence after an incident. The piece highlights that backups are only useful if they can be accessed securely and restored without contamination, and that recovery plans must assume that some systems — including backup environments — may be compromised. Drawing on NIST guidance, it outlines four goals for resilience: anticipating threats, withstanding disruption, recovering trustworthy systems, and adapting based on lessons learned. The article’s steady message is that resilience must be designed into systems from the start, not treated as an afterthought, because the real challenge after an attack is determining what can still be relied on.

Read Original Article →

Programming Languages and Choosing a Path

Learning a programming language is about learning how to translate your logic into a format a computer can understand. An algorithm outlines the solution to a problem, while a programming language simply provides the vocabulary and rules to express that solution. Knowing the syntax of a language will not automatically make your logic correct. Behind the scenes, languages use tools like compilers or interpreters to turn human-readable instructions into actions the computer hardware can execute. When choosing your first programming language, it is important to remember that there is no universal best choice. Languages are tools built for different jobs. For example, C++ is great for competitive programming, Java offers strong structure for enterprise systems, and Python is highly readable and ideal for data tasks. Instead of getting caught up in the search for the perfect language, beginners should pick one that aligns with their immediate goals and local support system. Learn enough basics to express your logic clearly, and then focus on mastering problem-solving, which is the true core skill of programming.

Read Original Article →
Article Thumbnail

Beyond Binary Quantum Computing: Exploring Higher-Dimensional Qudits

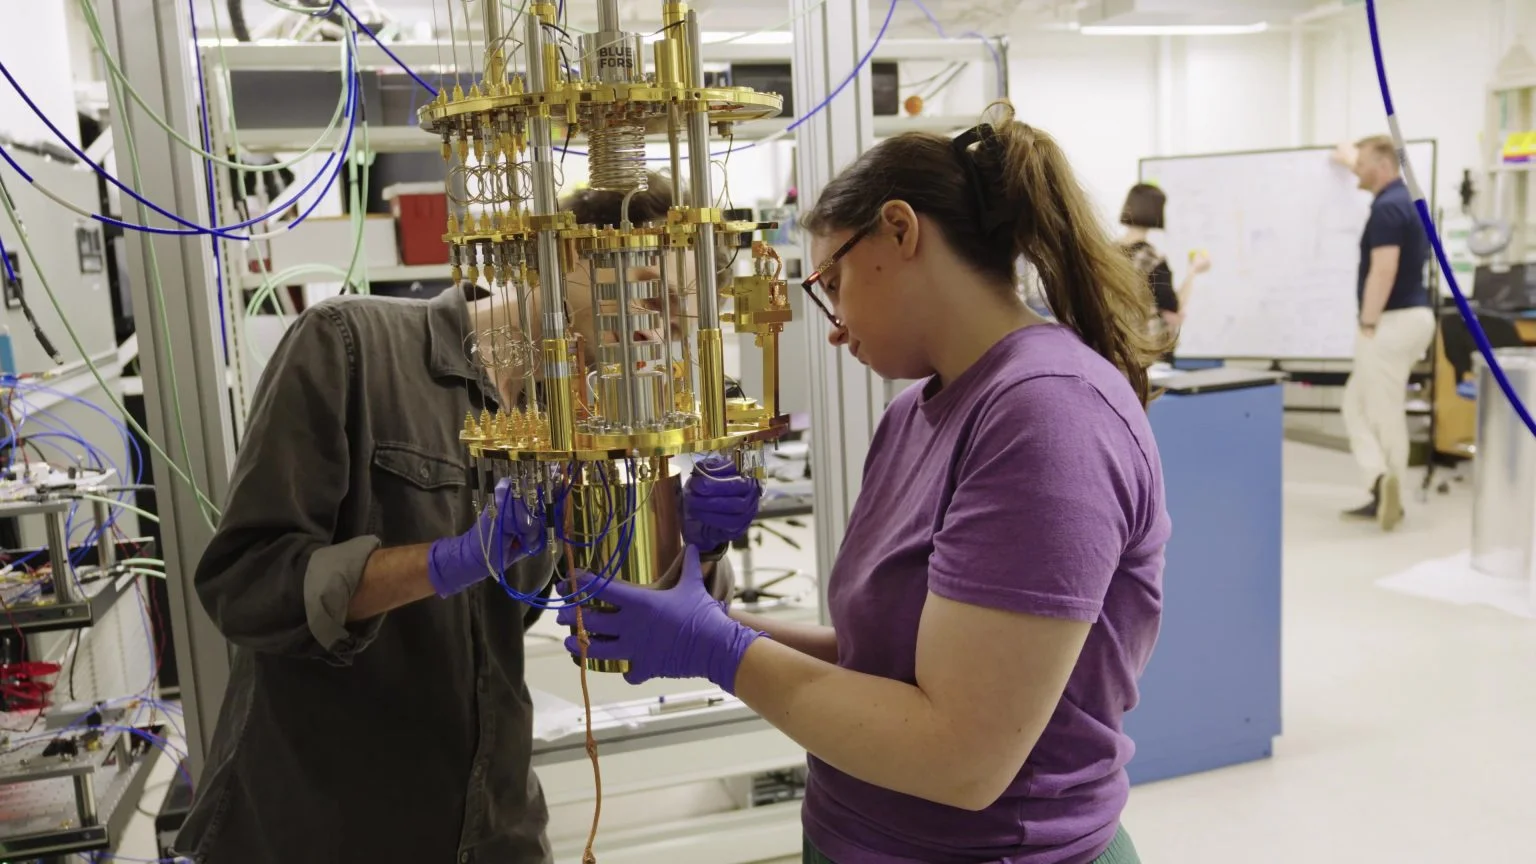
Researchers at the University of Rochester, led by Professor Machiel Blok, are exploring a new approach to quantum computing using "qudits" instead of standard qubits. While traditional quantum computers rely on binary systems with just two energy states, qudits can store information across multiple levels. This concept mimics the natural world, where atoms and molecules naturally exist in multiple states. By matching the computer's structure to the physical problem it is trying to solve, the team believes qudits could offer a much more efficient way to tackle complex challenges in chemistry and physics. To make this work, the researchers developed a new method to control all energy transitions simultaneously, essentially building a denser, high-rise structure for information rather than a sprawling, flat one. Supported by reliable cooling technology, the lab also provides practical experience for students. Ultimately, this research suggests the future of quantum computing will likely rely on a mix of different systems tailored to specific problems, rather than a single binary approach.

Read Original Article →

Why Faster Algorithms Aren't Enough to Build High-Performance Data Platforms

The article argues that high‑performance data platforms cannot be created simply by swapping in faster algorithms or adding more hardware. Performance, it says, is an architectural outcome shaped by many upstream decisions about how data is represented, moved, stored, and delivered. Faster joins or better allocators help only at the margins; they cannot fix a system that is fundamentally slow because of poor layout, excessive data movement, or inefficient memory patterns. The piece highlights that modern platforms already rely on highly optimized libraries, so the real bottlenecks often appear between those functions — for example, when unnecessary tables are materialized, when workflows shuffle large datasets across layers, or when memory allocation becomes a long‑tail problem. It also notes that parallelizing work across CPU cores is relatively easy compared to designing a pipeline that avoids hidden costs in browsers, storage formats, or intermediate transformations. The steady message is that performance emerges from dozens of coordinated design choices, and no single algorithmic improvement can compensate for weak architectural foundations.

Read Original Article →
Article Thumbnail

Why decision-making is the next frontier of modern cyber resilience

The article explains that while many organizations have strong security tools and threat visibility, they still suffer vastly different outcomes during a cyberattack. This difference comes down to decision-making. Knowing a threat exists does not automatically tell leaders how to prioritize their limited resources or which systems to fix first. Standard security models improve accountability but often fail to connect technical risks with actual business goals. To close this gap, the author suggests adopting a decision system framework that translates threat data into clear, actionable choices. This approach evaluates risks based on their real-world impact on core business functions rather than just their technical severity. By blending financial realities, trust, and business priorities into the security process, leaders can make faster, better-coordinated choices during a crisis. Ultimately, effective security is no longer just about building taller walls or spotting potential attacks; it is about having a clear, reliable method to decide exactly where to act, what to protect first, and how to recover quickly when disruptions occur.

Read Original Article →

Wazuh and AI for Enhanced SOC Workflows

As cyber threats grow more complex, Security Operations Centers face an overwhelming volume of daily alerts that can easily cause analyst fatigue and missed critical events. To manage this workload, organizations are integrating artificial intelligence to support their security teams rather than replace them. Platforms like Wazuh address this need by offering flexible AI tools that streamline threat detection and response. For cloud users, the Wazuh AI Analyst automatically reviews security data using secure cloud models to deliver scheduled, comprehensive insights on vulnerabilities and overall security posture without exposing private data. For teams with strict privacy requirements, Wazuh supports self-hosted local models like Llama 3, keeping all log data safely within the company network. Alternatively, organizations can connect external models like Claude 3.5 Haiku directly into their dashboard to provide a helpful assistant for daily tasks. By handling repetitive analysis and data correlation, these AI integrations allow human analysts to focus on making the final decisions and keeping the organization secure.

Read Original Article →
Article Thumbnail

What Should a Business Do After a Personal Data Breach in India?

The article outlines the practical steps an Indian business should take immediately after discovering a personal data breach, emphasizing that quick, organized action matters more than panic. It begins with containment: isolating affected systems, revoking compromised credentials, and stopping further data loss. The next step is verification — confirming what happened, which data was exposed, and whether the breach is still active. The article stresses that businesses must document facts carefully because regulators will expect clear evidence of what was done and when. Under the DPDP Act, organizations must notify the Data Protection Board and affected individuals when harm is likely, and the article explains that vague or delayed communication can worsen legal and reputational consequences. It also highlights the need to preserve logs, review security controls, and assess whether vendors or third‑party processors contributed to the incident. The message is steady: a breach response is both a technical and governance exercise, and businesses must combine containment, transparency, and structured follow‑up to restore trust and meet regulatory expectations.

Read Original Article →

Shadow AI vs. Shadow IT: What's the Difference?

The article explains that “shadow AI” is emerging as a distinct and faster‑moving risk compared to traditional shadow IT. Shadow IT has long referred to employees using unapproved apps or services, often exposing data by storing it in places the organization cannot monitor. Shadow AI, however, introduces a sharper problem: employees feed internal data into AI tools — sometimes through personal accounts or new AI features inside already‑approved applications — without any governance. The piece notes that one in five organizations have already seen data exposure through personal AI accounts, showing how easily risky behavior can slip past existing controls. Unlike shadow IT, where data can often be retrieved or redirected, data given to an AI model may be processed, retained, or used for training in ways the organization cannot reverse. This shifts the governance challenge from simply discovering unauthorized apps to understanding what data enters AI systems, what outputs they generate, and what actions those systems can take. The article’s steady message is that AI requires new visibility, new controls, and a more nuanced approach than legacy shadow‑IT playbooks.

Read Original Article →
Article Thumbnail

When auditors come for your AI algorithms

As artificial intelligence increasingly influences critical business operations, traditional auditing methods are falling short. Conventional audits rely on predictable, step-by-step trails, but AI models—especially large language models—are inherently variable. This unpredictability makes it difficult for CIOs to explain how an AI system reached a specific conclusion, which frustrates auditors demanding clear evidence and accountability. The core problem often stems from vague ownership across different teams, rather than the technology itself. To bridge this gap, organizations must abandon point-in-time audits in favor of continuous monitoring and a structured accountability framework. This approach involves assessing risks during system design, continuously reviewing those risks as the technology evolves, and conducting independent evaluations of the process. Rather than waiting for a massive corporate AI rollout, leaders need to act now, as AI features are already embedded in everyday enterprise software. By treating audit readiness as a core business capability rather than a compliance chore, CIOs can take proactive ownership, reduce risk, and confidently support ongoing innovation.

Read Original Article →
Article Thumbnail

Building Review Intelligence into the SDLC with AI Agents and Archetypes

As artificial intelligence evolves beyond basic code generation, AI agents are becoming active collaborators throughout the software delivery lifecycle. Instead of replacing human architects, developers, and reviewers, these agents act as helpful partners that provide vital context and consistent feedback. To truly benefit from this shift, organizations should move past generic AI prompts and develop specialized, well-defined skills for design, architecture, and code reviews. These targeted skills can be organized into reusable patterns, or archetypes, tailored to specific tasks like building new applications, upgrading older systems, or migrating to the cloud. By employing a coordinated group of agents driven by strict checklists, a central agent can organize the workflow, while specialized agents handle security, performance, and compliance. A final review agent ensures all feedback is practical and backed by evidence. Ultimately, this structured approach transforms informal AI assistance into a reliable quality assurance process, allowing engineering teams to manage the increasing speed of modern software development with clarity and confidence.

Read Original Article →

Daily Tech Digest - July 31, 2026


Quote for the day:

“It’s hard to do a really good job on anything you don’t think about in the shower.” -- Paul Graham

🎧 Listen to the audio debrief on YouTube

▶ Play Audio Digest

Duration: 20 mins • Perfect for listening on the go.


Why it’s time to end developer ‘blind trust’ in software code

Software supply chain security company NetRise has updated its toolset to address the growing risk of compromised code packages by eliminating the blind trust developers often place in external software dependencies. As supply chain attacks become much more common, malicious packages can easily slip into automated enterprise builds and spread widely before security teams even notice them. To prevent this problem, NetRise is introducing package trust enforcement directly into everyday developer workflows. The enhanced platform evaluates the safety of code components before they are downloaded. The update includes three main enforcement mechanisms: a firewall for the command line interface, an extension for the Visual Studio Code editor, and plugins for artificial intelligence coding assistants like Gemini and Claude. By checking dependencies at the exact moment a developer or an AI assistant attempts to install them, the system can immediately block harmful or noncompliant files right at the source. This clear approach shifts security measures earlier into the development lifecycle, smoothly moving away from reactive responses to proactive defense. Company leadership emphasizes that software should always prove its integrity and origin before it is ever allowed to run. By integrating these essential checks into standard coding environments, organizations can confidently build applications without relying on unverified external code.


Security regression testing and abuse case testing for technical teams

Security testing often relies on isolated events like penetration tests, but technical teams achieve better results by integrating security regression and abuse case testing directly into the software delivery lifecycle. Security regression testing ensures that previously resolved vulnerabilities do not reappear after code refactoring, dependency updates, or configuration shifts. While traditional testing verifies that a system works for authorized users, security regression adds negative assertions to confirm that unauthorized actions are consistently blocked. To complement this, abuse case testing transforms theoretical threat models and past security incidents into concrete, testable scenarios from an attacker's perspective. Instead of just identifying risks, teams build specific tests to verify trust boundaries, business logic, and authorization rules. By prioritizing high-value controls, such as authentication, session management, and access control, organizations can focus their efforts on areas with the highest business risk and change frequency. Implementing these tests effectively requires a balanced approach. Teams should automate predictable checks within their deployment pipelines using standard testing tools, while reserving manual validation for complex workflows. Maintaining isolated test environments and ensuring reliable, noise-free automated checks prevents alert fatigue. Ultimately, this proactive strategy catches vulnerabilities much earlier in the process, reduces rework, and builds a significantly more resilient application over time.


Can AI Agents Be Aligned with Human Rights?

As artificial intelligence advances from simple chatbots to autonomous agents capable of making complex, extended decisions, the need to align these systems with human values becomes critical. Historically, the tech industry has focused on safety measures applied only after a model is built, often prioritizing corporate liability over broader societal impact. However, recent research explores a proactive training method which embeds international human rights law directly into the AI development process. By using globally recognized standards like the Universal Declaration of Human Rights, developers can provide models with a concrete framework to evaluate the consequences of their actions before they are deployed. In practical experiments, models trained with human rights guidelines proved better at recognizing severe, irreversible harms and protecting vulnerable groups compared to those trained on standard corporate safety rules. Instead of merely offering defensive legal disclaimers, human rights aligned agents actively considered how their choices might affect society at large. To make this the standard, the industry must develop new benchmarks to measure societal impact and create rules for when different rights conflict. Ultimately, building safer AI requires collaboration between computer scientists, legal experts, and civil society to ensure that future technology answers to universally shared legal standards rather than subjective company policies.


Quantum Computers May Put Internet Traffic at Risk. NIST Is Safeguarding Computers With New Standards

Quantum computers represent a significant future threat to current encryption methods, placing sensitive data such as financial transactions, medical records, and government secrets at serious risk. To effectively address this, the National Institute of Standards and Technology (NIST) has finalized three post-quantum cryptography (PQC) standards after more than a decade of transparent global research. While a quantum computer capable of breaking modern encryption does not yet exist, the urgency stems from adversaries continually intercepting and storing encrypted data today with the strict intention of unlocking it once the proper technology becomes fully available. Transitioning to these new PQC standards will be a complex, industry-wide process that inevitably takes years. Organizations are advised to begin planning immediately by carefully inventorying their current cryptographic systems, prioritizing their most sensitive data, and collaborating with technology vendors to implement PQC securely. For everyday individuals, the best preparation is simply to ensure their personal devices and software are set to install updates automatically. Over time, everyday applications and web services will smoothly adopt these new algorithms. Upgrading our cryptographic infrastructure is undoubtedly a substantial undertaking, but it ultimately provides a clear opportunity to systematically modernize aging systems and ensure our information remains highly secure and fully resilient.


The blueprint for innovation: 3 ways regulatory readiness is a competitive advantage

Instead of viewing regulations as an obstacle to innovation, successful companies recognize early compliance as a distinct advantage. Rather than waiting for new rules to pass and treating compliance as an afterthought, sensible leaders are embedding governance directly into their initial designs. This proactive method focuses on three main strategies. First, organizations build a strong foundation by integrating necessary controls at the start of a project, such as adding transparency features to artificial intelligence tools or placing fraud detection inside payment systems. Second, companies ensure their internal teams work together effectively. Instead of keeping risk and compliance departments isolated, they encourage shared responsibility across product, engineering, and operations. This steady collaboration ensures that regulatory readiness becomes a natural part of daily work and helps maintain a consistent customer experience. Finally, businesses expand their available resources by adopting a flexible approach that includes building, buying, and partnering for new tools. In highly regulated fields, partnering with established experts can reduce risks and prevent companies from wasting time recreating existing capabilities. By making governance a core part of their daily strategy, organizations can confidently adapt to new technologies, rising customer expectations, and shifting rules, building lasting resilience from the ground up.


The Problem Is Prompt Debt

The article outlines the growing challenge of "prompt debt," a concept that directly mirrors technical debt in traditional software development. As engineers increasingly rely on artificial intelligence language models to build features, they often construct complex and highly specific instructions to force these systems to produce the exact desired output. While this approach solves immediate problems and gets applications running quickly, it ultimately creates a significant long-term maintenance burden. The main issue is that these intricate instructions are deeply tied to a specific version of a model. When the underlying model receives an update or is swapped out for a different system, the previously reliable instructions tend to break or perform poorly, forcing teams to start over entirely. The author explains that we are essentially writing a new kind of code, yet we lack the mature testing environments, debugging tools, and version control methods that standard programming currently enjoys. To get ahead of this problem, development teams must start treating their instructions as formal software components rather than quick fixes. This means prioritizing simplicity over clever hacks, building reliable evaluation systems, and maintaining clear records of changes. Managing this new form of debt requires adopting disciplined engineering habits before the ongoing maintenance cost becomes completely unmanageable.


Timeless Compliance: Why Better Questions Beat Bigger Frameworks

In his article, Matt Honea argues that effective AI compliance programs should abandon massive, convoluted frameworks in favor of concise, targeted checklists. Much like the proven success of surgical and pre-flight checklists, a highly focused set of questions yields far better results than hundreds of broad inquiries that merely invite creative writing from vendors. While major frameworks like the EU AI Act, NIST, and ISO 42001 provide solid foundational guidelines, they often translate poorly into bloated vendor assessments that fail to measure actual risk or scale appropriately. To build a truly timeless compliance strategy, organizations must ensure their questions are directly answerable with concrete evidence, such as system logs, configurations, and formal evaluation reports. These questions should be strictly scoped to the specific system's risk tier, objectively measurable, and directly relevant to actual business decisions. Honea suggests that standardizing an industry-wide model card – a consistent schema detailing model versioning, data retention policies, performance benchmarks, and inference parameters – could streamline this entire process, similar to how SOC 2 standardized security reporting. Ultimately, robust AI compliance remains an observability challenge. By prioritizing clear evidence, continuous measurement, and a firm understanding of system mechanics over performative paperwork, companies can create lasting programs that adapt easily to regulatory shifts.


The post-quantum mandate isn't about algorithms, it's about operational trust

Many organizations mistakenly view the upcoming shift to post-quantum cryptography simply as a task of swapping out old algorithms for new ones. However, recent regulatory changes and finalized standards highlight that this transition is fundamentally about securing long-term operational trust. Adversaries are already intercepting sensitive information with the intention of decrypting it once quantum computing technology matures. As a result, businesses cannot afford to wait for hardware to catch up before addressing their vulnerabilities. The core challenge lies not in picking the correct mathematical formulas, but in managing millions of digital certificates, cryptographic keys, and device identities across a complex enterprise. This requires a continuous lifecycle management approach. Organizations must first gain clear visibility into their current cryptographic assets to understand exactly where and how these tools are deployed. Once mapped, companies need to prioritize updating systems that handle long-term data, embedded hardware, and critical infrastructure. True readiness involves building a flexible environment capable of adapting to new standards without causing operational disruptions. Moving forward, the most resilient organizations will be those that move past static security checklists. By establishing continuous oversight of their trust mechanisms from basic hardware up through complex cloud systems, businesses can confidently navigate the post-quantum landscape.


Beyond the password: Why behavioral biometrics is becoming banking’s last line of defense

Account takeover fraud remains a growing threat to the financial industry, despite the widespread use of traditional login methods like passwords and multi-factor authentication. These standard security measures check if someone has the correct login details, but they cannot verify if the person using those details is the actual account owner. To address this blind spot, banks are increasingly turning to behavioral biometrics as an essential layer of defense. Rather than just checking credentials at the front door, behavioral biometrics continuously monitors how a person interacts with their account during a session. By analyzing distinct habits such as typing speed, mouse movements, and navigation patterns, the system establishes a baseline for legitimate users. If a fraudster gains access using stolen information, their behavior will immediately stand out as unusual, allowing the system to detect the intrusion well before any money is transferred. Financial institutions are heavily investing in this technology, recognizing the need to shift from a single login checkpoint to a continuous verification process. At the same time, experts note that the artificial intelligence systems powering these fraud detection efforts must also be protected from direct attacks. Ultimately, analyzing human behavior offers a critical, proactive approach to securing our global financial infrastructure against modern criminals.


Why Technology Strategy Now Matters More Than Technology Spending

For years, companies believed that bigger technology budgets automatically led to better business results. However, simply spending more money on software and infrastructure often results in duplicated systems, rising costs, and unnecessary complexity. Today, success depends far more on a clear technology strategy than on the overall size of the budget. Technology is no longer just a support function for departments like finance or human resources; it is a core business capability that shapes how a company operates and competes. Instead of buying isolated software to fix individual problems, organizations are now building extended plans that directly support their main goals. Every investment should advance a specific business objective, such as improving daily operations or preparing for artificial intelligence. In fact, effective artificial intelligence deployment requires strong foundational strategies, including reliable data and organized processes, rather than just rapid spending. Furthermore, a key part of modern technology strategy is simplification. By reducing overlapping systems and standardizing platforms, companies lower maintenance costs and improve flexibility. Strong governance ensures that every new tool aligns with the broader company framework. Ultimately, businesses achieve true agility and lasting value when their technology decisions are guided by a unified strategy rather than isolated spending habits.

Daily Tech Digest - May 07, 2026


Quote for the day:

"You learn more from failure than from success. Don't let it stop you. Failure builds character." -- Unknown

🎧 Listen to this digest on YouTube Music

▶ Play Audio Digest

Duration: 21 mins • Perfect for listening on the go.


Designing front-end systems for cloud failure

In the InfoWorld article "Designing front-end systems for cloud failure," Niharika Pujari argues that frontend resilience is a critical yet often overlooked aspect of engineering. Since cloud infrastructure depends on numerous moving parts, failures are frequently partial rather than absolute, manifesting as temporary network instability or slow downstream services. To maintain a usable and calm user experience during these hiccups, developers should adopt a strategy of graceful degradation. This begins with distinguishing between critical features, which are essential for core tasks, and non-critical components that provide extra richness. When non-essential features fail, the interface should isolate these issues—perhaps by hiding sections or displaying cached data—to prevent a total system outage. Technical implementation involves employing controlled retries with exponential backoff and jitter to manage transient errors without overwhelming the backend. Additionally, protecting user work in form-heavy workflows is vital for maintaining trust. Effective failure handling also requires a shift in communication; specific, reassuring error messages that explain what still works and provide a clear recovery path are far superior to generic "something went wrong" alerts. Ultimately, resilient frontend design focuses on isolating failures, rendering partial content, and ensuring that the interface remains functional and informative even when underlying cloud dependencies falter.


Scaling AI into production is forcing a rethink of enterprise infrastructure

The article "Scaling AI into production is forcing a rethink of enterprise infrastructure" explores the critical shift from AI experimentation to large-scale deployment across real business environments. As organizations move beyond proofs of concept, Nutanix executives Tarkan Maner and Thomas Cornely argue that the emergence of agentic AI is a primary driver of this transformation. Agentic systems introduce complex, autonomous, multi-step workflows that traditional infrastructures are often unequipped to handle efficiently. These sophisticated agents require real-time orchestration and secure, on-premises data access to protect sensitive enterprise information. While many organizations initially utilized the public cloud for rapid experimentation, the transition to production highlights serious concerns regarding ongoing cost, strict governance, and data control, prompting a significant shift toward private or hybrid environments. The article emphasizes that AI is designed to augment human capability rather than replace it, seeking a harmonious integration between human decision-making and automated agentic workflows. Practical applications are already emerging across various sectors, from retail’s cashier-less checkouts and targeted marketing to healthcare’s remote diagnostic tools. Ultimately, scaling AI successfully necessitates a foundational rethink of how modern enterprises coordinate their underlying infrastructure, data, and security protocols to support unpredictable workloads while maintaining overall operational stability and long-term cost efficiency.


Why ransomware attacks succeed even when backups exist

The BleepingComputer article "Why ransomware attacks succeed even when backups exist" explains that modern ransomware operations have evolved into sophisticated campaigns that systematically target and destroy an organization's backup infrastructure before deploying encryption. Rather than just locking files, attackers follow a predictable sequence: gaining initial access, stealing administrative credentials, moving laterally across the network, and then identifying and deleting backups. This includes wiping Volume Shadow Copies, hypervisor snapshots, and cloud repositories to ensure no easy recovery path remains. Several common organizational failures contribute to this vulnerability, such as the lack of network isolation between production and backup environments, weak access controls like shared admin credentials or missing multi-factor authentication, and the absence of immutable (WORM) storage. Furthermore, many organizations suffer from untested recovery processes or siloed security tools that fail to detect attacks on backup systems. To combat these threats, the article emphasizes the necessity of integrated cyber protection, featuring immutable backups with enforced retention locks, dedicated credentials, and continuous monitoring. By neutralizing the traditional "safety net" of backups, ransomware gangs effectively force victims into paying ransoms. This strategic shift highlights that basic, unprotected backups are no longer sufficient in the face of modern, targeted ransomware tactics.


Document as Evidence vs. Data Source: Industrial AI Governance

In the article "Document as Evidence vs. Data Source: Industrial AI Governance," Anthony Vigliotti highlights a critical distinction in how organizations manage information for industrial AI. Most current programs utilize a "data source" model, where documents are treated as raw material; data is extracted, and the original document is archived or orphaned. This terminal approach severs the link between data and its context, creating significant governance risks, particularly in brownfield manufacturing where legacy records carry decades of operational history. Conversely, the "evidence" model treats documents as permanent artifacts with ongoing legal and operational standing. This framework ensures documents are preserved with high fidelity, validated before downstream use, and permanently linked to any derived data through a navigable citation trail. By adopting an evidence-based posture, organizations can build a robust "Accuracy and Trust Layer" that makes AI-driven decisions defensible and auditable. This is essential for safety-critical operations and regulatory compliance, where being able to prove the provenance of data is as vital as the accuracy of the AI output itself. Transitioning from a throughput-focused extraction mindset to one centered on trust allows industrial enterprises to scale AI safely while mitigating the long-term governance debt associated with disconnected data silos.


Method for stress-testing cloud computing algorithms helps avoid network failures

Researchers at MIT have developed a groundbreaking method called MetaEase to stress-test cloud computing algorithms, helping prevent large-scale network failures and service outages that impact millions of users. In massive cloud environments, engineers often rely on "heuristics"—simplified shortcut algorithms that route data quickly but can unexpectedly break down under unusual traffic patterns or sudden demand spikes. Traditionally, stress-testing these heuristics involved manual, time-consuming simulations using human-designed test cases, which frequently missed critical "blind spots" where the algorithm might fail. MetaEase revolutionizes this evaluation process by utilizing symbolic execution to analyze an algorithm’s source code directly. By mapping out every decision point within the code, the tool automatically searches for and identifies worst-case scenarios where performance gaps and underperformance are most significant. This automated approach allows engineers to proactively catch potential failure modes before deployment without requiring complex mathematical reformulations or extensive manual labor. Beyond standard networking tasks, the researchers highlight MetaEase’s potential for auditing risks associated with AI-generated code, ensuring these systems remain resilient under unpredictable real-world conditions. In comparative experiments, this technique identified more severe performance failures more efficiently than existing state-of-the-art methods. Moving forward, the team aims to enhance MetaEase’s scalability and versatility to process more complex data types and applications.


Hacker Conversations: Joey Melo on Hacking AI

In the SecurityWeek article "Hacker Conversations: Joey Melo on Hacking AI," Principal Security Researcher Joey Melo shares his journey and methodology within the evolving field of artificial intelligence red teaming. Melo, who developed a passion for manipulating software environments through childhood gaming, now applies that curiosity to "jailbreaking" and "data poisoning" AI models. Unlike traditional penetration testing, AI red teaming focuses on bypassing sophisticated guardrails without altering source code. Melo describes jailbreaking as a process of "liberating" bots via complex context manipulation—such as tricking an LLM into believing it is operating in a future where current restrictions no longer apply. Furthermore, he explores data poisoning, where researchers test if models can be influenced by malicious prompt ingestion or untrustworthy web scraping. Despite possessing the skills to exploit these vulnerabilities for personal gain, Melo emphasizes a commitment to ethical, responsible disclosure. He views his work as a vital contribution to an ongoing "cat-and-mouse game" aimed at hardening machine learning defenses against increasingly creative threats. Ultimately, Melo believes that while AI security will continue to improve, the constant evolution of technology ensures that red teaming will remain a necessary, creative endeavor to identify and mitigate emerging risks.


Global Push for Digital KYC Faces a Trust Problem

The global movement toward digital Know Your Customer (KYC) frameworks is gaining significant momentum, as evidenced by the United Arab Emirates’ recent launch of a standardized national platform designed to streamline onboarding and bolster anti-money laundering efforts. While domestic systems are becoming increasingly sophisticated, the concept of portable, cross-border KYC remains largely elusive due to a fundamental lack of trust between international regulators. Governments and financial institutions are eager to reduce duplication and speed up compliance processes to match the rapid growth of instant payments and digital banking. However, significant hurdles persist because KYC extends beyond simple identity verification to include complex assessments of ownership structures and risk profiles, which are heavily influenced by local market contexts and legal frameworks. National regulators often prioritize sovereign control and data protection, making them hesitant to rely on third-party verification performed in different jurisdictions. Consequently, even when countries share broad anti-money laundering goals, their divergent definitions of adequate due diligence and monitoring requirements create a fragmented landscape. Ultimately, the transition to a unified digital identity ecosystem depends less on technological innovation and more on establishing mutual recognition and trust among global supervisory bodies, ensuring that sensitive identity data can be securely and reliably shared across borders.


How To Ensure Business Continuity in the Midst of IT Disaster Recovery

The content provided by the Disaster Recovery Journal (DRJ) at the specified URL serves as a foundational guide for professionals navigating the complexities of organizational stability through the lens of business continuity (BC) and disaster recovery (DR) planning. The material emphasizes that while these two disciplines are closely interconnected, they serve distinct roles in safeguarding an organization. Business continuity is presented as a holistic, high-level strategy focused on maintaining essential operations across all departments during a crisis, ensuring that personnel, facilities, and processes remain functional. In contrast, disaster recovery is defined as a specialized technical subset of BC, primarily concerned with the restoration of information technology systems, critical data, and infrastructure following a disruptive event. A primary theme of the planning process is the requirement for a structured lifecycle, which begins with a rigorous Business Impact Analysis (BIA) and Risk Assessment to identify vulnerabilities and prioritize critical functions. By defining clear Recovery Time Objectives (RTO) and Recovery Point Objectives (RPO), organizations can create targeted response strategies that minimize operational downtime. Furthermore, the resource highlights that modern planning must evolve to address contemporary challenges, such as cyber threats, hybrid work environments, and artificial intelligence integration. Regular testing, cross-functional collaboration, and plan maintenance are essential to transform static documentation into a dynamic, resilient framework capable of withstanding diverse disasters.


The Agentic AI Challenge: Solve for Both Efficiency and Trust

According to the article from The Financial Brand, agentic artificial intelligence represents the next inevitable evolution in banking, marking a fundamental shift from reactive generative AI chatbots to autonomous, proactive systems. While nearly all financial institutions are currently exploring agentic technology, a significant "execution gap" persists; most organizations remain stuck in the pilot phase due to legacy infrastructure, fragmented data silos, and outdated governance frameworks. Unlike traditional AI that merely offers recommendations, agentic systems are designed to act—executing complex workflows, coordinating multi-step transactions, and managing customer financial health in real time with minimal human intervention. The report emphasizes that while banks have historically prioritized low-value applications like back-office automation and fraud prevention, the true potential of agentic AI lies in fulfilling broader ambitions for hyper-personalization and revenue growth. As fintech competitors increasingly rebuild their transaction stacks for real-time execution and autonomous validation, traditional banks face a critical strategic choice. They must modernize their leadership mindset and core technical architecture to support the "self-driving bank" model or risk being permanently outpaced. Ultimately, embracing agentic AI is not merely a technological upgrade but a necessary structural evolution required for banks to remain competitive in an increasingly automated financial ecosystem.


Multi-model AI is creating a routing headache for enterprises

According to F5’s 2026 State of Application Strategy Report, enterprises are rapidly transitioning AI inference into core production environments, with 78% of organizations now operating their own inference services. As 77% of firms identify inference as their primary AI activity, the focus has shifted from experimentation to operational integration within hybrid multicloud infrastructures. Organizations currently manage or evaluate an average of seven distinct AI models, reflecting a diverse landscape where no single model fits every use case. This multi-model approach creates significant architectural complexities, turning AI delivery into a sophisticated traffic management challenge and AI security into a rigorous governance priority. Companies are increasingly adopting identity-aware infrastructure and centralized control planes to manage the routing, observability, and protection of inference workloads. To mitigate operational strain and rising costs, enterprises are integrating shared protection systems and cross-model observability tools. Furthermore, the convergence of AI delivery and security around inference highlights the necessity of managing multiple services to ensure availability and compliance. Ultimately, the report emphasizes that successful AI adoption depends on treating inference as a managed workload subject to the same delivery and resilience requirements as traditional enterprise applications, ensuring faster and safer operational execution.