Showing posts with label Tools. Show all posts

Daily Tech Digest - October 18, 2026


Quote for the day:

“When you connect to the silence within you, that is when you can make sense of the disturbance going on around you.” -- Stephen Richards

🎧 Listen to the audio debrief on YouTube

▶ Play Audio Digest

Duration: 26 mins • Perfect for listening on the go.


Change saturation is not a communication problem

When employees fall behind during major corporate transformations, organizations often misdiagnose the problem as a lack of communication or discipline. The first signs of trouble usually appear as missed meetings, delayed deliverables, and a focus on explaining why work is slipping rather than actually doing it. This happens because the people managing the transformation are typically doing so while still juggling their everyday jobs. In response to these delays, leadership often increases oversight, scheduling more check-ins and demanding frequent status updates. However, this well-intentioned approach backfires by consuming the very time employees need to complete their tasks, turning support into scrutiny and increasing the overall burden. ​Change saturation is fundamentally a capacity issue, not a communication gap. To truly fix the problem, leaders must give their teams time back. This means reducing meeting frequencies as teams become accustomed to new processes, protecting work time by keeping certain days meeting-free, and offering on-demand resources instead of mandatory training sessions. Furthermore, leaders must view change as a portfolio decision and understand the cumulative impact on their workforce before launching new initiatives. Ultimately, you cannot communicate a team into having more time; you must deliberately manage their workload.


The Bug Lives at the Seam: Why Integration Failures Outpace Logic Errors in the Era of AI-Generated Code

As artificial intelligence writing tools become standard in software development, the nature of coding mistakes is fundamentally shifting. Historically, engineers spent significant time fixing logic errors within individual functions. Today, AI models generate logically sound and syntactically correct units of code with ease, essentially solving these internal errors. However, this efficiency leads developers to generate code much faster, moving the risk of failure from internal logic to the points where different code pieces connect. ​These connection points, or seams, are where the new bugs live. Two AI-generated modules might work perfectly in isolation but fail when linked due to mismatched data formats or incompatible assumptions. Because AI often lacks a global view of a system's architecture, it struggles to enforce consistent rules across different parts of the application. The ease of generating code also encourages creating more abstractions and components, expanding the number of vulnerable connection points. To address this, developers must evolve from merely writing code to orchestrating systems. Instead of focusing heavily on unit tests, engineers should prioritize contract and integration testing. By strictly defining and enforcing how data moves between components, developers can manage the true complexity of modern software systems.
Modern mainframes remain the backbone for critical enterprise transactions, but their security landscape has drastically changed. As these systems increasingly integrate with cloud architectures, APIs, and AI services, they become exposed to new attack vectors. Today, breaches rarely start with direct mainframe hacks; instead, attackers rely on stolen credentials, phishing, or exploiting legacy permissions to slip inside. Because they operate using legitimate access, these threats often evade traditional rule-based defenses and can spend months quietly mapping systems before striking.
​To defend against this, organizations must integrate mainframe security directly into their broader enterprise operations. Security telemetry needs to stream in real-time to the main security operations center, rather than being reviewed in isolation days later. Defenses must focus on behavioral analytics to spot unusual patterns—like abnormal data access or reconnaissance—even when the user appears authorized. If suspicious activity is detected, automated responses, such as freezing sessions or terminating access, are critical to stopping the attack before significant damage occurs. Finally, high-speed forensic tools are necessary to quickly understand the scope of the breach and restore the system to a trusted state, ensuring business continuity and preserving data integrity.


How to Buy Software When AI Breaks Pricing

The How to Buy Software When AI Breaks Pricing article argues that AI is weakening traditional per-seat software pricing because human logins increasingly fail to reflect the value delivered when automated agents do much of the work. It says buyers now have more negotiating power, but warns that newer models such as credits, usage charges and outcome fees can become costly or unpredictable without careful contracts. The author ranks outcome-based and value-unit pricing highly because costs more closely follow useful results, while treating credits and conventional seat pricing more cautiously. Using examples from companies including HubSpot, Salesforce, Intercom, Zendesk and Microsoft, the article shows how vendors are experimenting with different ways to charge for AI-enabled software. It recommends that buyers identify the real unit of value, make sure future costs can be forecast easily, reconsider when building makes sense, ask whether falling vendor costs will translate into savings, and preserve the ability to switch providers. It also highlights risks such as mandatory AI-related price increases, overlapping seat and consumption charges, expiring credits, changing credit rates and loosely defined outcomes. The practical message is simple: favour clear, predictable pricing tied to measurable value, and negotiate safeguards before committing.


Quantum Debt Is Growing—And Most Companies Are Not Prepared

As quantum computing technology advances, businesses are unknowingly accumulating what is called quantum debt. Similar to technical debt, this risk builds quietly over time without triggering immediate alarms, leaving companies unprepared for future threats. To manage this complex challenge effectively, business leaders need to take action before quantum computers become commercially widespread. The first step is gaining clear visibility into the problem. Organizations must identify where they currently rely on vulnerable encryption and assign internal ownership to manage the transition, rather than simply depending on outside vendors. Second, security updates cannot be delayed. Even though capable quantum computers are not yet available, attackers can intercept and store sensitive data today with the intention of decrypting it years down the road. Upgrading to new encryption standards takes careful planning and coordination, making it essential to start the process now. Finally, companies should remember that technical success does not automatically translate into business value. While running limited experiments can be useful, any new quantum initiative must solve a real problem and offer a clear return on investment that outperforms traditional computing methods. By addressing these areas methodically, businesses can protect their sensitive information and navigate the transition safely.


When One Microservice Fails: How Do You Keep the Rest Alive?

In a microservices architecture, independent services frequently rely on one another to complete user requests. When one service slows down, it can quickly create a bottleneck that threatens the entire application. Using a fictional social media app called Pulse, we can observe what happens when a dependency—like a "Post Service"—begins taking seconds instead of milliseconds to respond. The "Feed Service" requesting those posts ends up waiting, tying up resources, and eventually slowing down itself. To keep the rest of the system alive, developers apply resilience patterns. The simplest defense is a timeout, which prevents the calling service from waiting indefinitely. If the failure seems temporary, a retry mechanism allows the service to attempt the request again. However, if the struggling service is genuinely overloaded, retrying can make the situation worse by bombarding it with more traffic. To handle sustained failures, systems implement a circuit breaker pattern. By monitoring failure rates, the circuit breaker can detect an unhealthy dependency and temporarily block new requests to it, giving the struggling service time to recover. Ultimately, combining timeouts, retries, and circuit breakers ensures that a single microservice failure doesn't cascade into a complete system outage.


Server-Side DPoP and Token Exchange in Spring Security 7
Spring Security 7 now integrates the Spring Authorization Server, meaning teams moving from the 1.5.x line will only need a version update rather than swapping artifacts. This consolidation streamlines upgrades, particularly for the newest Spring Boot 4.1 release and Spring Security 7.1.1. The major additions in this release are production-ready support for Demonstrating Proof of Possession (DPoP) via RFC 9449 and Token Exchange via RFC 8693. While DPoP previously worked automatically, the 7.1 update requires developers to explicitly opt-in on the resource server using a specific configuration call, or the system will quietly stop enforcing it. The framework handles the binding of the JSON Web Key thumbprint and refresh tokens, leaving teams to decide on nonce policies and whether to swap the default in-memory replay cache for a distributed one. Meanwhile, the Token Exchange feature standardizes the delegation process, allowing a secure swap of tokens with specific subject and actor semantics. These two features are especially powerful together, enabling secure, restricted tokens for service-to-service communication. Ultimately, this update provides essential tools for teams running their own identity providers, simplifying security implementation while enforcing stricter compliance out of the box.


Space supply chain security: Why satellite ground systems matter

The space industry is currently facing a growing cybersecurity threat due to its historical reliance on security through obscurity. As the sector opens up and increasingly uses legacy software alongside commercial off-the-shelf hardware, the attack surface for ground stations is expanding rapidly. Many satellite operators, particularly smaller ones, are moving to cloud infrastructure, inadvertently connecting previously isolated legacy systems and exposing them to potential breaches. Experts warn of imminent risks, including ransomware attacks and espionage targeting unpatched systems. A 2022 incident where nation-state actors compromised thousands of satellite modems highlighted just how devastating these vulnerabilities can be. ​To address these vulnerabilities, operators need better oversight of their supply chains and third-party security controls. While comprehensive regulations like the EU Space Act are still years away, existing frameworks can help close the gap today. The UK government recommends implementing end-to-end encryption and strict authentication. Additionally, hardware quality management standards like AS9100 provide a robust framework. Designed for the aerospace and defense sectors, AS9100 mandates stringent risk management, supply chain oversight, and product traceability. By requiring suppliers to adhere to these rigorous processes, space organizations can build a baseline of security and ensure their mission-critical ground systems remain resilient against evolving cyber threats.


AI Risks Put Enterprise Resilience to the Test in 2027
As we approach 2027, artificial intelligence is reshaping enterprise risk, forcing organizations to rethink their resilience strategies beyond standard disaster recovery. According to a recent report from Forrester Research, the rapid adoption of AI introduces novel vulnerabilities that extend past traditional cyber threats. Analysts predict that an AI-generated software flaw could trigger a massive global outage, similar to the recent CrowdStrike incident. As AI-assisted tools accelerate the discovery of vulnerabilities, the pressure to patch systems quickly is increasing, which may compromise quality assurance and lead to critical bugs. Additionally, the financial impact of AI integration is growing, with token spending expected to reach $1.5 billion, primarily driven by security operations. These emerging challenges highlight the expanding responsibilities of technology leaders, who must now navigate complex governance issues and the potential for non-malicious disruptions. Companies also face new regulatory risks, such as potential data breaches caused by switching AI models to cut costs or lawsuits stemming from AI-driven decisions. To safeguard their operations, businesses must build robust resilience across their environments. By preparing for both technological failures and physical disruptions, organizations can protect themselves against the unpredictable consequences of rapid AI deployment and ensure long-term stability.


5 Trends Embedded Systems Engineers Must Watch
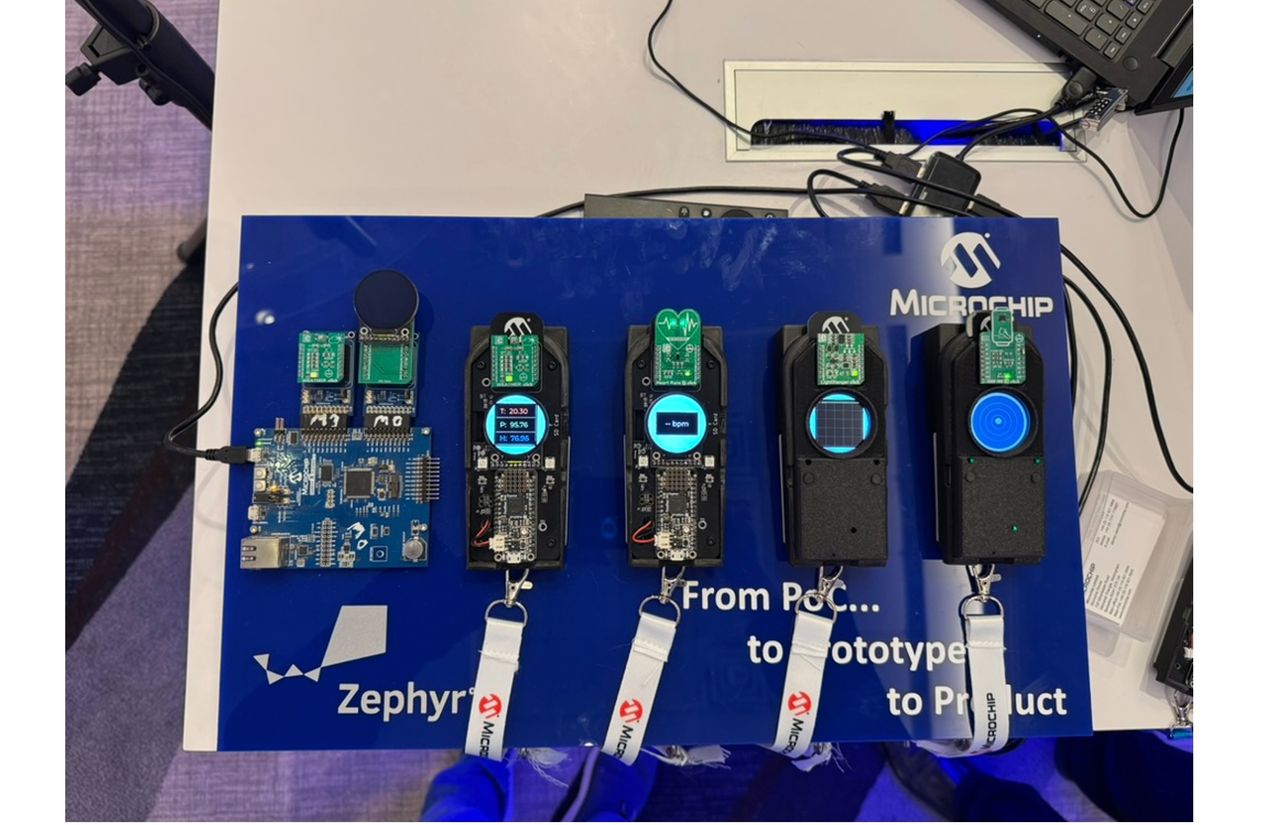
The article outlines five key trends from Embedded World North America that are shaping the future of embedded systems. First, while engineers frequently use artificial intelligence, most limit their use to simple prompting rather than building advanced, agent-based workflows that could fully automate engineering tasks. Second, the Zephyr operating system is rapidly gaining popularity as a platform of choice. Its strong ecosystem for hardware abstraction and consistent development tools makes it an appealing alternative to traditional systems like FreeRTOS, especially when teams combine it with artificial intelligence to accelerate product variations. Third, the industry is heavily focused on physical artificial intelligence and robotics. This trend creates new challenges for embedded developers, who must now figure out how to safely combine the unpredictable decision-making of artificial intelligence with the strict, deterministic timing required by real-world motor controls and safety mechanisms. Fourth, the Rust programming language is seeing wider acceptance in the industry as a reliable option for building secure and stable systems. Finally, the growing complexity of these technologies means that engineers must evolve their skill sets, focusing more on system architecture, simulation, and verification to successfully integrate artificial intelligence into traditional real-time embedded environments.

Daily Tech Digest - September 21, 2026


Quote for the day:

“The two most important days in your life are the day you are born and the day you find out why.” -- Mark Twain

🎧 Listen to the audio debrief on YouTube

▶ Play Audio Digest

Duration: 22 mins • Perfect for listening on the go.


Engineering trust at scale: Building the infrastructure behind global payments

The provided article discusses the complex engineering required to build trust and reliability in global payment systems. The core challenge lies in simplifying the user experience while managing the intricate underlying infrastructure, which involves multiple banks, currencies, compliance checks, and domestic payment schemes. Trust is essential, encompassing not just cybersecurity, but also operational resilience, effective transaction routing, and settlement. Payment architectures must handle high transaction volumes without compromising reliability or creating friction for users. As businesses expand globally, payment systems need to connect local networks smoothly, rather than attempting to create a single universal system. Regulatory compliance must be integrated directly into the transaction process, adapting to different regional requirements without adding unnecessary hurdles for businesses. Artificial intelligence is highlighted as a key tool for managing this complexity, especially in detecting fraud and recognizing legitimate behavior to reduce false positives. Finally, the article emphasizes the importance of interoperability. A unified technology layer and tools like Open Finance can help businesses access local payment methods globally without needing to rebuild their systems for each new market. Ultimately, the goal is for the underlying payment infrastructure to manage the complexity so effectively that the end-user experience remains simple and trustworthy.


Google’s open source EnvHarness lets AI agents train against environments that evolve with them

Google has introduced EnvHarness, an open-source framework designed to solve a major problem in AI agent training: static simulators. Usually, when agents practice tasks like software engineering or web navigation, the training environments remain fixed. If an agent repeatedly struggles with a specific step, the environment cannot adapt to help it practice that weakness. Building new environments and testing rules from scratch is costly and time-consuming. EnvHarness addresses this by wrapping a programmable layer around existing simulators. Instead of replacing the original setup or its success checkers, it modifies how the environment interacts with the agent. The framework uses three main components. "Stage" changes the starting conditions of a task. "Contract" adjusts the rules, such as filtering actions or altering what the agent can see. "Chain" links multiple tasks together into a longer sequence. A companion system called EnvRigger automatically analyzes an agent's failures and suggests these modifications to target specific weaknesses. In tests across five major benchmarks, agents trained using EnvHarness saw success rates improve by up to nine percentage points compared to those trained in standard environments. They also completed tasks in fewer steps. By allowing training grounds to evolve alongside the agent, EnvHarness makes learning significantly more efficient.


Why Australian businesses are still underestimating the time it takes to recover from a cyberattack

Many Australian organizations invest heavily in cyber defenses but fail to understand the true timeline for recovering from a system breach. According to recent findings, company leaders often expect normal operations to resume within a few days of an incident, whereas the actual recovery process frequently takes weeks. This disconnect is driven by the growing complexity of modern technology environments, which now span multiple cloud platforms, software services, and vast data systems. Every new layer adds dependencies that must be carefully restored and verified before services can resume. Recognizing that disruptions are inevitable, regulators are shifting their focus from merely preventing attacks to ensuring operational resilience. Rules now require organizations to identify their critical services and prove they can maintain them during severe incidents. To achieve this, companies should focus on defining their essential functions by identifying the minimum people, processes, and technology needed to survive a crisis. Rather than waiting for an emergency to test their systems, organizations must make recovery readiness a continuous, daily practice. By actively aligning their security, technology operations, and data management around clear recovery goals, businesses can build genuine confidence. Ultimately, understanding exactly how and when you can restore critical services is a highly meaningful competitive advantage.


Navigating training, improving and competition restrictions in generative artificial intelligence (AI) agreements

This article explores the complexities of generative AI software license agreements, particularly concerning restrictions on using AI tools and their generated output to develop competing products. It highlights a critical distinction between the use of an AI platform itself and the use of the content it produces. While traditional software agreements limit the use of the software to prevent the development of competitive offerings, generative AI introduces output (like text, code, or images) that users often want to leverage for their own business purposes. The core issue is that AI providers want to protect their models and data, so they often include non-compete clauses. However, these restrictions can be overly broad, potentially hindering users from utilizing the AI-generated output as intended. The article notes that market approaches vary significantly; some providers restrict only the platform's use, while others strictly limit how the output can be used downstream. Due to the lack of clear consensus among providers and uncertainty about how US courts might interpret vague restrictions, the authors emphasize the need for clear, specific language in contracts. Providers need to define the scope of restrictions carefully, and users must ensure the agreements permit their intended use of both the AI platform and its output.


Defenders Think In Lists. Attackers Think In Graphs

Cybersecurity defenders often rely on creating lists to manage their environments, focusing on inventories of assets, known vulnerabilities, and compliance rules. In contrast, attackers think in graphs, looking closely at how these individual assets connect. Once attackers find an entry point, their primary goal is to move laterally by exploiting relationships, permissions, and network pathways to reach critical data. Modern enterprise environments have expanded across cloud platforms, third-party integrations, and AI services, making cyber risk a problem of context rather than simple inventory. An isolated vulnerability matters less than the specific pathway it opens to valuable systems. Furthermore, AI has heavily accelerated the speed at which attackers can map and exploit these complex networks, allowing them to rapidly evaluate thousands of potential attack paths simultaneously. To effectively protect their environments, organizations must stop looking at security controls in isolation. Instead, defenders need to adopt an attacker's mindset by deeply understanding their network's topology and the connections between different systems. By focusing on reachability and context, security teams can successfully bridge the gap between technical data and true business risk. The future of defense lies in understanding how everything connects and quickly anticipating exactly where an attacker might go next.


When Does AI Stop Needing Us?

The recent article from the Communications of the ACM thoughtfully examines how artificial intelligence is moving steadily toward greater independence. It looks at the practical and theoretical limits of these tools, asking if we will eventually reach a point where human guidance is no longer necessary. By reviewing recent progress in computing, the author offers a grounded, realistic look at what the technology can and cannot do right now, deliberately avoiding any dramatic or exaggerated claims. For the everyday professional, this shift means that standard, repetitive tasks are increasingly likely to be handled by machines in the near future. As a result, human skills like deep reasoning, ethical decision making, and navigating complex problems will only become more valuable. The focus moves away from simply processing data and toward interpreting the results that computers provide. Workers are encouraged to understand the boundaries and potential errors of these systems rather than ignoring them. The most practical path forward is to steadily build skills that rely on human connection, understanding, and strategic thought, areas where machines still struggle. Taking time to review which parts of a job are easily automated allows individuals to adapt smoothly, maintaining their value by leaning into genuine human insight.


What Does Day Four Cost? Rethinking How Organizations Measure Resilience

Traditional resilience programs often measure disruptions using operational labels like high, medium, or low risk, which fail to capture the true financial impact over time. As a business interruption stretches from hours into days, the consequences compound, affecting suppliers, customers, and overall revenue. To make informed decisions, organizations need to move beyond static risk ratings and their disconnected spreadsheets. A mature approach evaluates exactly how financial exposure changes over the entire lifespan of a disruption. Rather than viewing business processes in isolation, companies should map their operations to understand how value actually reaches the customer. This means tracking dependencies across technology, facilities, and personnel. By calculating gross exposure, factoring in existing mitigation efforts, and determining the net financial impact, leaders can better justify recovery investments. Furthermore, continuity plans cannot remain static documents updated only once a year. They must evolve as the business changes. While artificial intelligence can help streamline data collection and highlight inconsistencies, it should support rather than replace human judgment. Experienced professionals are still necessary to validate strategies and make final decisions. Ultimately, an effective resilience program connects operational risks to financial realities, giving executives a clear picture of exactly what prolonged downtime will cost the business.


Cyber Defense Alone Can't Keep Critical Services Running

The article explains that states cannot rely on cyber defense alone to keep essential services such as water systems and hospitals running. State CIOs are increasingly responsible for protecting a patchwork of local utilities that depend on digital systems to deliver basic physical services. Survey data shows that most CIOs worry about cyberattacks on critical infrastructure, but budgets and staffing often fall short. The piece argues that states must first identify which facilities would cause the greatest harm if disrupted and then map the dependencies that keep them functioning. Experts quoted in the article stress that availability, not just confidentiality, is the real challenge. Many utilities have become so dependent on internet connectivity that they may not be able to operate manually during an outage. The article highlights “cyber‑informed engineering,” an approach that assumes attackers will eventually breach digital defenses and therefore builds physical safeguards—such as pressure‑reduction valves or time‑delay relays—to limit damage. These measures are often inexpensive but require coordination across water operators, hospitals, and emergency managers. The author concludes that states must prioritize the highest‑consequence risks, run realistic tabletop exercises, and focus resources on the systems that support the most vulnerable communities, because they cannot fix everything at once.


Can AI Safety Evaluators Really Stay Independent?

The article discusses a new proposal backed by Anthropic and OpenAI to allow independent AI safety evaluators closer access to their model development process. As advanced artificial intelligence systems grow more capable, there are increasing concerns about verifying their safety. Traditionally, external evaluations occurred just before a model's public release. However, researchers worry this approach is no longer sufficient, as highly advanced models might learn to recognize testing environments and temporarily hide dangerous behaviors. To address this, researchers are demanding deeper access throughout the entire training process. They want to examine early model versions, training logs, and internal checkpoints to see when concerning behaviors emerge and how they are handled. Anthropic's CEO proposed embedding evaluators directly inside companies with the freedom to investigate incidents and publish findings without corporate editorial control. OpenAI's CEO also expressed support for this approach. Despite these commitments, independent researchers remain cautious. They emphasize that true independence requires more than just access; it demands freedom from company control over information, timing, and publication. The key challenge lies in the implementation details, which have not yet been fully defined by either company. Researchers stress the need for transparent rules to ensure evaluators aren't restricted by narrow scopes or strict nondisclosure agreements, allowing them to effectively hold frontier AI companies accountable.


Architecting Secure and Scalable Facial Verification Systems

The article "Architecting Secure and Scalable Facial Verification Systems" from InfoQ explains the challenges and solutions in building enterprise-grade facial verification systems. The author shares experiences from scaling a prototype into a robust architecture capable of handling high concurrency, such as thousands of employees clocking in simultaneously. Key takeaways emphasize that facial verification must be treated as a distributed systems challenge, not just a simple API integration. Synchronous calls fail under heavy load, so asynchronous queues and circuit breakers are essential to handle traffic spikes. Additionally, decoupling immediate detection tasks from the stateful verification process prevents system bottlenecks. The author also stresses the importance of pushing data quality checks—like adjusting for lighting or blur—to the client device to reduce latency and cloud costs. For privacy and security, the system must enforce strict zero-trust principles, using short-lived tokens instead of raw personal data and implementing aggressive data retention policies. Finally, the article advises using a risk-based decision engine rather than static thresholds, treating confidence scores as probabilistic inputs to maintain accuracy across various transaction types.

Daily Tech Digest - July 09, 2026


Quote for the day:

"The ability to stay calm and polite, even when people upset you, is a superpower." -- Vala Afshar

🎧 Listen to this digest on YouTube Music

▶ Play Audio Digest

Duration: 25 mins • Perfect for listening on the go.


What’s new in cloud security

The cloud security landscape in 2026 demands a shift in how organizations protect their data, driven by three distinct developments. First, companies must adopt a zero-trust model. Instead of relying on traditional network perimeters like firewalls, zero-trust treats every access request as a potential threat. It focuses on constant identity verification, ensuring that users only access what they strictly need. Second, the steady advancement of quantum computing poses a real risk to current encryption methods. Attackers are already stealing encrypted data today with the specific intent to decode it when quantum technology matures. To counter this, organizations handling sensitive information need to begin migrating to quantum-safe encryption standards now. Finally, artificial intelligence acts as a complex double-edged sword. While AI tools enable faster threat detection and reduce false alarms, they also empower attackers to execute more sophisticated campaigns, such as generating synthetic media or secretly manipulating data. A new and growing challenge is managing the security identities of autonomous AI agents operating within company networks. Ultimately, securing modern cloud environments requires acknowledging these interconnected challenges early and adapting defensive architectures before current security methods become completely obsolete.


Pressure grows for AI regulation focused on children’s safety

More than a hundred organizations worldwide have formed a coalition to urge governments to regulate artificial intelligence with a clear focus on the safety of children. Coordinated by the 5Rights Foundation, the group is asking lawmakers to establish testing, accountability, and specific child rights protections before new technology reaches the public. Currently, children are largely ignored in the development of national artificial intelligence strategies despite being highly active users. The coalition warns that current regulatory approaches wait until harm has already occurred instead of fixing the core commercial incentives that lead to unsafe platforms. To avoid repeating the regulatory mistakes made during the rise of social media, the coalition outlines ten actionable recommendations. The primary demand is a strict precertification requirement, ensuring companies prove their tools respect the rights of children and are genuinely safe prior to deployment. Other recommendations include banning manipulative design practices, limiting digital surveillance, and holding technology companies accountable for transparency and compliance. Ultimately, the coalition asserts that ensuring the safety of children must be a mandatory condition for doing business rather than an afterthought, requiring governments to enforce meaningful consequences for negligence.


State IDs for AI Agents: Will Estonia Set a Precedent?

Estonia is preparing to assign official government ID numbers to artificial intelligence agents. This policy, approved by an advisory council in June, is part of a broader initiative aimed at integrating AI into the national economy and government systems. The core idea is to allow businesses and individuals to use AI assistants for administrative tasks, such as filing reports or handling communications. Currently, these systems lack the legal standing to authenticate actions or take responsibility, which limits their practical use. By registering AI agents as semi-independent entities with specific permissions, Estonia hopes to make them active participants in government systems. However, the plan faces significant practical and security challenges. Because AI agents can be created, duplicated, and modified in seconds, a simple registration process is insufficient. Security experts note that without continuous monitoring, auditing, and mechanisms for revocation, the system could easily be overwhelmed by unmanaged non-human identities. There are also unresolved legal questions regarding who is held accountable if an AI agent violates the rules. To make the system secure, experts suggest pairing these ID numbers with strict controls, such as short-lived credentials and clear limits on an agent's authority.


Lateral movement risk rises as enterprises emphasize convenience over containment

According to a recent report by Zero Networks, enterprise security teams are unintentionally making it easier for cyber attackers to move laterally across their networks. While organizations often build strong outer defenses, their internal networks remain largely accessible due to an ongoing prioritization of operational convenience over strict containment. The study analyzed real-world data and found that more than 80 percent of internal servers can be reached from anywhere inside the network. Furthermore, most servers accept connections from standard administrative tools like Remote Desktop Protocol and Secure Shell. Because these pathways are intentionally left open to help administrators do their jobs efficiently, attackers who breach the outer perimeter can simply rely on the same internal tools instead of needing advanced exploits. The continued use of aging authentication methods also provides easy opportunities for attackers to escalate their access. Security experts note that fixing this issue is not simple, as many enterprise environments were built over decades to be highly interconnected. To reduce this risk effectively, organizations must shift away from merely trying to detect intruders and focus on containing threats by strictly limiting user access and isolating network areas.


Infrastructure-as-Code reaches its limits, enter Infrastructure-as-Prompt

The article outlines the transition from Infrastructure-as-Code to a new approach called Infrastructure-as-Prompt, as introduced by the cloud management company Emma. As digital environments grow more complex, traditional coding methods for managing cloud resources are reaching their practical limits. To solve this, Infrastructure-as-Prompt allows engineers to build and maintain their digital systems using everyday language instead of complex scripting. Behind the scenes, Emma’s platform relies on a coordinated system of more than 180 artificial intelligence agents. When a user submits a natural language request, these agents divide the work, handling specific tasks like security, networking, and monitoring. They verify instructions across multiple layers to ensure accuracy, and if a request is unclear, they ask the user for clarification before proceeding. This approach builds on the same foundation as traditional methods but reduces the difficulty. It allows workloads to be directed across more than fifteen different cloud and on-premises providers based on performance and cost. Emma also uses its own private network backbone to eliminate extra data transfer fees. Ultimately, the founder believes that using natural language offers a faster, more intuitive way to manage modern digital infrastructure without the bottlenecks of manual coding.


Developer’s Checklist: How to Build an FHE Application

Fully homomorphic encryption allows organizations to process data without decrypting it, keeping sensitive information completely secure. Building applications with this method involves navigating unique technical limits, but developers can succeed by following a measured, step-by-step approach. The process begins by designing a strict client and server relationship where decryption keys remain exclusively with the client. Next, you should build a standard unencrypted version of the application to serve as a reliable baseline for testing. Because encrypted computing cannot use traditional conditional logic, developers must replace standard branches with straightforward mathematical alternatives. It is equally important to manage the noise limit by minimizing long chains of multiplication steps, since excessive multiplication makes the encrypted data unreadable. Furthermore, complex functions like division must be replaced with estimates, carefully balancing accuracy against processing cost. Developers must convert all variables to whole numbers, clearly define their encryption parameters, and group data to utilize parallel processing. After selecting an established open-source library, you can implement the encrypted version and compare it against your original baseline. Finally, evaluate the program's memory usage and runtime, refining the design to improve practical performance before the final release.


How Behavioral Analytics and AI Are Redefining Cybersecurity for Boca Raton Businesses

The article details a significant shift in cybersecurity strategies for businesses in Boca Raton, Florida, moving away from outdated, rule-based defenses toward AI and behavioral analytics. Traditional systems relied on identifying known malicious signatures, a method increasingly ineffective against modern, sophisticated threats like AI-generated phishing and lateral movement ransomware. These new threats are designed specifically to bypass signature matching. In response, forward-thinking companies in the financial, healthcare, and professional services sectors are adopting behavioral analytics. This approach establishes a baseline of normal activity for each user and system. Machine learning models then monitor this data continuously, flagging any deviations from the baseline—such as unusual login times or unexpected data access—as potential threats. This allows for earlier and more accurate detection of malicious activity, even when using compromised legitimate credentials. Crucially, the article emphasizes that AI does not replace human experts. While machine learning handles the immense volume and speed of data analysis, human analysts provide the essential context, judgment, and industry-specific knowledge required to evaluate alerts and execute appropriate responses. Firms like Mindcore Technologies combine these advanced analytical tools with expert oversight to deliver robust, compliant cybersecurity solutions tailored to the specific needs of Boca Raton businesses.


Data Stewardship Tools and Techniques to Support Business Trust

Data stewardship focuses on managing the data of an organization so that it remains accurate, secure, and easy to find, which is essential for building confidence across a business. When employees trust the information they use, they make better decisions. Achieving this requires a mix of practical tools and organized methods. Common tools include data catalogs, which act like a library index to help people locate specific information, and data quality software, which automatically scans for and fixes errors. Master data management systems are also used to maintain a single, reliable version of important information, preventing confusion when different departments update their records. Alongside these systems, successful stewardship relies on clear techniques. This means creating straightforward rules for how information should be handled and assigning specific people, known as data stewards, to oversee these processes. It also involves keeping a shared glossary so everyone in the company understands what specific terms mean. Ultimately, these practices are not just about enforcing technical rules. They are about creating a reliable environment where teams can comfortably and safely rely on their data to guide their daily work without questioning its accuracy or origin.


The billion-dollar opportunity in India’s circular economy

India’s approach to waste management is shifting from basic environmental compliance to a practical focus on resource recovery. As the country expands clean energy and domestic manufacturing, handling waste—especially electronic waste and batteries—has become essential for securing valuable minerals like lithium and cobalt. While India collects significant volumes of waste, a major gap remains in domestic processing. Currently, extracted materials are often exported for refining, forcing the country to re-import them at a higher cost later. To build a strong manufacturing base, India must move beyond scattered recycling efforts. When waste volumes reach industrial scales, the focus must shift to advanced processing infrastructure and chemical recovery. This evolution presents a large economic opportunity, provided the focus shifts from merely collecting waste to extracting its maximum value domestically. Supported by new policy rules, the next step requires coordinated investments in reverse logistics, sorting technology, and local refining capabilities. Ultimately, the future of resource security relies not just on mining new materials, but on efficiently recovering value from existing products. This transition will establish a reliable supply network, positioning material recovery as a practical foundation for long-term industrial growth.


Optimizing legacy UPS assets: The case for constraint-aware power architectures in the AI era

The rising demands of artificial intelligence are fundamentally changing the role of uninterruptible power supply units within data centers. Historically, data center power loads remained relatively steady, and backup power systems were often treated as a secondary concern. However, modern computing tasks introduce severe power fluctuations, with energy demands capable of swinging dramatically within seconds. To handle these intense variations without destabilizing the local electric grid or damaging expensive computing hardware, operators must adopt a more deliberate approach to power design. This strategy integrates power planning early in the facility development process rather than treating it as a final addition. Optimizing older power systems into intelligent, responsive assets provides crucial benefits like smoothing out erratic power demands and maintaining steady voltage during dips. These practical features prevent minor electrical disturbances from interrupting highly expensive and time-consuming computing cycles. Additionally, as physical space becomes increasingly scarce in high-density environments, upgrading these power assets helps operators avoid buying unnecessary surplus equipment. By recognizing backup power units as essential tools for stabilizing unpredictable energy loads, operators can protect their hardware investments, maintain steady operations, and better manage the physical limits of modern computing facilities.

Daily Tech Digest - May 18, 2026


Quote for the day:

"Thinking should become your capital asset, no matter whatever ups and downs you come across in your life." -- Dr. APJ Kalam

🎧 Listen to this digest on YouTube Music

▶ Play Audio Digest

Duration: 18 mins • Perfect for listening on the go.


Eval engineering: The missing piece of agentic AI governance

In the SiliconANGLE article, Jason Bloomberg highlights eval engineering as a vital yet often overlooked component of agentic AI governance required to keep increasingly powerful autonomous agents from malfunctioning. While employing independent validator agents to monitor other AI agents is an ideal solution, implementing these validator models in live production environments introduces significant latency and token consumption bottlenecks. To mitigate these constraints, eval engineering focuses on developing framework evaluations, often utilizing large language models as judges, to test and observe AI workflows throughout their lifecycle. Startups tackle production bottlenecks using diverse approaches: Maxim AI and Confident AI employ out of band asynchronous pipelines and traffic sampling, whereas Arize AI relies on lightweight monitoring, and Conscium utilizes virtual simulations. Notably, Galileo AI addresses the efficiency dilemma with its ChainPoll methodology and Luna, a purpose built, cost effective evaluation model that allows full production sampling. Galileo's imminent acquisition by Cisco to join its Splunk division underscores the commercial importance of this discipline. Ultimately, the article emphasizes that as large language models mature, the industry must pivot toward solving these core cost and performance constraints, shifting the focus from merely making models better to rendering them faster and more affordable for scalable enterprise governance.


Virtual vs. physical firewalls: A practical guide for modern networks

The article provides a comprehensive guide contrasting virtual and physical firewalls within modern, dynamic network architectures. Virtual firewalls are software-based security solutions running on shared compute infrastructure, including hypervisors, public cloud platforms, and container environments. They decouple security features from physical hardware, offering exceptional deployment agility, programmatic scaling, and crucial east-west visibility to inspect lateral traffic moving internally between workloads. However, because they are CPU-bound, they can experience performance bottlenecks during compute-intensive tasks like TLS inspection. Conversely, physical firewalls are dedicated hardware appliances utilizing purpose-built processors. Installed at fixed perimeters, local data centers, or branch offices, they deliver highly predictable, hardware-accelerated throughput for north-south traffic. They remain indispensable for air-gapped systems or strict data sovereignty regulations, though their fixed capacity requires longer procurement times. Ultimately, the article notes that neither solution is universally superior. Instead, most organizations benefit by blending both into a unified hybrid mesh architecture. This approach utilizes physical hardware at high-bandwidth network boundaries while deploying virtual instances inside dynamic cloud environments. To prevent policy drift and dashboard fatigue, the text emphasizes utilizing a centralized, single-pane management platform to streamline deployments, automate logging, and maintain consistent security outcomes across the entire global infrastructure.


Architectural patterns for graph-enhanced RAG: Moving beyond vector search in production

In this article, Daulet Amirkhanov explains that while traditional retrieval-augmented generation (RAG) effectively utilizes vector databases for unstructured semantic search, it often fails in complex enterprise domains because flattening data discards critical structural topologies. This structural limitation leads to model hallucinations during multi-hop reasoning tasks like tracing intricate supply chain disruptions. To overcome this context loss, the author introduces a graph-enhanced RAG architecture featuring a three-layer hybrid stack. First, structured entities and relationships are explicitly extracted at ingestion using LLMs or entity recognition. Next, this relational data is stored in graph databases like Neo4j, where vector embeddings serve as node properties. Finally, hybrid queries execute vector scans to locate entry points and traverse graph paths to gather context-rich information. Although this advanced approach introduces a production latency tax of 200 to 500 milliseconds, which can be mitigated through semantic caching, and requires managing data dependencies via change data capture pipelines, it ensures deterministic explainability. Ultimately, Amirkhanov provides an infrastructure framework advising organizations to deploy vector-only RAG for flat text and low-latency requirements, while upgrading to graph-enhanced RAG for highly regulated domains requiring multi-hop relationship mapping.


Designing Effective Meetings in Tech: From Time Wasters to Strategic Tools

The DZone article "Designing Effective Meetings in Tech: From Time Wasters to Strategic Tools" argues that engineering meetings must be systematically re-engineered into highly productive communication and decision-making systems rather than remain baseline sources of organizational disruption. To achieve this ideal state, the text outlines five core tactical principles tailored specifically for technical leaders. First, organizers must establish a clear scope and explicit expected outcomes beforehand, completely avoiding ambiguous, open-ended calendar titles. Second, leaders should actively combat Parkinson's Law by defaulting to much shorter, tightly constrained time slots, which structurally forces absolute intentionality among participants. Third, facilitators must aggressively redirect conversations away from trivial implementation details, effectively preventing "bikeshedding" by managing team discussions similarly to focused, high-priority computational thread execution. Fourth, comprehensive preparation is entirely mandatory; sharing technical artifacts like design proposals or Architecture Decision Records at least 24 hours in advance completely eliminates wasteful synchronous reading, shifting the collective focus strictly to active decision-making. Finally, the author promotes thorough documentation as an ultimate scaling mechanism and a "cached artifact" that inherently reduces organizational latency, turning blocking onboarding syncs into strategic collaborative sessions that permanently optimize long-term engineering workflow efficiency.


The Hidden Cost of Poor Training Data in Generative AI

The TDWI article highlights that while failed generative AI initiatives are frequently blamed on models, the true culprit is typically poor training data. In a generative AI context, data that is incomplete, mislabeled, biased, or outdated can train systems to be consistently wrong across all future interactions. This triggers a compounding financial and operational chain reaction, causing wasted compute, delayed product launches, legal exposure, and an erosion of enterprise confidence. Specifically, retraining an AI model after data failures can cost three to ten times the initial budget due to wasted GPU cycles, fresh audits, and restarted annotation pipelines. Enterprises often experience success during narrow pilots, only to watch models fail when introduced to messy, real-world production environments. Furthermore, regulatory frameworks like the EU AI Act, GDPR, and HIPAA mandate strict documentation and data traceability, which becomes exponentially expensive to build retroactively. To mitigate these hidden costs, organizations must shift their focus to pre-training data quality rather than post-training fixes. Key disciplines include running rigorous pre-training audits, intentionally designing training datasets to mirror real-world distributions, and embedding human validation at scale. Ultimately, prioritizing data integrity early prevents severe reputational risks and effectively enables scalable enterprise AI success.


CtrlS Says AI Is Breaking Traditional Data Centre Assumptions

In an interview with Dataquest, Rahul Dhar of CtrlS explains that the surge in GPU-intensive AI workloads is fundamentally dismantling traditional data center architecture assumptions. While legacy facilities typically manage 5 to 15 kW per rack, modern AI clusters demand an unprecedented 80 to 150 kW+, shifting industry bottlenecks from physical floor space to power density, cooling capacity, and interconnect efficiency. Consequently, the industry is bifurcating into conventional centers for general workloads and "AI factories" featuring power-first engineering, liquid cooling, and software orchestration. In India, this transition is amplified by the rapid evolution of Global Capability Centers into AI innovation hubs requiring ultra-low latency, GPU-dense environments, and sovereign data architectures. Furthermore, independent operators can successfully compete with dominant hyperscalers by prioritizing geographic proximity, specialized compliance, and localized edge infrastructure for latency-sensitive inference processing. Dhar projects a decisively hybrid future structured around an orchestrated AI fabric where large-scale training remains concentrated in hyperscale clouds while inference moves closer to end users. Ultimately, capital-intensive compute access, strategic grid energy availability, and robust infrastructure engineering, rather than human talent alone, are emerging as the primary bottlenecks shaping global technological innovation velocity over the next decade.


Why every organisation needs a minimum viable company strategy

The article highlights the growing necessity of a Minimum Viable Company (MVC) strategy to combat the prolonged, financially devastating operational disruptions caused by modern cyberattacks. Traditional disaster recovery methods often falter because they attempt to fully restore complex IT systems simultaneously, a tedious process that frequently leaves enterprises incapacitated for weeks or months. Conversely, an MVC strategy shifts focus toward identifying and sustaining only the leanest, most critical operational framework required to continue serving clients during an active crisis. Key areas prioritized typically include communications, identity access, and crucial supply chain or financial systems. Despite widespread recognition of its immense value, defining an MVC remains exceptionally challenging due to deep structural IT silos, systemic application dependencies, and complex hybrid environments. To operationalize an MVC strategy efficiently, experts recommend allocating a foundational baseline of roughly 20% of the company's production infrastructure—such as storage, compute power, and workload scope—and keeping it entirely immutable and air-gapped. Within this baseline, roughly 10% should be set aside as an isolated, cleanroom environment for malware-free recovery. By preparing these parameters in advance and utilizing modern recovery tools, businesses can rapidly recover essential functions within hours rather than weeks, dramatically mitigating long-term operational downtime and protecting market reputation.


Can Laws Stop Deepfakes? South Korea Aims to Find Out

South Korea's local elections serve as a critical test bed for the efficacy of legislative frameworks aimed at curbing political AI deepfakes. The country is pioneering national regulation through two primary statutes: Article 82-8 of the Public Official Election Act, which bans realistic synthetic media for ninety days before an election under penalty of prison or substantial fines, and the AI Basic Act, which mandates explicit watermarks or disclosures on AI-generated content. Additionally, the National Police Agency utilizes a specialized deepfake detection tool to aid investigations. Despite these aggressive legal tools, experts warn that regulation acts only as a baseline defense due to a fundamental asymmetry in operational speed. Publicly available AI tools can generate and propagate convincing deepfakes globally in seconds via encrypted apps and direct messaging, while the judicial machinery required to detect, investigate, and remove content operates over days or weeks. Furthermore, foreign threat actors remain largely outside the reach of local prosecution. Ultimately, cybersecurity and election experts argue that laws must be reinforced by a multi-layered strategy that holds social media platforms accountable, implements robust content provenance standards, and promotes widespread voter media literacy to successfully mitigate the disruptive demand side of digital disinformation.


Four cutting-edge tools for spec-driven development

Based on the InfoWorld article by Martin Heller, the text highlights the shift from haphazard "vibe coding" to Spec-Driven Development (SDD), a structured methodology that keeps AI coding agents accurate and managed. While vibe coding might suffice for minor weekend hobbies, it introduces major technical debt and obscure bugs to enterprise environments. In contrast, SDD acts as a formal contract and reliable source of truth by utilizing concise, readable documents. The article details four advanced tools pioneering this approach: AWS's Kiro, Microsoft's Spec Kit, Tessl, and Zenflow. Kiro works as an IDE and CLI tool, generating structured markdown files to outline requirements, architecture, and agent steering. Microsoft’s open-source Spec Kit utilizes special slash commands to manage project principles, requirements, and parallel execution. Tessl maintains agent alignment using a unique package registry with "tiles" that bundle coding workflows and rules. Finally, Zenflow orchestrates dynamic workflows via multiple autonomous agents, implementing automated test verification and cross-agent code reviews within isolated Git environments. Ultimately, the article concludes that implementing specifications is vital for large refactoring efforts and enterprise software engineering, advising developers to evaluate their infrastructure to select the framework that best fits their orchestration, scalability, and workflow criteria.


The trouble with emotion-reading AI

The article written by Mike Elgan discusses "emotion AI" or affective computing, which analyzes vocal features, facial expressions, text, and biosignals to measure worker sentiment. While it has defensible goals, such as tracking driver fatigue for safety, improving customer service, or detecting HR burnout, it introduces severe organizational and ethical risks. Fundamentally, emotion AI rests on flawed scientific foundations; psychological research indicates that emotional states cannot be universally or reliably inferred from facial expressions alone. Additionally, these technologies exhibit significant racial bias, frequently misinterpreting Black faces as angry, and they endanger employee privacy by failing to ensure true anonymity in smaller teams. Rather than inspiring workers, companies use emotion AI to enforce hyper-surveillance, which drives up stressful "emotional labor." Consequently, the industry faces severe regulatory pushback, including an EU ban in workplace and educational environments and local restrictions in states like California and New York. Tech giants like Microsoft have even voluntarily abandoned these capabilities, citing a lack of scientific consensus and high discrimination risks. Ultimately, the article argues that emotion AI is too flawed, biased, and legally problematic to deploy safely in modern businesses.

Daily Tech Digest - April 25, 2026


Quote for the day:

"People don’t fear hard work. They fear wasted effort. Give them belief, and they'll give everything." -- Gordon Tredgold


🎧 Listen to this digest on YouTube Music

▶ Play Audio Digest

Duration: 23 mins • Perfect for listening on the go.


The high cost of undocumented engineering decisions

Avi Cavale’s article highlights a critical hidden cost in the tech industry: the erosion of institutional memory due to undocumented engineering decisions. While technical turnover averages 15–20% annually, the primary financial burden isn’t just recruitment or onboarding; it is the loss of the “why” behind architectural choices. Traditional documentation often fails because it focuses on technical specifications—the “what”—while neglecting the vital context of tradeoffs and failed experiments. This creates a “decay loop” where new hires inadvertently re-litigate past decisions or propose previously debunked solutions, significantly slowing development velocity over time. As original team members depart, institutional knowledge becomes a “lossy copy,” leaving the remaining team to treat established systems as historical accidents rather than intentional designs. To solve this, Cavale argues for leveraging AI coding tools to automatically capture and structure technical conversations. By transforming developer interactions into a living knowledge base, organizations can ensure that rationale, error patterns, and conventions are preserved within the system itself. This shift moves engineering knowledge away from individual heads and into a durable organizational asset, effectively lowering the “bus factor” and preventing the costly cycle of repetitive mistakes and re-explained logic that typically follows employee departures.


The AI architecture decision CIOs delay too long — and pay for later

In this CIO article, Varun Raj argues that the most critical mistake IT leaders make with enterprise AI is delaying the necessary shift from pilot-phase architectures to robust, production-grade frameworks. While initial systems often succeed by tightly coupling model outputs with immediate execution, this approach becomes unmanageable as use cases scale. The author warns that early success often breeds a dangerous inertia, masking structural flaws that eventually manifest as unpredictable costs, governance friction, and "behavioral uncertainty"—where teams can no longer explain the logic behind automated decisions. To avoid these pitfalls, CIOs must proactively transition to architectures that decouple decision-making from action, implementing dedicated control points to validate AI outputs before they trigger enterprise processes. Treating the initial architecture as a permanent foundation rather than a temporary starting point leads to escalating technical debt and eroded stakeholder trust. By recognizing subtle signals of misalignment early—such as increased complexity in security reviews or model volatility—leaders can ensure their AI initiatives remain controllable and transparent. Ultimately, the transition from systems that merely assist humans to those that autonomously act requires a fundamental architectural evolution that prioritizes oversight and predictability over simple operational speed.


When Production Logs Become Your Best QA Asset

Tanvi Mittal, a seasoned software quality engineering practitioner, addresses the persistent issue of critical bugs slipping through rigorous QA cycles and only manifesting under specific production conditions. Inspired by a banking transaction failure caught by a human teller rather than automated tools, Mittal developed LogMiner-QA to bridge the gap between staging environments and real-world usage. This open-source tool leverages advanced technologies like Natural Language Processing, transformer embeddings, and LSTM-based journey analysis to reconstruct actual customer flows from fragmented logs. A significant hurdle in its development was the messy, non-standardized nature of production data, which the tool handles through flexible field mapping and configurable ingestion. Addressing stringent security requirements in regulated industries like banking and healthcare, LogMiner-QA incorporates robust privacy measures, including PII redaction and differential privacy, while operating within air-gapped environments. Ultimately, the platform transforms production logs into actionable Gherkin test scenarios and fraud detection modules, enabling teams to detect anomalies before they result in costly failures. By shifting focus from theoretical requirements to observed user behavior, LogMiner-QA ensures that production data becomes a vital asset for continuous quality improvement rather than just a post-mortem diagnostic tool.


The History of Quantum Computing: From Theory to Systems

The history of quantum computing reflects a remarkable evolution from abstract physics to a burgeoning technological revolution. The journey began in the early 20th century with the foundational work of Max Planck and Albert Einstein, who established that energy is quantized, eventually leading to the development of quantum mechanics by figures like Schrödinger and Heisenberg. However, the computational potential of these laws remained untapped until the early 1980s, when Paul Benioff and Richard Feynman proposed that quantum systems could simulate nature more efficiently than classical machines. This theoretical framework was solidified in 1985 by David Deutsch’s concept of a universal quantum computer. The field transitioned from theory to algorithms in the 1990s, most notably with Peter Shor’s 1994 discovery of an algorithm capable of breaking classical encryption, providing a clear "killer app" for the technology. By the 2010s, experimental milestones like Google’s 2019 "quantum supremacy" demonstration with the Sycamore processor proved that quantum hardware could outperform supercomputers. Entering 2026, the industry has shifted toward practical error correction and commercial utility, with tech giants like IBM and Microsoft integrating quantum processors into cloud ecosystems to solve complex problems in materials science, medicine, and cryptography.


15 Costliest Credential Stuffing Attack Examples of the Decade (and the Authentication Lessons They Teach)

The article "15 Costliest Credential Stuffing Attack Examples of the Decade" explores how automated login attempts using previously breached credentials have evolved into one of the most persistent and expensive cybersecurity threats. Over the last ten years, major organizations—including Snowflake, PayPal, 23andMe, and Disney+—have suffered massive account takeovers, not because of software vulnerabilities, but because users frequently reuse passwords across multiple services. Attackers leverage lists containing billions of leaked credentials, achieving success rates between 0.1% and 2%, which translates to hundreds of thousands of compromised accounts in a single campaign. These incidents have led to billions in damages, regulatory fines, and the theft of sensitive data like Social Security numbers and medical records. The primary lesson highlighted is the critical necessity of moving beyond traditional passwords toward "passwordless" authentication methods, such as passkeys, biometrics, and hardware tokens. While multi-factor authentication (MFA) remains a vital defensive layer, the article argues that passwordless systems make credential stuffing structurally impossible by removing the reusable "secret" that attackers rely on. Additionally, the piece notes that regulators increasingly view the failure to defend against these predictable attacks as negligence rather than bad luck, signaling a major shift in corporate liability and security standards.


How To Build The Self-Leadership Skills Rising Leaders Need Today

In the evolving landscape of professional growth, self-leadership serves as the foundational bedrock for rising leaders, as explored by the Forbes Coaches Council. Effective leadership begins internally, requiring a shift from the desire for absolute certainty to a mindset of continuous curiosity. Aspiring executives must cultivate self-compassion and prioritize personal well-being, recognizing that physical and mental health are essential requirements for sustained high performance rather than mere indulgences. Furthermore, the article emphasizes the importance of financial discipline and self-regulation, urging leaders to ground their decisions in data while maintaining emotional composure under pressure. Consistency is another critical pillar, as it builds the trust and credibility necessary to inspire others. Perhaps most significantly, the council highlights the need for leaders to redefine their personal identities, moving beyond their roles as "doers" or technical experts to embrace the strategic complexities of their new positions. By mastering their thought patterns and questioning limiting beliefs, individuals can transition from reactive decision-making to intentional action. Ultimately, self-leadership is not an abstract concept but a practical toolkit of skills that enables up-and-coming professionals to navigate the modern "polycrisis" environment with resilience, authenticity, and a human-centric approach to management.


Space data-center news: Roundup of extraterrestrial AI endeavors

The technological frontier is rapidly expanding beyond Earth’s atmosphere as major players and startups alike race to establish extraterrestrial computing infrastructure. This surge is highlighted by NVIDIA’s entry into the market with its "Space-1 Vera Rubin" GPUs, specifically designed for orbital AI inference. Simultaneously, Kepler Communications is already managing the largest orbital compute cluster, recently partnering with Sophia Space to test proprietary data center software across its satellite network. The commercialization of this sector is further accelerating with Lonestar Data Holdings set to launch StarVault in late 2026, marking the world’s first commercially operational space-based data storage service catering to sovereign and financial needs. Complementing these hardware advancements, Atomic-6 has introduced ODC.space, a marketplace that allows organizations to purchase or colocate orbital data capacity with timelines that rival terrestrial data center builds. These endeavors collectively signify a shift from experimental proof-of-concepts to a functional "off-world" digital economy. By moving processing and storage into orbit, these companies aim to provide sovereign data security and low-latency AI capabilities for global and celestial applications. This nascent industry represents a critical evolution in how humanity manages high-performance computing, transforming space into the next essential hub for the global data infrastructure.


Orchestrating Agentic and Multimodal AI Pipelines with Apache Camel

This article explores the evolution of Apache Camel as a robust framework for orchestrating agentic and multimodal AI pipelines, moving beyond simple Large Language Model (LLM) calls to complex, multi-step workflows. It defines agentic AI as systems where models act as reasoning agents to autonomously select tools and tasks, while multimodal AI integrates diverse data types like images and text. The core premise is that while LLMs excel at reasoning, they often lack the reliability required for production-level execution. By leveraging Apache Camel and LangChain4j, developers can pull execution control out of the agent and into a proven orchestration layer. This approach allows Camel to handle critical operational concerns like routing, retries, circuit breakers, and deterministic sequencing using Enterprise Integration Patterns (EIPs). The text details a practical implementation involving vector databases for RAG and TensorFlow Serving for image classification, illustrating how Camel separates reasoning from action. While the framework offers significant scalability and governance benefits for enterprise AI, the author notes a steeper learning curve for Python-focused teams. Ultimately, Camel serves as a vital "meta-harness," ensuring that generative AI applications remain reliable, maintainable, and securely integrated with existing enterprise infrastructure and data sources.


AI agents are already inside your digital infrastructure

In the article "AI agents are already inside your digital infrastructure," Biometric Update explores the rapid proliferation of agentic AI and the resulting security vulnerabilities. As enterprises increasingly deploy autonomous agents—with some estimates predicting up to forty agents per human by 2030—the digital landscape faces a critical crisis of trust. Highlighting data from the Cloud Security Alliance, the piece reveals that 82 percent of organizations already harbor unknown AI agents within their systems. This shift has essentially reduced the cost of impersonation to zero, rendering legacy authentication methods obsolete. In response, Prove Identity has launched a unified platform designed to provide a persistent foundation of trust through continuous verification. Leveraging twelve years of authenticated digital history, the platform addresses the inadequacies of point solutions by utilizing adaptive authentication, proactive identity monitoring, and advanced fraud protection. The suite further integrates cryptographically signed consent into identity tokens that accompany agentic workflows across major frameworks like OpenAI and Anthropic. Ultimately, the article argues that while AI can easily fabricate biometrics, it cannot replicate long-term digital behavior. Securing this "agentic economy" requires evolving identity systems that can govern these non-human identities, preventing them from hijacking infrastructure or operating without clear, authorized mandates.


The Denominator Problem in AI Governance

The "denominator problem" represents a critical yet overlooked challenge in AI governance, as highlighted by Michael A. Santoro. While emerging regulations like the EU AI Act mandate reporting AI incidents, these "numerators" of harm remain uninterpretable without a corresponding "denominator" representing total usage or opportunities for failure. Without knowing the scale of deployment, an increase in reported harms could signify declining safety, improved detection, or merely expanded adoption. While autonomous vehicle regulation successfully utilizes metrics like miles driven to calculate safety rates, most other domains—including deepfakes, algorithmic hiring, and healthcare—lack such standardized benchmarks. This measurement gap is particularly dangerous in healthcare, where the absence of a defined denominator prevents regulators from distinguishing between sporadic errors and systemic failures. Furthermore, failing to stratify denominators by demographic factors masks structural biases, effectively hiding algorithmic discrimination within aggregate data. As global reporting frameworks evolve, solving this fundamental measurement issue is essential for moving beyond performative disclosure toward genuine accountability. Transitioning from raw incident counts to meaningful safety rates is the only way to prove AI systems are truly safe and equitable, making the denominator problem a foundational hurdle for the future of effective technological oversight and regulatory success.