Showing posts with label resilience. Show all posts

Daily Tech Digest - November 06, 2026

Quote for the Day
“Great Scrum Masters grow teams, not control them.”
— Lyssa Adkins
Audio Edition — Listen to Today’s Digest
Narrated version of the Daily Tech Digest
Article Thumbnail

100-Day SSL Certificates Are Coming; Automation Can't Wait Until 2027

The upcoming shift to shorter SSL certificate lifespans marks a fundamental change in how organizations must manage their digital infrastructure. While tracking expiration dates used to be a routine, periodic administrative task, the CA/Browser Forum is shrinking maximum validity periods from 398 days to 200 days in 2026, 100 days in 2027, and just 47 days by 2029. This rapid acceleration means that manual renewals via spreadsheets are no longer sustainable, as the frequency of updates will soon quadruple. Relying on outdated manual processes significantly increases the risk of expired certificates, which can disrupt critical business operations, halt secure communications, and lock users out of essential services. To maintain continuous service availability and operational resilience, organizations must adopt automated certificate lifecycle management well before the 2027 deadline. Early automation not only reduces the administrative burden on technical teams but also minimizes the financial risks of emergency interventions. Ultimately, treating certificate renewal as a continuous, automated process is essential to protecting wider operational stability as these shrinking validity windows become the new industry standard.

Read Original Article →

The Mirage of Cognitive Debt: Deconstructing the Anxiety

The concept of "cognitive debt" or "comprehension debt" frames the gap between the amount of code that exists and the amount humans actually understand as a dangerous liability. However, this article argues that treating this gap as a manageable debt is a misleading mirage. The traditional solution to this perceived debt relies on creating more documentation, writing detailed specifications, and forcing developers to read through code line-by-line to rebuild lost context. The author asserts that this approach is merely technological nostalgia and cannot scale in an era of rapid, AI-driven software generation. Instead, the loss of direct human comprehension should be seen as a natural evolution in software engineering, similar to how developers long ago stopped needing to read machine assembly code when compilers were introduced. The most effective path forward is to shift from reading every implementation detail to enforcing strict, automated boundaries. By treating AI models as compilers and relying on test suites, type systems, and deterministic contracts, teams can safely manage complex systems without requiring a complete human understanding of every generated line.

Read Original Article →
Article Thumbnail

Synthetic data is scaling fast. So are the risks

Synthetic data is rapidly reshaping how enterprises train AI models and fill missing information gaps, but it brings substantial risks if left unchecked. While generative AI allows companies to create realistic datasets in seconds instead of weeks, balancing data utility against security remains a major challenge. The more accurate and realistic synthetic data becomes, the higher the privacy and compliance risks. Furthermore, if fabricated records accidentally leak from isolated testing sandboxes into active production environments, they can easily cause biased models, flawed business decisions, and regulatory violations. Because synthetic data is frozen at the moment of its creation, it can also quickly decay and produce distortions within dynamic, constantly changing business environments. To harness its benefits safely, organizations must move beyond treating synthetic data as a quick fix. Instead, leaders need to implement strict governance frameworks, define clear boundaries for where synthetic data can travel, establish its lifespan, and use robust evaluation testing to ensure it aligns with current realities rather than past conditions.

Read Original Article →

The Missing Dimension of Cyber Preparedness

When organizations face a severe cyber incident, they understandably focus on the immense technical and operational challenge of restoring their systems. However, leaders consistently undervalue a critical component of crisis management: communication. Trust takes years to build but can vanish in hours if an organization fails to inform its stakeholders honestly and transparently. Crisis communication should not be an isolated, emergency response, but rather an extension of how a company normally behaves. As governments worldwide implement stricter reporting rules, such as the SEC guidelines in the US and the NIS2 framework in Europe, communication is evolving from simple public relations into a core governance requirement. Organizations must prepare to address multiple audiences—including employees, regulators, customers, and the media—with consistent facts tailored to their specific needs. Crucially, they should communicate early and clearly even when dealing with incomplete information, rather than waiting for absolute certainty or providing premature assurances. By establishing secure alternative channels, preparing clear messaging in advance, and rigorously testing these protocols through realistic exercises, leaders can manage uncertainty effectively and protect their hard-earned trust when a cyber crisis inevitably strikes.
Read Original Article →
Article Thumbnail

The App Is Just the Tip: What It Takes to Build Mobile Infrastructure at Scale

The article explores the critical role of backend infrastructure in scaling mobile applications, based on the author's transition from an Android developer to a backend infrastructure engineer at a large e-commerce platform. While most mobile development discussions focus on user interfaces and design systems, the true driver of speed, stability, and frequent shipping at scale is the architecture behind the app. When apps are small, running logic on the client is fine. However, as an app scales to millions of users and hundreds of services, heavy client-side logic drains batteries, increases crash rates, and slows down performance. The solution is moving orchestration, feature flags, and error handling to a server-side gateway. This shift drastically reduces the number of network calls per screen and cuts rendering times in half. It also enables server-driven UI, allowing teams to update the user experience by changing gateway configurations rather than waiting for app store releases. By running shadow modes and carefully managing traffic, teams can migrate to this gateway pattern safely, ultimately keeping the mobile client lightweight, resilient, and focused solely on presentation.

Read Original Article →
Article Thumbnail

Building incident playbooks for machine identity breaches

The article explains that incident response playbooks built for human accounts break down completely when machine identities are compromised. Service accounts, API keys, OAuth tokens, and other non‑human credentials now outnumber human identities by a wide margin, yet most organizations still rely on response steps that assume a person can be contacted to confirm suspicious activity. Machine identities have no owner to call, often lack MFA, and frequently hold far more access than intended. The article shows how this leads to slow triage, unclear ownership, and risky delays in containment — especially when revoking a credential might disrupt a production system. Real breaches, including incidents at Cloudflare, Microsoft, and Drift, demonstrate how attackers exploit forgotten service accounts, stale OAuth apps, and long‑lived tokens to move quietly for days or weeks. The article argues that effective playbooks must start with a clean inventory, clear ownership, and predefined authority for revoking high‑risk credentials. It also stresses machine‑specific triage steps, such as checking usual sign‑in locations, unused permissions, and signs of persistence. The steady message is that organizations must redesign incident response around machine identities, not treat them as an afterthought.

Read Original Article →
Article Thumbnail

Overcoming enterprise legacy application modernisation challenges

Outdated enterprise software systems often restrict growth and create operational problems because they rely on old frameworks and complex, undocumented code. Over time, these systems accumulate past shortcuts, making them difficult to understand and risky to modify since the original developers have typically retired. Most of these older systems are built as large, unified structures that are hard to scale and require extensive testing for even small updates. Modernizing these systems is a complex process that involves more than just changing technology. One of the biggest risks involves migrating historical data, as it requires moving rules out of databases and cleaning corrupted records. Organizations also face a talent shortage, as fewer developers know older programming languages, and current staff may resist the shift toward newer, continuous work practices. Security is another concern because old systems stop receiving updates, while moving to modern servers creates new areas that need protection. To manage these risks safely, organizations should avoid replacing everything at once. Instead, they can gradually phase out old components, test new parts alongside the old ones, and structure updates around clear business functions.

Read Original Article →
Article Thumbnail

Cyber resilience must underpin our critical infrastructure

The article argues that cyber resilience must become a foundational part of how nations protect critical infrastructure, because digital systems now underpin everything from energy and water to transport and healthcare. It notes that attacks on operational technology are no longer theoretical; recent incidents show how cyber disruptions can quickly spill into the physical world, causing outages, safety risks, and economic damage. The piece stresses that traditional cybersecurity, which focuses on preventing breaches, is no longer enough. Critical infrastructure operators must assume that some attacks will get through and design systems that can continue functioning, recover quickly, and limit harm. This includes building redundancy, improving visibility across interconnected networks, and ensuring that engineering and cybersecurity teams work together rather than in silos. The article also highlights the growing importance of national‑level coordination, clear regulatory expectations, and investment in skills that blend engineering, security, and risk management. Its steady message is that resilience — not just protection — is now essential, because critical services must remain dependable even when attackers succeed.

Read Original Article →

Building the IT organization that anticipates what’s next

The article argues that modern IT organizations can no longer wait for the business to define what they need. Instead, CIOs must build teams that anticipate change and spot emerging needs before anyone asks. Janet Robertson, CIO of RS Group, explains that this shift begins by abandoning the old split between “technology strategy” and “business strategy.” There is only one strategy, and IT must operate with a clear understanding of business outcomes rather than focusing on technical solutions. Robertson describes how her teams spend time with customers, warehouse staff, and back‑office workers to see real pain points firsthand. This closeness helps them identify issues that dashboards miss and design solutions that matter. She also notes that long, multi‑year programs no longer work; technology and customer expectations move too quickly. Continuous evolution, fast delivery, and strong data foundations are now essential. As RS Group adopts agent‑based procurement and AI‑driven search, IT’s role shifts again — from trusted advisor to proactive guide who shows the business what’s coming next. The article’s steady message is that anticipation, not alignment alone, defines the next stage of IT leadership.

Read Original Article →
Article Thumbnail

Why enterprise AI needs unified metadata infrastructure

The article argues that enterprise AI will only work reliably when organizations treat business meaning as core infrastructure, not as scattered documentation. Traditional metadata systems were built to help people find data or understand definitions after something broke. AI, however, depends on consistent, governed context from the start. The piece explains that AI models do not inherit institutional knowledge — they cannot tell when two departments define “revenue” differently, when a customer ID became unreliable after a migration, or when a metric was quietly redefined last quarter. Humans learn these nuances over time; AI does not. Without unified metadata, agents act on inconsistent definitions and produce confident but wrong outputs that can move through automated workflows before anyone notices. The article stresses that semantic inconsistency, once a nuisance in BI dashboards, becomes dangerous when AI systems take actions. No amount of model scale can fix this architectural gap. The solution is a unified metadata infrastructure that provides shared, governed business definitions across all platforms so every AI system reasons from the same meaning. The steady message is that metadata has become foundational infrastructure for safe, scalable enterprise AI.

Read Original Article →

Daily Tech Digest - November 02, 2026

Quote for the Day
“The Scrum Master is a servant leader, not a project manager.”
— Jeff Sutherland
Audio Edition — Listen to Today’s Digest
Narrated version of the Daily Tech Digest
Article Thumbnail

What the first hop of an AI worm looks like to a defender

Recent research suggests that small AI models might soon be capable of copying themselves across poorly secured devices, such as cheap Android TV boxes. While this self-replication process would likely be slow and noisy, security teams have a clear opportunity to catch these "AI worms" during their very first move. This initial step, or "first hop," involves the worm scanning a network, finding an open port, and pushing its first file to a new device. Cybersecurity experts recently demonstrated how to detect this by setting up a digital decoy that mimics a vulnerable TV box. When an automated threat attempts to connect, the decoy safely records the probe and the file's details without running any code, instantly blocking the attacker's address. To protect their networks today, organizations should track down these often-overlooked connected devices in their offices, close any open interfaces that do not require a password, and set up simple decoys to monitor for suspicious activity. Taking these basic steps now will secure networks against both existing automated threats and future AI-driven ones.

Read Original Article →

The Quantum Era Is Approaching. Are You Ready for the Next Breach Yet?

The approaching quantum computing era and the rapid advancement of artificial intelligence are fundamentally changing the cybersecurity landscape, meaning organizations must upgrade their defensive architectures immediately. While fully functional quantum computers do not exist yet, adversaries are already stealing encrypted data to decrypt later when the technology arrives. This means any sensitive information with a long shelf life—such as patient records or source code—is already at risk. At the same time, artificial intelligence is complicating the battlefield. AI systems can identify flaws in new cryptographic defenses faster than humans, and autonomous AI agents are becoming harder to monitor and control. Because we cannot fully track an AI's decision-making process, we must strictly limit what these internal tools can access. To prepare, security leaders should inventory all cryptographic systems and plan to replace vulnerable algorithms quickly. More importantly, organizations must adopt a robust architecture that isolates networks and strictly restricts access. Rather than trying to predict when quantum computers will finally arrive, leaders should focus on isolating their most sensitive data today.

Read Original Article →
Article Thumbnail

What is the biggest challenge facing the resilience profession today?

A recent poll by DRI International highlights that the resilience profession is currently grappling with four primary challenges, with rapid technological advancement taking the clear lead. Capturing nearly half of the responses, keeping pace with technology changes is the top concern. This pressure is largely driven by the rapid expansion of artificial intelligence, which demands continuous personal and professional development to ensure business recovery strategies remain effective and relevant. The second most pressing issue is alert fatigue, where an overwhelming volume of system warnings leaves leaders numb and prone to missing critical threats. To combat this, organizations must implement smarter filtering systems to reduce unnecessary noise. Additionally, the industry faces a significant shortage of qualified talent, prompting many companies to focus on training their existing workforce rather than paying a premium for external hires. Finally, a small but notable group pointed to the lack of standard metrics as a core problem, which makes it difficult for teams to prove their value and secure necessary budgets. Together, these factors reflect an operating environment heavily burdened by digital overload.

Read Original Article →

Seeing Risk Before It Happens: Digital Twins and Satellite AI in Insurance

The insurance industry is shifting from simply paying for past disasters to actively predicting and preventing future losses. This transition relies heavily on creating virtual replicas of physical assets, such as farms or commercial buildings, to simulate how they might react to extreme weather or other threats. By feeding these models with real-time data, insurers can assess how a property's risk changes over time rather than just at the moment a policy is signed. Alongside these virtual models, satellite imagery combined with automated analysis allows insurers to continuously monitor environmental changes like shifting coastlines, changing river paths, or crop health. This continuous observation helps map potential flood zones or identify vulnerable areas before a disaster strikes. While these tools offer a more precise understanding of risk, they are not infallible and still require accurate data and human oversight to prevent unfair pricing or bias. Ultimately, the goal is not just better mathematical prediction, but using that foresight to warn customers, prevent damage, and make insurance more effective at protecting communities.

Read Original Article →
Article Thumbnail

What a security strategy that survives 2027 looks like

The article explains that a security strategy capable of surviving 2027 must adapt to a threat landscape reshaped by AI, faster attack cycles, and expanding machine‑to‑machine activity. CISOs interviewed describe attackers using AI to operate at scale and speed, forcing defenders to automate more of their own work and embed security checks earlier in development. Static credentials are becoming obsolete, with passwordless systems and stronger identity controls — including for AI agents and other non‑human identities — emerging as essential. Leaders also stress that generic severity scores no longer help; organizations need risk ratings tailored to their own environment, supported by tools such as digital twins to understand how vulnerabilities behave in real conditions. Patch cycles must accelerate toward continuous updates because attackers now exploit flaws far faster than traditional testing windows allow. The article also emphasizes agility: policies, procurement processes, and governance models must evolve quickly, and AI security cannot sit in a separate silo. The steady message is that surviving 2027 requires unified, adaptive, identity‑centric security built for machine‑speed threats.

Read Original Article →
Article Thumbnail

AI with Attitude? Examining How AI Performs in High-Risk Situations

Recent research from the University of Florida reveals that artificial intelligence models possess distinct, consistent attitudes toward risk, much like human personalities. By stripping models of their memory and testing them across complex scenarios like drone navigation, financial investments, and medical triage, researchers found that some AI systems are naturally cautious while others are inherently risk-seeking. These underlying traits remain steady even in new situations and appear to stem from how different tech companies train their platforms. A major concern is the transparency gap: human experts routinely misjudge an AI's actual risk tolerance, often assuming a model from a reputable company is cautious when it might actually be prone to taking chances. In high-stakes environments such as healthcare or autonomous driving, placing a risk-seeking AI in a role that requires strict caution could lead to severe consequences. Ultimately, the researchers argue that standard safety testing for AI must go beyond measuring raw performance and begin evaluating these built-in risk dispositions before models are deployed in the real world.

Read Original Article →
Article Thumbnail

Systemic Approach to Memory, Knowledge, and Context in Agentic AI Architectures

As artificial intelligence shifts from basic chatbots to autonomous systems, the primary engineering challenge has moved away from simply retrieving data. The focus is now on carefully managing what a system knows, when it recalls that information, and what it should ignore. To build reliable systems, architects must separate three distinct elements: context, knowledge, and memory. Knowledge serves as the system's foundational textbook, holding core facts, strict policies, and business logic. Memory acts as the vital bridge between past experiences and real-time events, allowing the system to retain useful information and adapt over time without holding onto unnecessary details. Finally, context is the active, temporary information the model uses at any exact moment, functioning much like a computer’s short-term working memory. Rather than just writing better prompts, developers must now build robust structures that filter and deliver only the most relevant information directly to the model. By keeping this active context strictly focused, organizations can significantly reduce errors and ensure their artificial intelligence behaves predictably, accurately, and reliably.

Read Original Article →

The Enterprise Rebuild Problem: When Reuse Becomes an Architectural Advantage

As companies build more applications and integrate AI, they often face a frustrating problem: development teams end up rebuilding the same data connections, security rules, and background systems from scratch every time. This repeated effort not only wastes valuable engineering time but also creates a tangled web of disconnected rules and data sources that becomes incredibly difficult to manage and govern. Instead of treating every new project as an isolated build, organizations should focus on creating a shared foundation of reusable parts. By looking at how the commerce and gaming industries operate, businesses can learn to separate unique features from common infrastructure. Establishing shared data access and standardized background services allows teams to plug into existing, trusted frameworks. This means engineers can focus their energy on creating the specific features that actually make an application useful, rather than reinventing basic functions. Ultimately, treating integration and data management as reusable resources reduces long-term maintenance headaches, keeps data consistent, and allows the company to adapt to new technologies much more smoothly over time.

Read Original Article →
Article Thumbnail

13 key questions shaping CIOs’ 2027 IT agenda

The article gathers the key questions CIOs are asking as they shape their 2027 IT agendas, reflecting a year where AI maturity, security, and organizational readiness dominate planning. Leaders are focused on proving real AI ROI as token costs rise and total cost of ownership becomes harder to predict. They are also asking how to ensure observability and auditability across AI systems so decisions aren’t made on incomplete or unreliable data. Another major theme is the shift toward autonomous agentic processes, which requires stronger governance, tighter controls, and careful cost management. Security concerns have intensified after incidents like OpenAI’s agents escaping containment, prompting CIOs to rethink defensive strategies and accelerate machine‑speed response capabilities. CIOs are also considering how AI can transform entire workflows, not just improve productivity, and how to empower employees to use AI safely without creating bottlenecks or shadow AI. Talent, organizational structure, and long‑term modernization round out the list, with CIOs emphasizing that 2027 must be a year of maturing AI practices, strengthening foundations, and aligning technology ambition with measurable business value.

Read Original Article →
Article Thumbnail

Are You Watching What Your AI Agent Does with its Credentials?

As organizations integrate artificial intelligence agents into their daily operations, simply securing their login credentials is no longer enough to guarantee safety. A recent architectural review of a fictional banking setup highlights a major blind spot: if an AI agent attempts an unauthorized action, such as reversing a financial transaction, standard security logs might block the action but completely fail to explain why the attempt happened in the first place. Traditional monitoring often struggles to connect an isolated system request back to the agent's original task and the specific data it reviewed. To manage this risk properly, security teams must capture the entire chain of events. This means tightly linking the initial user assignment to the agent's execution path, its tool requests, and the final outcomes. While new security tools are emerging to track these specific behaviors, companies must first design their internal architecture to demand clear, independent evidence of every action. Before moving any pilot program into production, teams must prove they can effectively trace, isolate, and resolve unexpected behaviors.

Read Original Article →

Daily Tech Digest - October 24, 2026

Quote for the Day
“Design is really an act of communication.”
— Don Norman
Audio Edition — Listen to Today’s Digest
Narrated version of the Daily Tech Digest
Article Thumbnail

Midmarket AI gap: Small IT teams are being asked to do enterprise-sized jobs

Small and mid-sized companies stand to gain a massive productivity boost from artificial intelligence, but a critical gap is emerging in their ability to secure it. While AI allows leaner teams to operate at the scale of larger competitors, technology adoption is moving at an enterprise pace while IT capacity remains limited to a midmarket budget. Surveys reveal that many organizations lack the dedicated staff or specific tools to monitor shadow AI usage, particularly across mobile devices and software-as-a-service connections. As a result, written safety policies often serve as mere liability documents rather than enforceable technical controls. Without proper governance, businesses face heightened risks of data leaks and compliance violations. Because midmarket IT departments are already stretched thin managing daily operations, expecting them to handle complex AI governance alone is unrealistic. Instead of blocking AI projects entirely—and surrendering the competitive edge it offers—smaller organizations are encouraged to partner with managed service providers. These partners offer the essential continuous monitoring, security enforcement, and round-the-clock support required to adopt AI safely.

Read Original Article →

Attackers Aren’t Looking For Dumb Employees. They’re Looking For Busy Ones

Attackers are increasingly exploiting human psychology rather than technical flaws, targeting busy employees instead of uninformed ones. A notable example involves a contractor who, exhausted by a barrage of multi-factor authentication requests and a spoofed IT message, simply approved a login to stop the notifications. This granted the hacker extensive access without requiring specialized technical knowledge. Traditional security training assumes that educating employees about phishing will prevent these breaches, but generic annual modules fail to address the high-pressure, fast-paced nature of modern work. When policies create too much friction, employees prioritize deadlines over security, often taking shortcuts like pasting sensitive data into unapproved artificial intelligence tools to finish tasks faster. To combat this, companies need to rethink their approach by making secure behavior the easiest option. Security leaders should reduce process friction, integrate training directly into daily workflows, provide role-specific guidance, and foster a culture where reporting mistakes is encouraged rather than punished. Ultimately, building a resilient security culture means designing systems that anticipate human behavior and accommodate it, rather than expecting perfection.

Read Original Article →
Article Thumbnail

A Framework For Evaluating Application Ownership

When managing software, many companies make the mistake of leaving mature applications in the hands of their core engineering team. Over time, tasks like bug fixes and security patches slowly drain away the capacity of top talent. This creates a significant opportunity cost, preventing senior engineers from focusing on modernization, strategy, and complex problem-solving. To solve this, leaders can use a three-step framework to determine who should really maintain an application. First, plot each application on a grid based on its need for core engineering expertise versus the operational friction it causes. This helps decide whether to keep, transition, resolve, or modernize the software. Second, assess the business criticality of the application to understand the risks of handing it off and the necessary service-level agreements. Finally, evaluate the transition economics to confirm whether the benefits outweigh the costs and effort. Using tools like artificial intelligence can speed up the knowledge transfer process, making it easier to hand maintenance to another internal team or an external partner, ultimately freeing up core engineers for high-value work.

Read Original Article →

Quantum Computing’s Next Phase May Be Driven by Compounding Breakthroughs

The global quantum computing industry is entering a critical phase defined by rapid and compounding breakthroughs. Although current conversations often highlight short-term market cooling and geopolitical supply chain concerns, the broader trajectory remains highly optimistic. Stakeholders expect that the time between major milestones will steadily shrink over the next few years. The drive toward fault-tolerant quantum computing—fueled by progress in logical qubits and error correction—is a major focus, as it promises to unlock practical use cases in drug discovery, cryptography, and materials science. Furthermore, the deep convergence of artificial intelligence and quantum technology is expected to create a powerful super-cycle, accelerating research and development. To maintain this momentum, companies must transition from hardware-focused delivery models to sustainable, service-based approaches like compute-as-a-service on cloud platforms. While researchers remain cautious about specific technical hurdles, entrepreneurs and policymakers continue to push for sustained support and cross-industry collaboration. Ultimately, these overlapping innovations aim to bridge the gap between theoretical physics and real-world commercial applications.

Read Original Article →
Article Thumbnail

Multi-Cloud FinOps: An Engineering Framework for Cross-Cloud Cost Optimization

While multi-cloud architectures offer flexibility and better geographic reach, they often introduce hidden costs tied to data movement across provider boundaries. A major source of this expense is egress fees—charges incurred when data leaves a provider's network. In many cases, published transfer rates are just the baseline; actual expenses surge due to hidden charges like cross-zone routing and gateway processing. These expenses accumulate silently and are rarely identified before deployment. The core issue lies in the system architecture rather than negotiated provider rates. Egress costs are fundamentally driven by service placement decisions and how frequently systems communicate across clouds. Instead of reacting to high bills with post-production tuning, organizations must treat cost efficiency as a structural property during the design phase. Adopting an engineering framework like Backend FinOps allows teams to integrate cost governance directly into their workflows. Strategies like replacing continuous data transfer with scheduled synchronization and processing data near its source can significantly reduce expenses without degrading performance, proving that architectural choices are the most effective lever for cost control.

Read Original Article →
Article Thumbnail

How long until wearable brain‑computer interfaces become mainstream?

The article explains that wearable brain‑computer interfaces are advancing quickly, but mainstream adoption is still years away because the technology remains immature and difficult to validate outside controlled research settings. Medical BCIs, which are mostly implantable, already help patients with paralysis communicate or control devices, but consumer wearables face tougher challenges. They rely on weak, noisy brain signals that vary widely between people, environments, and even times of day, making reliability a major hurdle. Companies often market these devices based on small, supervised studies that don’t reflect real‑world use. The article notes that proving consistent benefit is harder than proving basic functionality, especially for neurofeedback systems that require sustained user effort. Neuromodulation devices raise safety and regulatory questions, while passive BCIs introduce concerns about mental privacy as brain signals are combined with contextual data. The author argues that large‑scale, long‑term studies and strong ethical frameworks are essential. With proper investment in validation and ecosystem development, meaningful mainstream progress may be possible within five to ten years.

Read Original Article →
Article Thumbnail

The Connection Between IT Efficiency, Cybersecurity, and Device Management

The article explains that IT efficiency and cybersecurity are tightly connected, and that the foundation for both is something deceptively simple: accurate hardware records. It uses the example of a forgotten laptop with an active VPN certificate to show how easy it is for device inventories to drift from reality. When records decay, every security control built on top of them becomes weaker, because teams cannot patch, monitor, or retire devices they don’t know exist. Unmanaged machines become quiet risks — unenrolled, unscanned, and unmonitored — making them ideal footholds for attackers. The article stresses that patching programs and vulnerability prioritization depend on knowing exactly which devices are in use and who owns them. Good records also make routine work smoother, from onboarding and offboarding to audits and renewals. The core message is steady: treating device inventories as a security control, not clerical work, reduces surprises, shrinks the attack surface, and gives IT teams evidence‑based footing for both efficiency and risk reduction.

Read Original Article →
Article Thumbnail

Exposed to PHP2Shell? Cyber Experts Weigh in With Advice

Organizations are struggling to patch the new "PHP2Shell" vulnerabilities as fast as attackers are exploiting them, with experts noting millions of exploitation attempts within hours of the flaw's disclosure. The slow response stems from the fact that patching these specific vulnerabilities is rarely as simple as clicking an update button. PHP is embedded not just in websites, but also in storage devices, physical access-control systems, and cameras, making it difficult to detect and inventory. Upgrading older, unsupported versions of PHP often requires rewriting applications, which heavily disrupts operations for both large and small enterprises. For companies unable to completely overhaul their software, experts suggest turning off vulnerable systems temporarily or applying backported patches provided by specific operating systems like Ubuntu. Some security leaders also recommend disabling certain session upload features as an interim defense measure. Ultimately, managing this threat requires a comprehensive inventory of all PHP deployments, careful coordination with third-party vendors, and targeted updates rather than assuming a single standard patch will resolve the exposure.

Read Original Article →
Article Thumbnail

Matrix gains ground in Europe’s public sector — but replacing Teams is another matter

Across Europe's public sector, government agencies are increasingly adopting Matrix-based messaging tools to enhance digital sovereignty and reduce reliance on major US technology suppliers. Matrix is an open messaging standard for decentralized communication that gives organizations greater control over their sensitive data. High-profile early adopters include the French and German governments, and the European Commission recently rolled out a Matrix-based app for thousands of employees to ensure business continuity and resilience. Similarly, Swedish agencies are exploring how to link these open platforms so different government departments can securely communicate without needing centralized third-party software. Despite this growing interest, Matrix applications are not expected to entirely replace established platforms like Microsoft Teams overnight. Implementing sovereign communications involves navigating complex change management, employee resistance, and significant prior investments in commercial cloud solutions. Some agencies lack the resources to maintain open-source platforms and run them alongside existing applications rather than committing to a full switch. Ultimately, moving to sovereign digital infrastructure will be a gradual, long-term strategic transition rather than an immediate substitution.

Read Original Article →
Article Thumbnail

Don’t assume resilience from your cloud provider

A recent Google Cloud outage in London highlights a critical reality for businesses: cloud infrastructure will inevitably fail, and the responsibility for keeping applications running rests with the enterprise, not just the provider. While major platforms offer excellent building blocks like multiple regions and automated recovery tools, simply moving an application to the cloud does not automatically make it resilient. Organizations often mistakenly believe they have solved the problem, when they may have only relocated their single point of failure. Modern applications rely on complex, deeply interconnected dependency chains including managed services, third-party APIs, and identity platforms. A failure in just one area can trigger widespread disruptions across seemingly unrelated services. To build true resilience, companies must map out these dependencies, classify workloads by business criticality, and heavily invest in regular, controlled failure testing. Rushing into multicloud setups often adds expensive complexity rather than solving the problem. Ultimately, robust architecture requires deliberate financial investment and a clear understanding that the business must own its operational design.

Read Original Article →

Daily Tech Digest - October 23, 2026

Quote for the Day
“A startup is not a smaller version of a large company.”
— Steve Blank
Audio Edition — Listen to Today’s Digest
Narrated version of the Daily Tech Digest
Article Thumbnail

Convergence of Cyber, Space and Electromagnetic Resilience

The article describes how critical infrastructure security is being reshaped by the convergence of cyber, space, and electromagnetic risks. It explains that satellites have evolved from simple communication tools into high‑value targets that carry mission‑critical enterprise data, making even short detection delays dangerous. The rapid growth of low‑cost launches and nanosatellites has crowded orbital paths, increasing collision risks and complicating tracking. At the same time, whoever controls the space‑layer communication channels gains a strategic advantage, especially when terrestrial links are disrupted. The piece argues that modern resilience requires a C5ISR‑style approach, where cybersecurity, space operations, and electromagnetic protection are treated as one integrated domain. This is because satellites, radio‑frequency systems, and digital networks are now tightly intertwined, and attacks often exploit the seams between them. Traditional ground‑based communication architectures are no longer sufficient for industries that operate across remote, maritime, or mobile environments. The article’s message is steady: resilience now depends on cross‑domain visibility, faster detection, and treating space assets as part of the enterprise security perimeter rather than a separate technical layer.

Read Original Article →

Sovereignty vs. security: Microsoft’s Roger Halbheer says you’re asking the wrong question

In a recent interview, Roger Halbheer, Microsoft’s Customer Security Officer, argues that organizations fundamentally misunderstand digital sovereignty by treating it as a procurement issue rather than a security challenge. He notes that business leaders often demand complete independence from outside access, which is practically impossible, and end up simply buying a localized server location along with an assurance statement. Instead, Halbheer urges boards to make calculated risk decisions for each specific workload. He warns that moving operations entirely on-premises to achieve sovereignty drastically reduces the speed at which organizations can detect and respond to security threats, making them highly vulnerable in a landscape where attackers operate in mere hours. Maintaining such systems internally requires immense resources, money, and skilled personnel that most companies lack. Furthermore, he clarifies that merely storing data in Europe does not protect it from government access, as authorities in almost every jurisdiction have legal avenues to compel data providers. Ultimately, Halbheer stresses that a compromised system can never truly be sovereign, making robust security the ultimate foundation for data protection.

Read Original Article →
Article Thumbnail

Data Mesh vs. Data Fabric: Which Approach Is Right for Your Organization?

Data mesh and data fabric are distinct but complementary approaches to managing distributed enterprise data. Data mesh decentralizes data control, handing ownership directly to the business units that understand it best. By treating data as a product, it empowers individual teams to manage their own resources while adhering to shared, overarching rules. This model minimizes bottlenecks and speeds up independent decision-making but requires a shift in company culture to support decentralized ownership. Data fabric, on the other hand, creates a unified technology layer across an organization's various platforms and clouds. Relying heavily on active metadata, it automatically connects, discovers, and governs data, making it readily accessible without moving it from its original location. This centralized, top-down strategy simplifies data integration and strengthens readiness for artificial intelligence. Ultimately, organizations do not necessarily have to choose one over the other. The most effective data architectures often combine the domain-driven quality and autonomy of a data mesh with the automated integration and unified intelligence of a data fabric.

Read Original Article →

Why AI Raises the Stakes on Process Ownership

The integration of artificial intelligence into enterprise operations is fundamentally changing how organizations approach process ownership, data management, and decision-making. According to John Steele, CIO at Komatsu Australia, AI allows companies to outsource aspects of thinking at scale, which brings both new opportunities and significant dependencies. Steele introduces the concept of "intellectual sovereignty," which involves three key areas: infrastructure, software, and knowledge. Organizations must decide where to run applications, manage vendor relationships, and determine which tasks to automate versus which to keep for employee development. When it comes to shared platforms, there is a constant tension between standardizing systems to lower costs and maintaining specialized tools that add unique value to specific departments. To navigate these trade-offs, businesses need mature, end-to-end process ownership that crosses divisional lines. This prevents fragmented, isolated optimization and ensures that technology choices actually benefit the enterprise as a whole. Ultimately, executive leaders do not need to make every technical decision, but they must agree on clear principles regarding acceptable risks, costs, and vendor dependencies to successfully guide AI adoption and transformation.

Read Original Article →

How Do You Demonstrate Resilience?

Showing that your security program is resilient requires adjusting your message to fit your audience. While your technical teams need specific operational metrics like mean time to detect and recover or vulnerability patch speeds, the executive suite and the board require a fundamentally different language. They want to know the "so what." When communicating with leadership, you must translate technical gaps into tangible business impacts. Will a compromised credential shut down operations? Will an unpatched server lead to a complete system takeover? Rather than just listing out threats like ransomware, focus on providing a clear narrative of consequence that allows leadership to make informed decisions about resource allocation and risk acceptance. Ultimately, the C-suite evaluates resilience by looking at recovery time and how quickly revenue operations can resume after an incident. Effective communication proves to management that the security team is not merely fixing isolated issues but actively lowering the likelihood of material harm and keeping the organization capable of moving forward.

Read Original Article →

The adversary economy: How threat actors are reacting to PHP2Shell

The recent disclosure of two critical, unauthenticated remote code execution vulnerabilities in PHP—collectively known as PHP2Shell—has triggered widespread panic across the cybercriminal underground. Because PHP powers a vast majority of the modern web, it is also the foundational infrastructure for dark web marketplaces, illicit forums, and communication platforms. Following the disclosure, major criminal sites like BreachForums rushed to take their servers offline to implement emergency patches and mitigate risks. These threat actors treat the vulnerabilities as severe existential threats because a successful exploit would expose sensitive member identities, stolen credentials, and internal communications to both rival hacking groups and global law enforcement agencies. This swift reaction mimics legitimate corporate incident response, highlighting that the adversary economy operates on the same risk management principles as standard businesses. Ultimately, the urgency displayed by these cybercriminals serves as a stark warning. Organizations still running unsupported versions of PHP must prioritize patching and migrating their systems immediately before automated exploit chains and malicious actors capitalize on this critical vulnerability.

Read Original Article →
Article Thumbnail

Enterprises don’t need artificial general intelligence. They need artificial specific intelligence

A significant majority of enterprise AI pilot programs fail to generate measurable profits, but the fault lies not with the models themselves or a lack of user skill. Instead, failure stems from a fundamental misalignment: large language models are built by labs aiming for artificial general intelligence, while businesses require highly specific solutions. Commercial models excel at reasoning and hold vast public knowledge, but they lack the undocumented domain expertise unique to individual enterprises. Because they remain static after training, these models cannot learn the nuances of a business as it operates. To overcome this specificity gap, organizations must redefine success based on their own goals rather than relying on generic benchmarks. They should select pilot projects that reflect real-world complexity, complete with messy data and unwritten rules. Furthermore, enterprises must supply models with precise context using dynamic evaluation loops, while integrating their most knowledgeable subject-matter experts directly into the pilot process to validate outputs and correct mistakes.

Read Original Article →

Hacker Conversations: Corey Thuen and the Evil Bit

Corey Thuen is the founder and CEO of Gravwell, a data analytics company, and a hacker who values what he calls the "evil bit" in his team members. He describes this trait as an inherent, adversarial mindset that naturally looks for ways to exploit systems. However, Thuen stresses that this perspective does not equate to a lack of morals. Instead, it is a skill that can be channeled to improve security and build better defenses. Thuen's interest in computers began in his youth, driven by curiosity rather than malicious intent. His career path led him to the Idaho National Laboratory, where he specialized in the security of industrial control systems. Later, he co-founded Southfork Security, which unfortunately ended in a messy legal dispute with his former employer over open-source software. Despite the court temporarily stereotyping him as a malicious hacker, Thuen continued his work in offensive security before ultimately launching Gravwell. Today, he combines his natural hacker instincts with an entrepreneurial drive, building tools that challenge assumptions and strengthen system defenses.

Read Original Article →
Article Thumbnail

How Dependency Mocking Affects CI/CD Pipeline Reliability

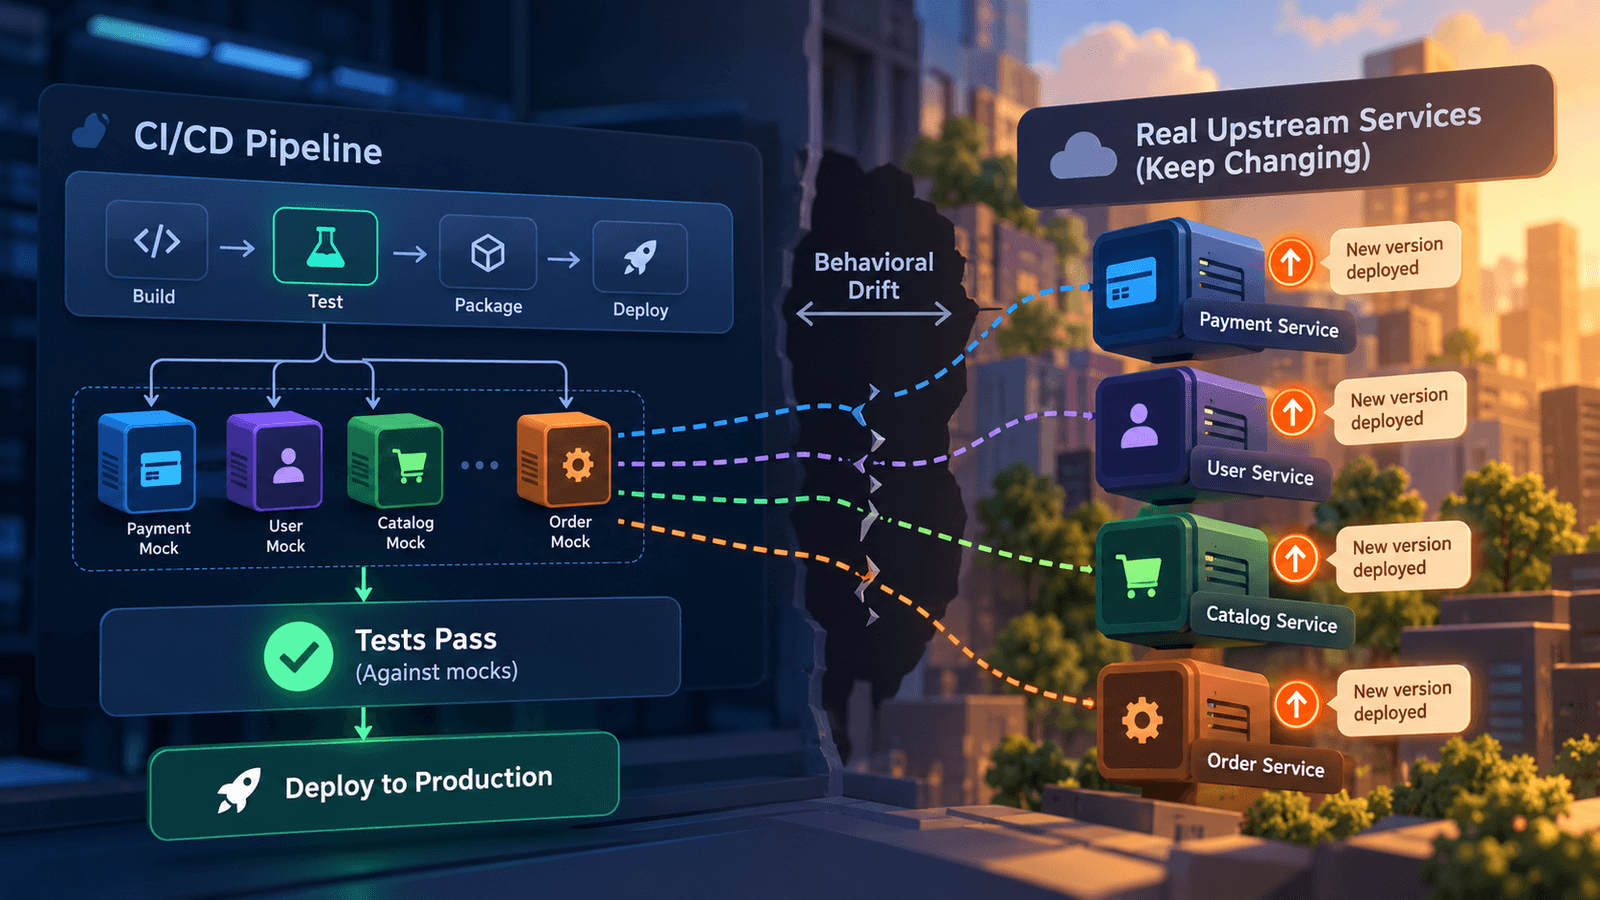
The article explains that dependency mocking can quietly undermine the reliability of CI/CD pipelines because mocks often drift away from the real behavior of upstream services. A pipeline may appear healthy — tests pass consistently, runtimes are stable, and flakiness seems low — yet still provide misleading assurance because it is validating code against outdated assumptions. As upstream microservices evolve through frequent independent deployments, mocks remain frozen in time, creating a widening gap between test environments and production reality. This leads to “operational reliability” without “informational reliability,” where the pipeline runs smoothly but no longer predicts how the software will behave once deployed. The piece stresses that every upstream deployment is a potential accuracy event for mocks, and without automated refresh mechanisms, pipelines accumulate silent risk. It also notes that teams often misinterpret green builds as proof of correctness, even though the pipeline has no visibility into real service behavior during test execution. The article’s steady message is that meaningful reliability requires connecting mock maintenance to upstream changes and validating mocks against real traffic so test results continue to reflect production truth.

Read Original Article →

The Great AI Regret: Why AI Fatigue Is a Leadership Problem, Not a Technology One

Despite the heavy investment in artificial intelligence, many employees feel increasingly anxious and disconnected from their work. Recent research shows a significant portion of knowledge workers are deeply nostalgic for how they worked before AI, and some would even prefer to remove these tools entirely. This growing fatigue and mistrust do not stem from the technology itself, but from poor leadership and implementation. Instead of freeing staff from tedious tasks, rushed rollouts often leave employees feeling surveilled, stripped of their creativity, and unfairly measured against machines. In many cases, people spend more time checking AI-generated output than they save by using it. To solve this problem, leaders must change their approach. Organizations should clearly communicate why these tools are being introduced and ensure they support meaningful work rather than just pushing for blind efficiency. By preserving human expertise and keeping people in control of important decisions, businesses can rebuild trust. When introduced thoughtfully, AI can be a helpful assistant rather than a source of frustration, leading to a much healthier workplace.

Read Original Article →