Showing posts with label business continuity. Show all posts

Daily Tech Digest - October 22, 2026

Quote for the Day
“Debugging is twice as hard as writing the code in the first place.”
— Brian Kernighan
Audio Edition — Listen to Today’s Digest
Narrated version of the Daily Tech Digest
Article Thumbnail

14 ways attackers abuse cloud services to hack your enterprise

As enterprises migrate to hybrid and cloud environments, cyberattackers are evolving from "living off the land" to "living off the cloud," blending malicious activities into legitimate business traffic. Instead of relying on traditional malware that triggers alarms, adversaries are increasingly abusing trusted APIs, native administrative tools, and SaaS platforms to bypass conventional defenses. Attackers route command-and-control communications through reputable services like OpenAI, Microsoft Graph API, and Google Sheets, making the traffic look like routine developer or employee activity. They also exploit cloud identities, such as OAuth tokens and service accounts, to move laterally and access sensitive data without needing to compromise local servers directly. Further tactics include staging malware in object storage buckets, exfiltrating data via everyday tools like Slack, abusing ephemeral serverless functions to mask reconnaissance scans, and weaponizing identity tenant relationships. By exploiting the inherent trust and API-driven nature of modern cloud architecture, these cloud-native attack chains effectively turn the enterprise's operational backbone into a highly evasive attack surface.
Read Original Article →
Article Thumbnail

From Microservices to Agents: the Next Evolution of Distributed Systems

The shift toward artificial intelligence agents marks a significant evolution in software architecture, moving away from traditional microservices. While microservices focused on breaking down complex applications into smaller, predictable parts with clear ownership boundaries, agentic systems focus on distributing decision-making. Instead of following pre-programmed, step-by-step logic, these new AI agents determine their actions dynamically. They analyze the context and their goals in real-time to decide which tools to use and how to sequence their reasoning. This means execution paths are no longer entirely determined during the design phase but adapt as the system runs. While this makes systems more capable of handling complex or vague situations, it introduces new challenges in reliability. The quality of a system's decisions becomes just as critical as its speed or availability. When these systems fail, they often suffer from silent drops in reasoning quality rather than crashing entirely. To manage this effectively, systems need built-in boundaries for the agents, continuous evaluation loops, and reliable fallback mechanisms.
Read Original Article →
Article Thumbnail

How hybrid infrastructure is making quantum commercially actionable today

The quantum computing industry is currently in a critical "prepare for quantum" phase. While fault-tolerant quantum hardware is still developing, organizations cannot afford to wait passively. Integrating geographically isolated quantum processors with enterprise IT through secure, low-latency interconnection is an infrastructure challenge that must be addressed today. This preparation is essential for sectors like life sciences, where delays in drug discovery can be incredibly costly. A prime example is Qubit Pharmaceuticals, which utilizes a hybrid approach with its ATLAS platform. This four-layer system combines high-fidelity physics simulations, a synthetic quantum chemistry data engine, a specialized AI foundation model, and an emulator that simulates up to 40 qubits on classical hardware. By leveraging secure interconnection fabrics provided by partners like Equinix, companies can seamlessly link classical computing, HPC, AI, and early quantum capabilities. Building this hybrid infrastructure now allows organizations to experiment, gain operational familiarity, and seamlessly scale their capabilities as quantum hardware matures, ensuring they are ready to harness quantum utility when it arrives.

Read Original Article →

What Recent Cybersecurity Incidents Teach About the Duty to Mitigate Vendor and Service-Provider Risk

Recent cybersecurity incidents demonstrate that organizations face immense risks from third-party vendors and service providers, shifting the focus from internal defenses to external supply chains. Regulatory bodies increasingly expect companies to maintain a strict duty of vendor oversight, meaning organizations cannot simply outsource accountability for data protection. Real-world examples highlight this shift. The MOVEit software breach showed that companies can face severe legal and financial consequences from a vendor's vulnerability, regardless of their own internal controls. The Change Healthcare attack emphasized operational dependency risk, illustrating the disaster that occurs when a critical vendor goes offline. Furthermore, the PowerSchool lawsuit revealed that oversight must extend to subcontractors who have system access. To mitigate these threats, businesses must integrate vendor oversight into their core governance structure. This requires conducting thorough initial evaluations, negotiating clear contractual protections for incident response, and continuously monitoring vendor security practices. Treating vendor management as an ongoing legal and operational responsibility is essential for maintaining resilience when external failures cause major internal disruptions.

Read Original Article →
Article Thumbnail

The CIO’s new recovery problem: Knowing what ‘good’ looks like

Disaster recovery used to focus primarily on how quickly a business could restore its systems and resume normal operations. Today, modern technology environments are far more complex, spanning cloud platforms, software-as-a-service applications, and constantly changing identities. This complexity sprawl presents a new challenge for technology leaders: figuring out what a healthy system actually looks like before attempting to restore it. Simply bringing a system back online is no longer enough if you cannot guarantee it is secure and trustworthy. To build true resilience, organizations must maintain an accurate inventory and clear dependency mapping while the environment is still functioning properly. Testing a recovery plan must also evolve beyond verifying backups. It should evaluate whether the team can make critical decisions under pressure, understand shifting dependencies, and confirm that the restored environment is safe to use. While speed remains a priority during a crisis, restoring systems without confidence introduces severe risk. Technology leaders must establish a clear definition of a trusted state before an incident ever occurs.

Read Original Article →
Article Thumbnail

When Business Continuity Plans Depend on One Person Knowing What to Do

Even when business continuity plans are well-documented and regularly tested, they often contain a hidden vulnerability: relying too heavily on specific individuals. While organizations meticulously map out system and supply chain dependencies, they frequently overlook personnel dependencies. This reliance becomes clear during a crisis when teams instinctively turn to a single experienced manager, technical expert, or executive rather than following established procedures. The article suggests a straightforward way to expose this weakness during recovery exercises: deliberately remove key personnel from the scenario. If progress halts, deputies hesitate to make decisions, or critical workarounds suddenly become unavailable, the organization has identified a dangerous point of failure. These exercises often reveal that designated alternates lack the practical authority or historical knowledge to step in effectively when the primary decision-maker is absent. Recognizing these human dependencies allows organizations to correct them before a real emergency by formally documenting vital workarounds, transferring knowledge, and granting alternates the real authority they need to lead under pressure.
Read Original Article →
Article Thumbnail

Can AI stop good candidates from getting lost in the hiring pile?

Artificial intelligence is shifting from a basic background tool into an active partner for recruitment teams. As hiring volumes grow, qualified applicants are frequently overlooked simply because recruiters lack the time to review everyone. To solve this, companies are using artificial intelligence voice agents to handle the initial stages of screening. These agents can conduct first-round interviews at any time, answer standard questions about the role, and generate structured reports for the hiring team. This approach eliminates long waiting periods for applicants and ensures every application receives attention. However, technology cannot replace the core of recruitment. While artificial intelligence excels at repeatable tasks and gathering information, the final decision must remain human. Assessing an individual's motivations, understanding how they think, and building a genuine connection require human judgment. Furthermore, companies must be fully transparent when using these tools. Candidates need to know they are speaking with software, not a person. When applied responsibly, this technology prevents strong applicants from falling through the cracks while preserving the vital human element of hiring.

Read Original Article →

Gartner’s top tech trends for 2027 expand—and constrain—AI capabilities

Gartner recently outlined ten strategic technology trends for 2027, focusing on expanding artificial intelligence capabilities while establishing stricter controls. Over the next few years, businesses will move beyond text-based models toward systems designed for complex math, continuous voice reasoning, and physical world simulation for robotics. As these systems produce output faster than humans can review, the second phase emphasizes necessary limits. Organizations will need dedicated frameworks to manage machine identities, verify coding output, and provide specific business context to prevent rogue actions or compliance failures. Automated security patching will also become essential to close vulnerabilities quickly. Finally, looking further ahead, companies will aim to reduce reliance on specific cloud providers by adopting easily replaceable applications and independent technologies. A notable long-term shift involves biological computing, where lab-grown organic systems could eventually handle complex data tasks using far less energy than traditional silicon hardware. By planning across these three horizons, technology leaders can balance autonomous capabilities with the security required for steady operations.
Read Original Article →
Article Thumbnail

Coding Agents Moved the Bottleneck From Writing to Reviewing PRs

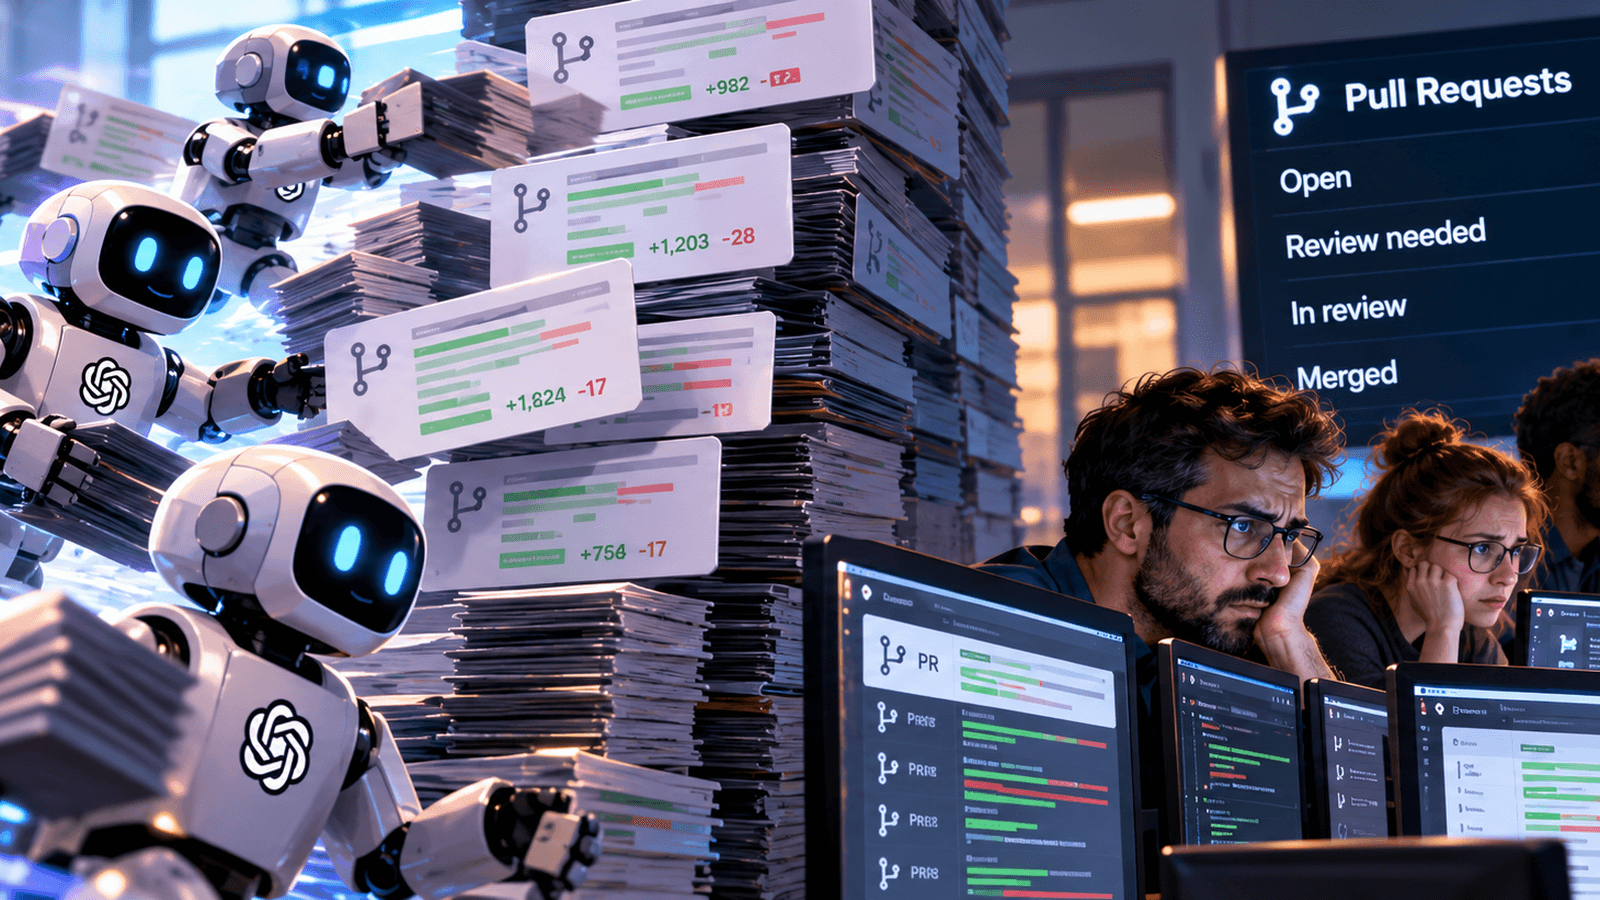
Artificial intelligence coding agents have significantly accelerated software development, but they have also shifted the primary bottleneck from writing code to reviewing it. Because these agents generate larger and more frequent pull requests, the volume of code needing review has outpaced the capacity of human engineers. This growing queue of unreviewed work often remains hidden because traditional productivity metrics focus on generation speed rather than review efficiency. Consequently, development teams face mounting quality debt. Overwhelmed reviewers might miss architectural flaws or security vulnerabilities, especially since AI-generated code typically looks clean and passes basic tests. To address this, organizations must recognize that hiring more reviewers is not a sustainable solution. Instead, they should implement dedicated AI review agents designed specifically to catch errors rather than generate new code. Additionally, capping the size of pull requests and tracking review metrics—such as wait times and review depth—can help maintain software quality without sacrificing the speed gained from AI development tools.
Read Original Article →
Article Thumbnail

Where Should a Transaction End? Designing Consistency Boundaries in Distributed Java Systems

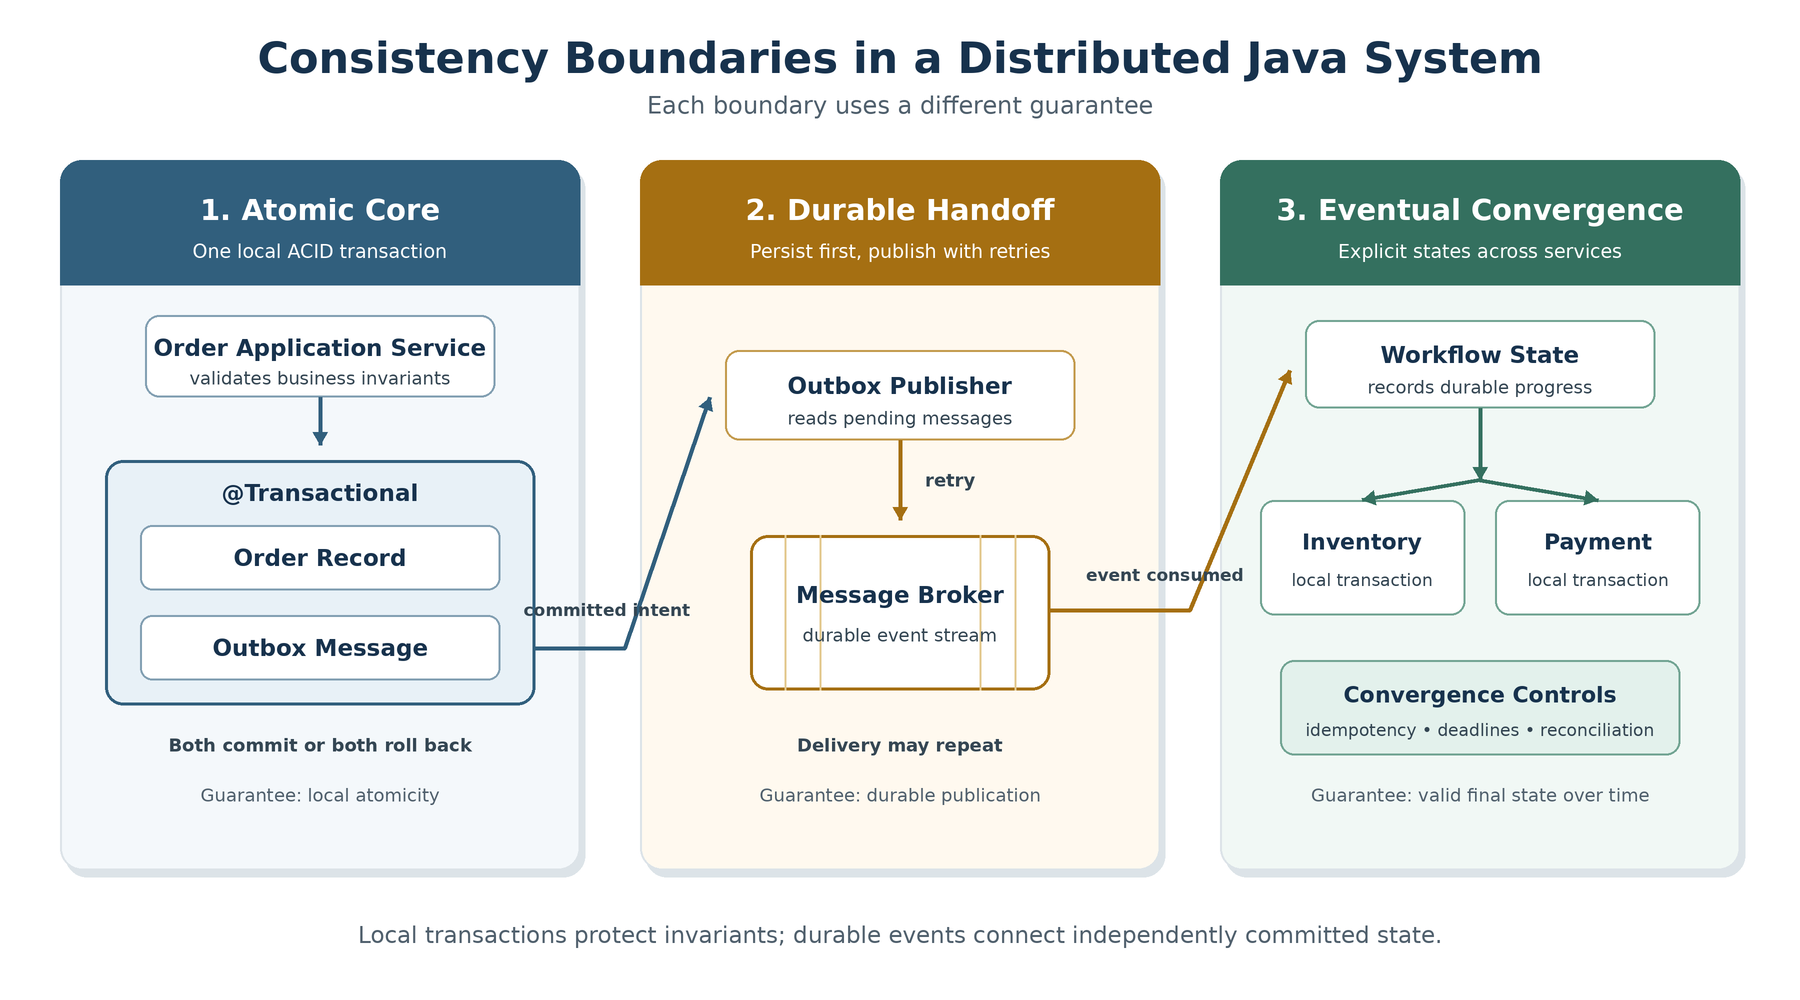
Designing distributed systems forces architects to decide exactly where a transaction begins and ends. Rather than splitting services first and worrying about data consistency later, the best approach starts with defining business invariants. These are the core rules that must always remain true together. The architecture should wrap its boundaries around these facts. When multiple pieces of data must change simultaneously to keep a rule intact, they belong in a single local transaction. Once that core state is secure, the system can use a durable handoff, like an outbox pattern, to safely communicate changes to other components. From there, eventual consistency can manage the broader workflow, but it must be an explicit process with clear recovery paths, not just a vague delay. Relying on synchronous call chains often creates hidden points of failure, so workflows should be modeled as durable states that can survive a crash. Ultimately, separating databases or breaking apart services is only valuable if it respects the underlying business rules that keep the entire system correct.

Read Original Article →

Daily Tech Digest - July 22, 2026


Quote for the day:

“Identify your problems but give your power and energy to solutions.” -- Tony Robbins

🎧 Listen to the audio debrief on YouTube

▶ Play Audio Digest

Duration: 20 mins • Perfect for listening on the go.


Context bombing heralds a new AI era of deceptive defense

The article describes a defensive technique called “context bombing,” which uses the weaknesses of malicious AI agents against them. Attackers increasingly rely on autonomous AI models to speed up every stage of a cyberattack, from reconnaissance to exploitation. To counter this, defenders plant decoy files or secrets that contain short, carefully crafted prompts designed to trigger an AI model’s built‑in safety rules. When a rogue agent reads one of these prompts, it often stops executing its task entirely, halting the attack rather than simply alerting defenders. This builds on traditional “canary” techniques, where fake resources signal unauthorized access, but adds an active disruption layer. Tracebit, the firm behind the approach, tested context bombs in an AWS environment and found they reduced attack success rates by up to 90% by causing models to refuse further action . Because AI agents are vulnerable to prompt injection, hidden instructions placed in documents, DNS records, or environment variables can derail them mid‑operation. As one researcher explained, once the refusal enters the model’s context, “the model will often refuse to continue”. Context bombing heralds a new AI era of deceptive defense. The technique doesn’t replace other defenses, but it buys time, limits damage, and turns attackers’ reliance on AI into a practical point of failure.


Reskilling Mid-Career Leaders: What Senior Talent Needs to Stay Relevant

The discussion focuses on how mid‑career leaders can stay relevant as AI reshapes the workplace. Host Isaac Sacolick and guest Dean Cantave talk about the anxiety many senior professionals feel as their long‑held strengths no longer guarantee future opportunities. They emphasize that staying relevant now requires more than collecting certifications; leaders need to show clear, visible proof of their impact through thoughtful communication, public work, and practical results. Critical thinking, collaborative leadership, and strong data governance skills are highlighted as essential, along with understanding how AI agents and automation change decision‑making and team dynamics. The conversation also notes that leadership roles are becoming more cross‑functional, pushing senior talent to adapt their style, learn new tools, and work more fluidly across departments. Participants share personal stories about career transitions, stressing that credibility today comes from demonstrating how one’s experience translates into modern challenges rather than relying on past titles. They encourage leaders to build a recognizable professional presence, articulate their value clearly, and stay open to continuous learning. Overall, the session frames reskilling not as starting over but as evolving deliberately to match the demands of an AI‑driven workplace.


The Resilience Paradox – Why Autonomous Operations Require a New Approach to Governance

The article argues that as organizations move toward autonomous operations, their traditional governance models no longer fit the reality of how modern systems behave. It explains that observability has matured to the point where most companies can detect issues, but the real question now is how much decision‑making they are willing to hand over to AI. As environments grow more complex and produce more telemetry than humans can reasonably process, AIOps becomes essential for filtering noise and spotting patterns. However, each step toward autonomy reduces human workload while increasing the impact of a wrong automated decision. The piece notes that different teams often advance at different speeds, with platform groups embracing automation early while critical business systems remain manually governed. This uneven maturity creates a “resilience paradox”: delegating more to AI can strengthen reliability, but it also introduces new risks that governance frameworks were not designed to handle. The author stresses that resilience is no longer just about detecting problems but about deciding when systems should act on their own. As organizations shift from observation to autonomous action, they must rethink governance to ensure accountability, manage new categories of risk, and maintain trust in systems that increasingly make decisions without human intervention.


Technology moves faster than ecosystems

The article argues that many digital transformation efforts fail because technology evolves far faster than the ecosystems needed to support it. Companies invest heavily in advanced monitoring, automation, and predictive systems, yet execution performance often worsens. As the author notes, unplanned downtime rose to $1.4 trillion even as digital capability increased, revealing a structural gap where “technology advances faster than the ecosystems required to realize its value.” The paper explains that most industries operate across three maturity tiers, from highly digital enterprises to SMEs still dependent on spreadsheets and email. This mismatch means Tier‑1 intelligence layers can detect problems early, but Tier‑2 and Tier‑3 execution layers cannot respond at the same pace. The semiconductor shortage illustrates this clearly: Toyota’s deeper visibility helped for a time, but “the execution layer… still could not respond on the same timescale.” Workforce capability and physical infrastructure add further delays, evolving over years or decades while technology changes in months. To address this, the author proposes four architectural principles: design for graceful degradation, instrument for friction, build coordination layers, and orchestrate across the ecosystem rather than optimizing only within the enterprise. The core message is that digital transformation succeeds only when decision and execution architectures mature together.


SaaS will survive, but lazy SaaS is dead

The article argues that SaaS is not disappearing, but the old model of “lightweight” SaaS — tools that mainly provide a polished interface over simple workflows — is losing its footing. The author describes an internal review of AI meeting‑transcription tools where the products worked fine, yet the team kept asking, “what exactly are we paying for?” . Because they already had a secure AI environment, they could build the same workflow themselves in days and tailor it to their needs. This experience reflects a broader shift: AI and agentic systems have erased the old advantage SaaS once had, where buying was cheaper and faster than building. Large language models can now move data, call APIs, and automate logic with far less engineering effort, collapsing the integration friction that protected many SaaS categories. The SaaS most at risk are the thin workflow layers — dashboards, meeting tools, narrow productivity apps — whose value rested on simplifying implementation. Agents don’t use interfaces, and they don’t care about switching costs, which weakens the stickiness of these products. The SaaS that endures will be the kind that carries real operational burden for customers, such as compliance, regulatory complexity, or domain‑specific liability. In short, SaaS survives, but “lazy SaaS” — tools that exist mainly because integration used to be hard — does not.


Closing the Identity Gaps in Critical Infrastructure Security

Critical infrastructure remains highly vulnerable to identity‑based attacks, and the article explains why closing those gaps is now essential. It uses the Colonial Pipeline ransomware incident as a clear example, where attackers accessed the network through an inactive VPN account without MFA, leading to a shutdown that disrupted fuel supply across the U.S. East Coast . The piece notes that today’s threat actors, including state‑sponsored groups like Volt Typhoon, rely on stolen credentials, compromised devices, and legitimate remote‑access tools to blend into normal activity and maintain long‑term persistence inside critical infrastructure networks. Because these environments combine IT, cloud services, operational technology, and physical systems, implicit trust becomes dangerous. CISA’s guidance stresses that OT systems require careful handling due to safety and legacy constraints, but the article makes clear that business IT systems can be just as damaging when compromised. The core message is that MFA alone is not enough; organizations must verify both user identity and device trust, enforce segmentation, and continuously monitor for abnormal access patterns. Binding identities to trusted devices and eliminating unmanaged endpoints are highlighted as practical steps. Overall, the article urges critical‑infrastructure operators to adopt zero‑trust principles across both IT and OT so attackers cannot quietly enter, persist, and escalate into national‑level disruptions.


When your vehicle outlives its cloud: What happens next?

The article looks at what happens when a car’s cloud‑based features stop working long before the vehicle itself reaches the end of its life. Modern cars rely heavily on connected services for conveniences like remote locking, cabin pre‑conditioning, vehicle status checks, and emergency assistance. As Ars Technica notes, these features have become standard across brands, from HondaLink to BMW ConnectedDrive, and many owners willingly pay subscription fees to keep them active . The problem is that these services depend on backend systems, cellular networks, and telematics hardware that have much shorter lifespans than the vehicles they support. When networks shut down or manufacturers retire older platforms, owners can lose access to features overnight. A related report highlights how 3G shutdowns caused Lexus, Acura, and BMW to discontinue connected services for older models, sometimes leaving drivers with no upgrade path or costly hardware replacements. The mechanical car remains usable, but the digital layer quietly expires. The article suggests that this mismatch will only grow as more vehicles become internet‑dependent. Without modular hardware or long‑term support commitments, many drivers will eventually face a future where the car still runs but the cloud it depends on does not — raising practical questions about reliability, ownership, and the real lifespan of connected technology.


Designing Multi-Cloud Resiliency for Business Continuity

The piece explains why multi‑cloud strategies are becoming essential for business continuity, especially as outages, cyberattacks, and regional disruptions grow more frequent. It argues that relying on a single cloud provider creates a concentration risk: if that provider suffers a failure, the organization’s critical services may go down with it. Multi‑cloud architectures spread workloads across different providers, reducing the chance that one incident can halt operations. The article notes that this approach is not simply about redundancy; it is about designing systems that can operate even when parts of the environment are degraded. That includes planning for data portability, consistent security controls, and clear failover procedures. The author stresses that resilience requires more than technical configuration. Teams must understand how applications behave under stress, test recovery paths regularly, and ensure that governance policies support cross‑cloud operations. Multi‑cloud also introduces complexity, so organizations need strong visibility, shared standards, and disciplined architecture to avoid fragmentation. The core message is that resilience comes from intentional design: distributing risk, preparing for partial failures, and ensuring that critical functions can continue even when one cloud provider experiences trouble. In a world where disruptions are inevitable, multi‑cloud is presented as a practical way to keep essential services running with confidence.


From the bank branch to the mobile phone: India’s core banking journey

The article traces how India’s banking system evolved from branch‑centric operations to today’s mobile‑first experience, showing that this shift was gradual, uneven, and shaped by both technology and policy. It begins with the early core‑banking era, when banks moved from isolated branch systems to centralized platforms that allowed customers to access services from any branch. This foundation enabled nationwide expansion and consistent service delivery. As digital payments grew and smartphones became widespread, banks shifted again—this time from centralized infrastructure to digital channels that could support millions of small, real‑time transactions. The piece highlights how mobile banking, UPI, and app‑based services transformed customer expectations, pushing banks to modernize legacy systems, strengthen cybersecurity, and redesign processes for speed and reliability. It also notes that modernization is not only about technology; banks had to rethink architecture, improve integration, and adopt cloud‑ready platforms to keep pace with rising transaction volumes. The journey reflects India’s broader digital transformation: a move from physical branches to digital ecosystems that reach rural and urban customers alike. The article closes with a reminder that modernization is ongoing, and banks must continue refining their core systems to stay resilient and competitive in a fast‑changing financial landscape.


What is RPA? A revolution in business process automation

The article explains robotic process automation (RPA) in straightforward terms, focusing on what it is, how it works, and why organizations use it. RPA relies on software “bots” that mimic the steps a person takes on a computer—logging in, clicking buttons, copying data, moving files, and completing routine tasks much faster and without human error. These bots are best suited for high‑volume, rule‑based work on structured data, such as invoice processing, claims handling, report generation, and other repetitive back‑office activities. Because RPA operates at the user‑interface level, it works across existing applications without requiring deep system changes or complex integrations, making it practical for organizations with legacy systems. Sources note that RPA frees employees from tedious tasks so they can focus on work that requires judgment or creativity. RPA is not the same as AI; it cannot learn or make decisions outside its predefined workflow, though pairing it with AI enables more advanced “intelligent automation” capable of handling unstructured inputs or basic reasoning. The article also highlights that RPA can run unattended in the background or assist users directly, and its appeal continues to grow as businesses seek speed, accuracy, and consistency in routine operations. Overall, RPA is presented as a practical, dependable way to streamline repetitive digital work.

Daily Tech Digest - July 17, 2026


Quote for the day:

“If you’re not stubborn, you’ll give up on experiments too soon. And if you’re not flexible, you’ll pound your head against the wall and you won’t see a different solution.” -- Jeff Bezos

🎧 Listen to this digest on YouTube Music

▶ Play Audio Digest

Duration: 20 mins • Perfect for listening on the go.


The executive profile your security team isn’t defending

Artificial intelligence has fundamentally changed how attackers gather intelligence on corporate leaders, turning public data into a significant security risk. In the past, researching an executive required a skilled analyst spending days sifting through search engines and public records. Today, anyone with internet access can use an AI tool to instantly generate a comprehensive profile. These tools do not just return documents; they analyze past statements, map their professional networks, and identify personal interests, handing attackers a ready-made playbook for targeted manipulation and social engineering. To defend against this, organizations must recognize that an executive's digital footprint is a core security issue, not merely a standard public relations concern. Security teams should regularly query major AI platforms to see exactly what information is being synthesized about their leadership. The next step is actively working with executives to reduce unnecessary exposure, such as oversharing on social media or leaving old biographies online. For information that must remain public, security and communications teams should collaborate to ensure the resulting AI narrative does not provide leverage to attackers. Perhaps the most effective way to secure buy-in is simply showing executives their own AI-generated profiles, quickly transforming an abstract threat into an undeniable reality.


Why Business Continuity Programs Fail and How Resilient Organizations Succeed

Many organizations struggle to maintain operations during a crisis because they treat business continuity as a compliance exercise rather than a core capability. Instead of building adaptable strategies, they often rely on static, audit-driven documents that fail to hold up against complex, real-world disruptions. A major reason for this failure is an incomplete understanding of critical dependencies, such as third-party vendors, interconnected systems, and key personnel. When these hidden links break, the disruption cascades. Additionally, companies frequently assume stable conditions during an emergency, neglecting to plan for simultaneous system failures or degraded communication channels. Overreliance on technology is another common pitfall; without manual workarounds, automated failures quickly become insurmountable. Furthermore, ineffective testing practices that merely confirm success rather than expose weaknesses leave teams unprepared for actual chaos. In contrast, resilient organizations focus on end-to-end critical services and constantly monitor their dependencies. They design their operations to function in a degraded state and institutionalize crisis leadership to ensure rapid decision-making. By testing their plans to the point of failure and integrating resilience across all departments, these companies transform business continuity from a rigid requirement into a strategic investment that adapts to evolving threats.


AI Is the Answer for the Banking Industry. But It’s Also the Problem

Artificial intelligence presents a compelling solution for the banking sector, yet it simultaneously introduces a new set of complex operational challenges. On one hand, banks view these digital tools as the answer to established operational hurdles. They use the technology to speed up loan approvals, spot fraudulent transactions instantly, and provide continuous customer support. By automating routine administrative tasks, financial institutions can cut costs and tailor financial products to individual client habits. However, this rapid technological shift is also creating significant difficulties. Many institutions try to install advanced systems on top of fragmented, disorganized databases, which ultimately accelerates internal confusion rather than creating real value. Furthermore, relying entirely on automated reasoning strips away the human empathy and personal judgment necessary for managing sensitive customer relationships. Automated decisions can inherit historical biases, leading to unfair loan rejections for underserved communities. Watchdogs are also raising alarms over systemic risks, such as a lack of transparency in how algorithms make decisions, data privacy flaws, and the danger of widespread, identical system failures. To navigate this shifting landscape successfully, traditional banks must look past the initial industry excitement, focusing their efforts instead on building solid data foundations and maintaining strict human oversight at every stage.


Privacy-Preserving Access: The Architecture Behind Enterprise AI Adoption

As artificial intelligence evolves in the enterprise, its role is shifting from simply providing answers to taking direct action. While early AI tools functioned as basic search engines or text summarizers, newer agents are fully capable of initiating tasks, such as updating supplier records or routing complex workflow exceptions. However, this transition naturally introduces significant new risks. Enterprise data forms the critical operational foundation for everything from modern supply chains to compliance reports and customer experiences. Because of this, organizations are no longer just struggling to connect AI to their data; they are facing the complex challenge of doing so safely. Trust, rather than the technical capability of the models themselves, has emerged as the primary barrier to widespread adoption. To bridge this gap, privacy-preserving architectures must be a foundational requirement rather than a mere compliance afterthought. Companies must rely on established methods like data masking to protect sensitive information while still allowing AI to function effectively. Furthermore, AI-driven actions should not operate with unchecked autonomy. Instead, organizations achieve the best results by separating AI recommendations from actual execution through clear policies, human validation, and strict auditing. Ultimately, the objective is to enable fast, governed action that safely maintains enterprise trust.


5 steps to secure your infrastructure in the frontier model era

As AI evolves, it exposes system weaknesses far faster than engineering teams can realistically patch them. While much attention is placed on scaling hardware like processors and cooling systems, the underlying infrastructure must also be built to withstand new security threats. To protect sensitive data and maintain operations, organizations should take five practical steps. First, infrastructure must be designed with built-in security, using layered controls and hardware protections that anticipate constant probing. Second, uptime should be treated as a strict security requirement, because outdated systems and delayed maintenance create openings for attackers. Third, companies must shift from periodic checks to continuous discovery, addressing vulnerabilities the moment they appear rather than relying on static defenses. Fourth, defending against advanced threats requires using defensive artificial intelligence directly within the system to detect unusual activity and respond without waiting for human intervention. Finally, organizations cannot face these complex challenges alone; they must participate in industry coalitions and share knowledge to counter threats effectively. By prioritizing resilient foundations, treating system availability as critical, maintaining continuous vigilance, using automated defense tools, and collaborating with others, businesses can safely expand their technical capabilities without compromising their daily security or exposing themselves and their customers to unnecessary risk.


The Operational Cost of Fragmented CI/CD - and How to Fix It

The article explains how many companies end up with a patchwork of CI/CD tools and pipelines that grew over time through team preferences, cloud migrations, and mergers. While each choice may have made sense locally, the result is a delivery system that is hard to manage, secure, and scale. The piece highlights the hidden costs of this fragmentation, such as duplicated engineering work, uneven security practices, slow onboarding, and longer incident‑resolution times. These issues often drain time and attention even more than the metrics organizations typically track. The article also notes that forcing everyone onto a single tool rarely works because teams have different needs and constraints. Instead, it suggests creating a unified delivery experience through shared services, pipeline‑as‑code, reusable templates, and clear governance. This approach lets teams keep the tools that suit their work while giving the organization consistency and visibility across delivery processes. The article argues that better observability and platform‑driven practices help reduce complexity and improve reliability. In the long run, solving CI/CD fragmentation becomes an important step toward faster, safer, and more predictable software delivery across the enterprise.


New agentic compute patterns

For the past ten years, Kubernetes has been the standard way to organize and run software in the cloud, perfectly tuned for short, isolated web requests. However, this model breaks down when running modern artificial intelligence agents. Unlike standard web services, agents are long-running, continuous processes that remember past actions, use external tools, and make ongoing decisions. Because of these differences, agents require an entirely new approach to computing infrastructure. Specifically, they need execution environments that start in milliseconds rather than minutes, the ability to pause and resume work without losing memory, reliable ways for multiple agents to collaborate, and secure methods to handle passwords. When companies try to force these new workloads into older systems, they experience frequent failures, wasted computing power, and significant security risks. For example, a cloud system might mistakenly shut down an agent that is waiting for a response simply because it appears inactive. The Kubernetes community has recognized this mismatch and is developing new tools designed specifically for these workloads. Organizations that recognize the need for this dedicated infrastructure early on will build more reliable and secure systems, while those sticking to the old methods will struggle with high costs and constant system errors.


AI At Work: Managing Legal Risk Across The Fast Moving Global Landscape

Artificial intelligence is rapidly transforming the modern workplace globally. While these technologies offer significant opportunities to increase productivity and improve operations, they also introduce a host of complex employment law risks that organizations must carefully manage. From recruitment and daily performance management to overall service delivery and internal communications, AI tools are fundamentally altering how companies operate and make decisions that impact their employees. However, this widespread transformation can trigger serious legal obligations. Employers face potential issues related to discrimination, redundancy, redeployment, required consultation periods, changes to employment contracts, and outsourcing complications. Furthermore, using AI systems for workplace monitoring and productivity tracking creates substantial privacy and data protection risks. These concerns become particularly severe when surveillance data directly influences important outcomes such as work allocation, compensation, disciplinary actions, or terminations. Relying on third-party AI vendors does not absolve organizations of their legal responsibilities, and employers should never view these external tools as a shortcut to compliance. Instead, managing the legal risks associated with workplace AI requires careful planning. Responsible integration of these technologies must begin with establishing strong internal governance, prioritizing comprehensive employee education, and implementing clear risk management strategies to ensure fairness and legal compliance across the entire employment lifecycle.


Why Self-Awareness Is The Key To Leadership

This article, written by Dr. Shaoqing Sun, discusses self-awareness as an essential foundation for leadership. He begins by recounting his own struggles, explaining how an ego-driven mindset negatively affected his home life and how those same flaws seeped into his professional life. He emphasizes that a leader's unconscious habits inevitably impact all of their interactions, meaning true leadership is about what a person transmits to others rather than just what they achieve. Self-awareness is critical because it bridges the gap between how leaders see themselves and how their colleagues actually experience their actions. Without it, leaders may fall into a self-referential trap where they think highly of their performance while others struggle with the consequences of their behavior. Sun stresses that self-awareness shouldn’t just be a quick fix during a crisis but must be a consistent, daily practice—much like maintaining a friendship. This continuous practice helps leaders recognize and stop negative behaviors before they cause harm. Ultimately, he argues that cultivating this level of emotional maturity leads to a deeper, more conscious style of leadership that moves beyond ego and fear.


Resilience over prevention as AI reshapes security landscape

Organizations are shifting their cybersecurity strategies from trying to block every attack to ensuring they can recover effectively when one happens. Because artificial intelligence has made threats faster and more complex, businesses accept that complete prevention is no longer realistic. Errors and new types of attacks will always find a way through. As a result, companies are moving a larger share of their security budgets toward recovery efforts instead of focusing almost entirely on prevention. A major challenge during an incident is balancing the desire of management to get systems back online immediately with the need of the security team to ensure the restored network is truly safe. Security professionals note that artificial intelligence speeds up attacks but also helps defenders minimize damage, creating an ongoing arms race. Beyond external threats, companies face internal risks from employees accidentally sharing sensitive data with public artificial intelligence tools. This makes proper data management and employee education essential. Furthermore, because many attacks start by stealing user credentials, protecting digital identities has become just as critical as protecting the data itself. Ultimately, experts advise that organizations should operate on the assumption that a breach will occur and prioritize their ability to restore operations quickly and securely.

Daily Tech Digest - July 11, 2026


Quote for the day:

“The people who are crazy enough to think they can change the world are the ones who do.” -- Steve Jobs

🎧 Listen to this digest on YouTube Music

▶ Play Audio Digest

Duration: 24 mins • Perfect for listening on the go.


AI Coding: Do Security Risks Outweigh Productivity Gains?

AI coding tools are transforming software development, with widespread adoption driven by the promise of automating repetitive tasks and boosting productivity. Most developers report saving time and delivering features faster, making these tools highly attractive. However, beneath these clear benefits lie significant security risks and hidden costs that require careful consideration. While AI models write code quickly, they often train on outdated or insecure libraries. Consequently, developers frequently encounter code that looks functional but introduces critical vulnerabilities or relies on hallucinated software packages. A major concern is the alarming increase in leaked secrets and hardcoded credentials, which require time-intensive cleanup efforts that drain engineering resources. Security teams report spending up to forty percent of their time simply sorting through false positives generated by AI-assisted code. The financial aspect is equally complex. The base subscription costs for these tools are rising, and when combined with the added expenses of security scanning, triage, and infrastructure, the overall investment can be substantial. Whether these tools provide a positive return depends heavily on the industry. Fast-paced consumer applications might justify the expense through sheer agility, whereas slower-moving sectors may struggle. Ultimately, adopting AI coding requires strict security hygiene and realistic expectations about its true cost to your organization.


Building Customer Identity at Scale: Lessons from 1 Billion Users

Building a customer identity and access management (CIAM) system at scale goes far beyond basic login functionality. It sits at the intersection of user experience, security, and scalability. Based on insights from managing over a billion users, one of the most effective strategies is replacing traditional, lengthy registration forms with progressive profiling and contextual authentication. Instead of forcing users to provide all their personal details upfront—which often leads to high abandonment rates and fake data—companies should start with minimal requirements, such as an email and a passwordless login method. Additional details can then be requested gradually as they become contextually relevant, like asking for a shipping address only when a purchase is made. Simultaneously, contextual authentication analyzes behavioral signals—like location and device—to adapt security measures dynamically. Low-risk activities remain frictionless, while high-risk actions prompt multi-factor authentication. This approach reduces registration abandonment, drops support tickets, and surprisingly strengthens security by catching anomalies that standard passwords miss. When migrating millions of users to new identity systems, the biggest hurdle is psychological, not technical. Proactive, clear communication, dedicated support, and maintaining visual continuity are essential to retain user trust. By treating identity management as a relationship rather than just infrastructure, businesses can significantly improve conversion rates and customer satisfaction.


Relearning cloud lessons from runaway AI token costs

Just like the early days of cloud computing, generative AI is causing unexpected and massive spikes in technology spending for many organizations. AI token costs are often running 10 to 20 times higher than initially projected, largely because AI agents require roughly 50 times more computing power per task than traditional chatbots. Because costs fluctuate based on usage, query complexity, and model size, organizations are struggling to stick to their budgets. To bring these costs under control, companies are returning to "FinOps" — the financial operations strategies originally developed to manage cloud spending. The most successful organizations apply a core set of practices: making spending visible, attributing costs directly to the teams responsible (a method known as "show-back"), and setting strict usage alerts. When teams see the direct financial impact of their AI consumption, they naturally begin to optimize. This means choosing smaller, more cost-effective models for simpler tasks rather than defaulting to the most expensive, advanced options. Ultimately, organizations that treat AI tokens as a managed operational expense rather than an unpredictable variable are the ones successfully taming their generative AI budgets.


The Executive Cyber Risk Report: July 2026 Edition

The mid-2026 cyber risk landscape shows a clear shift, combining the risks of older, outdated software with new, AI-related threats. Recent events highlight this change. For instance, a flaw in an older Oracle system led to a major data breach, while companies like Novo Nordisk faced the theft of valuable AI research. Furthermore, an attack on a healthcare vendor exposed patient information, proving that a company's security is only as strong as its external partners. Beyond external attacks, new risks are growing inside organizations. Employees using unapproved AI tools can accidentally leak sensitive information. Additionally, criminals are using AI to create highly convincing phishing emails and trick AI coding assistants into running harmful commands. In response, regulations and insurance rules are tightening. New federal rules now require critical infrastructure companies to report major incidents within 72 hours. Cyber insurance providers are also demanding proof of clear AI safety rules and continuous security tracking before offering coverage. To protect their organizations, leaders must take calm, decisive action. This involves strictly evaluating the security of all external vendors. It also requires creating a clear, company-wide policy for safe AI use. Finally, organizations must adopt stronger, modern login protections to defend against increasingly clever phishing attempts.


Enterprise AI is entering an evaluation gap: Agents are gaining autonomy faster than companies can verify them

Companies are rapidly granting artificial intelligence systems more independence, yet their trust in the testing methods used to verify these systems is actually dropping. This creates an evaluation gap where the freedom given to AI outpaces the ability to ensure it works properly. A recent survey reveals that half of surveyed businesses have released AI tools that passed internal checks but later failed when interacting with customers. Despite these setbacks, the majority of companies still plan to allow AI deployments without human review within the next year. Testing these systems is inherently difficult. Unlike standard software, AI systems choose their own steps and can respond differently each time they run. They might complete several steps correctly but make a critical error at the end. Consequently, business leaders distrust automated testing because high scores often do not match real-world performance. A single successful test does not guarantee consistent results, making reliability a crucial metric that needs strict evaluation. To move forward safely, organizations should adjust AI independence based on the risk associated with a task. Low-risk tasks can operate with more freedom, while sensitive actions require strict limits and human oversight. Ultimately, the most successful companies will prioritize consistent testing and reliability just as highly as deployment speed.


Disaster Recovery Tabletop Exercise: A CIO's Step-by-Step Guide

A disaster recovery tabletop exercise is a guided discussion where key team members talk through a simulated emergency, such as a cloud outage or a ransomware attack. Unlike a live technical drill that requires taking systems offline, a tabletop exercise allows a company to test its recovery plans in a low-risk setting. Its primary goal is to find hidden gaps in communication, technical procedures, and decision-making before an actual crisis occurs. For technology leaders, these exercises are highly valuable. They help determine if a critical process relies too heavily on a single person or if the expected recovery timelines align with what the business actually needs. Furthermore, running these drills provides strong proof that the organization meets major security compliance standards. To get the most out of a session, organizations should set clear goals, choose a realistic threat, and introduce unexpected twists during the exercise to test how well the team adapts under pressure. Free resources, such as those provided by the Cybersecurity and Infrastructure Security Agency (CISA), can provide a strong foundation for building these scenarios. Ultimately, tabletop exercises build the confidence and coordination required to handle real emergencies smoothly and effectively.


The Five Stages Of Organizational Failure

When companies face major restructuring or layoffs, leaders often rush to blame external factors like market shifts or artificial intelligence. However, organizational failure rarely starts with outside forces; it typically follows a predictable five-stage pattern. The first stage is denial, where leaders ignore changing realities and stick to outdated plans. When denial breaks down, the second stage, anger, sets in. This anger can result in rushed, destructive decisions or be channeled into fixing the actual problem. The third stage is blame, a dangerous trap where companies point fingers at convenient excuses—like AI—instead of taking responsibility for their next steps. To survive, organizations must reach the fourth stage, reflection. This means conducting an honest, uncomfortable review of why things went wrong and which assumptions failed. Finally, the company reaches acceptance, which is not surrender, but rather a clear acknowledgment of the new reality and the foundation for rebuilding. The true role of leadership is moving an organization through these stages intentionally. Rather than waiting for conditions to improve or hiding behind comfortable excuses, leaders must use failure as valuable data, confront the damage directly, and focus on building a sustainable path forward.


When Criticality Outpaces the Plans: Why Business Continuity Must Redefine ‘Criticality’

For decades, businesses have used impact analysis to figure out which of their systems and assets are the most important. Traditionally, companies assumed that once they labeled a function as vital, it would stay that way until the next annual review. However, today's operating environments rely heavily on interconnected networks, supply chains, and external services, meaning risk changes quickly. An asset that seems minor during normal operations can suddenly cause a massive failure if a specific relationship or process breaks down. Because of this, organizations need to stop treating importance as a fixed label and start viewing it as a flexible state. The article introduces a framework based on adaptive importance, suggesting that leaders must evaluate how an asset's role might shift under stress. This involves looking at real-time changes, understanding how small parts can become major vulnerabilities, analyzing the exact position of an asset within a broader network, and recognizing that importance changes at different stages of a crisis. To stay secure, companies should update their priorities based on real-world shifts rather than a rigid calendar. Using artificial intelligence can help track these complex, hidden connections and spot changes early. Ultimately, true preparation means anticipating what might become essential tomorrow, rather than just protecting what seems important today.


Trade-Offs in Multi-Region Architectures: Latency vs. Cost

The decision to expand cloud infrastructure into multiple geographic regions is far more complex than simply weighing lower latency against the monthly cost of new servers. According to the InfoQ article on multi-region architecture, opening a new region typically adds roughly forty percent to incremental infrastructure costs. This figure includes expensive cross-region network connections, service setup, and data replication, even before factoring in the day-to-day operational overhead of managing new systems. While active-active architectures are excellent for reducing wait times for end users, they require constant data syncing that can drive operational costs up by twenty to thirty-five percent. As a result, businesses often find more balanced success by pairing latency goals with specific data sovereignty and compliance requirements to justify the steep investment. For many read-heavy systems, organizations can achieve up to eighty percent of the latency benefits simply by using smarter DNS routing rather than fully replicating data across regions. To keep expenses from spiraling out of control during a global expansion, companies must right-size their regional footprints and aggressively automate setups to reduce manual coordination. Ultimately, a new region only makes financial sense if teams can eliminate long-distance dependency chains and ensure their systems are structurally prepared for the added complexity.


Why the Next Technology Revolution Will Be Built on Invisible Infrastructure

While headlines focus on artificial intelligence and autonomous systems, the next major technology shift will actually rely on something most people never see: digital infrastructure. Every major leap in technology, from the internet to cloud computing, has depended on a solid foundation. Today, the success of modern applications requires complex, underlying systems like enterprise architecture, secure data platforms, application programming interfaces, and embedded cybersecurity. These elements form the invisible infrastructure that allows digital innovation to happen smoothly and securely. Artificial intelligence, for example, cannot function well without clean, governed data and fast computing networks. Similarly, modern cloud platforms have moved beyond tools for saving money to become the operational engines that drive rapid development and disaster recovery. Even cybersecurity is shifting from a basic protective wall to an integrated feature that supports safe innovation across every level of a business. Rather than treating these technical systems as basic support functions, smart organizations now view them as critical business assets. Customers may not notice the complex integration of banking platforms or supply chain networks, but they directly experience the results: faster services, secure transactions, and reliable applications. Ultimately, the companies that invest heavily in this unseen foundation today will be the ones equipped to lead the digital economy tomorrow.

Daily Tech Digest - May 30, 2026


Quote for the day:

“Any fool can write code that a computer can understand. Good programmers write code that humans can understand.” -- Martin Fowler

🎧 Listen to this digest on YouTube Music

▶ Play Audio Digest

Duration: 18 mins • Perfect for listening on the go.


AI-Driven Bug Tsunami Prompts Exploitability Questions

The article outlines how artificial intelligence has driven a massive increase in software bug reports, pushing the Common Vulnerabilities and Exposures system toward another record year. While major platforms like Chrome and GitHub have seen a large number of reported flaws, security researchers emphasize that most of these automated findings present very little real threat. Historically, fewer than two percent of all reported vulnerabilities are actually exploitable, and current telemetry indicates that only a tiny fraction are ever widely used by attackers. A primary issue is that automated tools often generate reports that lack necessary context regarding severity, practical reachability, and real world impact, creating an unnecessary administrative burden for software maintainers who must sort through low quality duplicates. In response, open source projects like the Linux kernel and platforms like GitHub have tightened their guidelines, now requiring functional proof of concept demonstrations before prioritizing a bug or issuing rewards. Furthermore, even advanced models like Anthropic’s Mythos, despite their ability to chain minor bugs into serious exploits, have not altered underlying risks significantly. Traditional security measures and defense in depth principles remain effective. By ensuring systems are built with multiple layers of security, organizations can ensure a single software flaw will not compromise an entire product.


AI and connected systems are forcing CIOs and COOs to rethink OT security

Historically, organizations kept operational technology, such as factory equipment and utility infrastructure, isolated from corporate IT networks to maintain security and safety. However, the search for efficiency has pushed companies to introduce connected sensors, cloud data, and artificial intelligence into these industrial spaces. While this change offers clear business advantages, it also creates significant cyber risks. Older operational equipment was never designed for internet connectivity, making standard software updates or sudden network shutdowns highly impractical. Furthermore, the integration of autonomous artificial intelligence systems complicates defense strategies because they constantly exchange data with outside networks while relying on legacy internal frameworks. To address these vulnerabilities, chief information officers and chief operating officers must move away from isolated management practices and embrace shared responsibility. This coordination is essential because typical corporate security tactics, like instantly isolating a compromised system, can disrupt manufacturing schedules or cause physical damage on the factory floor. Instead of trying to replace decades of old equipment immediately, leadership teams should focus on improving basic operational visibility, monitoring the network access of outside contractors, and deploying stricter identity verification checks. Taking a deliberate, phased approach to securing these blended environments allows companies to manage hidden threats much more effectively while keeping critical machinery running safely.


Accelerating Data Strategy and Governance with AI

According to a Dataversity article featuring insights from Peter Aiken, many organizations fail with their data strategies because they treat them as static documents to be completed and shelved rather than ongoing processes. Consequently, a vast amount of corporate data often remains redundant or obsolete. To fix this, an effective data strategy should serve as a continuous pattern of choices that aligns information assets directly with broader business goals. Aiken suggests utilizing a cyclical method focused on addressing constraints, where teams repeatedly isolate and resolve single bottlenecks to build small, incremental advantages. Data governance teams provide the necessary routine execution, though they frequently face common hurdles like cultural resistance, confusion, or competing technology priorities. Artificial intelligence serves as a practical tool to ease these operational burdens and expand human worker capabilities. Rather than replacing professionals, AI automates tedious administrative chores such as labeling data, mapping information lineage, checking security risks, and updating quality rules. This shift reduces internal friction and allows data stewards to spend their time on important strategic planning. Ultimately, combining cyclical improvements with automated support helps companies steadily improve their data quality, mitigate security risks proactively, and turn abstract strategy documents into practical business actions.


India has already witnessed increasing cyber targeting of critical infrastructure sectors

In this interview, Vaibhav Dutta of Tata Communications discusses the growing cybersecurity risks facing India’s critical infrastructure as industries embrace digital modernization. As sectors like energy, utilities, and manufacturing integrate isolated operational technology with enterprise IT, cloud networks, and automated systems, they inadvertently widen their exposure to external threats. This shift changes the nature of these threats from basic data breaches to complex physical disruptions capable of destabilizing essential public services. India has already seen an uptick in malware and remote access exploitation targeting its power grids and manufacturing setups. Dutta points out major vulnerabilities in current industrial upgrades, particularly a severe lack of visibility over legacy equipment, insecure remote access pathways, and unprotected application programming interfaces. Furthermore, many organizations mistakenly treat security as a compliance box to check rather than a core operational necessity. To mitigate these risks, the text advocates for building safety controls directly into systems during the initial planning stages of any digital expansion. Moving forward, safeguarding these interconnected environments will require a unified approach that blends traditional computer network security with physical operational safety, relying on continuous verification models and intelligent monitoring to detect anomalies and maintain continuity even during an active cyber attack.


The AI inventory is the EU AI Act artefact most teams underestimate

The Information Age article highlights why the AI inventory required by the EU AI Act is a critical component that corporate teams routinely underestimate. Rather than treating it as a superficial list or spreadsheet of active tools, organizations should view the inventory as a map that connects every artificial intelligence application to real business processes. A weak register merely names products like chatbots or analytics software. In contrast, a truly comprehensive inventory details business and technical owners, data inputs, intended outcomes, human review steps, and clear accountability trails. This deep level of clarity helps prevent the common issue of ownerless systems, where unmonitored technology leads to gradual shifts in purpose and completely untracked updates. While creating an inventory does not automatically ensure legal compliance or replace deeper security and privacy reviews, it establishes the necessary shared baseline record that different departments require to work together effectively. Technology executives play a central role here because standard legal or compliance teams rarely notice the automated features quietly embedded inside third-party corporate software platforms. Ultimately, maintaining a clear and current register enables legal, security, and operational units to understand exactly what they own, paving the way for structured risk management as new regulations phase in.


Kindness and Critical Infrastructure: Rethinking OT Security

In episode 52 of the Hack the Planet podcast, titled "Kindness and Critical Infrastructure," host Bryson Bort interviews Andrea Haddad, an infrastructure architect working at a pharmaceutical manufacturing organization. Haddad shares her transition from traditional IT network engineering to the world of operational technology, where safety and production take top priority. She highlights a common tension between maintaining strong security and ensuring daily workplace convenience. For example, forcing factory technicians to manage multiple complex passwords for remote access often leads to frustration and risky habits, like password reuse. Furthermore, external equipment suppliers frequently push back against corporate network rules, sometimes introducing unauthorized remote connections that create visibility blind spots. Haddad notes that while theoretical frameworks like the Purdue model offer helpful blueprints for layering networks and establishing equipment standards, strict solutions cannot be imposed instantly. Instead, she argues that lasting security relies heavily on mutual listening and empathy, choosing kindness over rigid enforcement. Because production downtime causes massive financial losses, security teams must understand the real-world constraints under which plant engineers operate. Ultimately, true system protection comes from a continuous process of learning, open communication, and building a practical middle ground that safeguards equipment without disrupting daily work.


How to Ideate in Design Thinking: What Works, What's Overhyped, and What's Changing

The Eleken article highlights that coming up with fresh product ideas is often misunderstood as a rigid, workshop-heavy process that smaller teams cannot afford. In reality, effective problem-solving is simply about pushing past the first few obvious choices, which are usually the same generic concepts your competitors have already considered. Traditional group brainstorming sessions frequently fall short because the loudest voices dominate the room, participants fear judgment, and early suggestions accidentally restrict everyone’s thinking. To bypass these social limitations, teams can use practical alternatives like the bad idea challenge, which removes performance pressure by asking people to deliberately invent terrible solutions that can later be flipped into useful features. Other effective approaches include studying solutions from completely unrelated industries or using imaginary scenarios to challenge basic assumptions. Furthermore, artificial intelligence is steadily changing how teams work by quickly producing hundreds of starting layouts and options. Instead of replacing human creativity, these software tools handle the heavy lifting of initial volume, allowing designers to dedicate their time to reviewing, editing, and perfecting the best directions. Ultimately, the article suggests treating design thinking as a flexible toolkit rather than a strict textbook rulebook, matching the core principles to actual product timelines and real-world project constraints.


Cloud spend is now a governance issue. Finance and IT need a new model

The article highlights the shifting nature of cloud and AI infrastructure costs, framing them not as a purely technical or financial problem, but as a critical governance challenge. Traditional static budgeting models and retroactive approvals fail to match the reality of modern cloud consumption, where expenses fluctuate dynamically based on daily engineering decisions and varying workload demands. Consequently, companies frequently deal with wasted spending, often due to overprovisioning or unutilized cloud resources. To solve this, finance and technology departments must work together more closely, adopting a shared framework commonly known as FinOps. This collaborative approach distributes financial accountability directly to product and business teams, linking cloud costs directly to performance and measurable business value. By establishing metrics like cost allocation coverage, forecasting accuracy, and unit economics, such as the cost per transaction or model inference, finance leaders gain deeper context into what their spending actually accomplishes. This visibility creates a shared understanding between engineering and corporate finance, helping teams make better everyday design choices. Ultimately, the text argues that companies focusing merely on reducing costs will struggle, whereas organizations that actively manage the business value of their cloud investments can turn structural volatility into a distinct operational advantage.


Stragglers, Not Failures: How Adaptive Hedged Requests Reduce p99 Latency by 74 Percent

This InfoQ article discusses how adaptive hedged requests can effectively manage extreme response delays in distributed computer networks. In large systems, overall performance is often slowed down not by outright errors, but by requests that eventually finish but take far longer than usual due to temporary glitches like background garbage collection or minor network bottlenecks. While software engineering teams often use retries to fix these issues, resending a slow request can accidentally overload an already struggling back-end server. Instead, a hedged request proactively sends a duplicate backup request if the initial attempt takes too long, accepting whichever response returns first and canceling the slower peer. To avoid the pitfalls of static timing limits, which require constant manual adjustments as traffic patterns shift throughout the day, the author introduces an automated system. By using an open-source statistical tracking tool called DDSketch, this setup continuously analyzes real-time response times to establish accurate thresholds naturally. Additionally, a built-in safety mechanism uses a token bucket budget to cap duplicate traffic, ensuring that the system handles problems gracefully rather than multiplying load during genuine outages. Ultimately, this approach works best for repeatable operations that do not change database state across multi-instance environments.


From resilience to survivability: How AI forces a rethink of business continuity

The article by Zeus Kerravala explains how artificial intelligence is changing corporate business continuity, pushing organizations to move past traditional recovery plans toward a model of continuous survivability. Historically, maintaining business operations during an unexpected network outage meant relying on simple secondary backups. However, these systems often share hidden technical dependencies, such as the same cloud providers or identity management tools. Because modern AI workloads are deeply interconnected and control real-time decision-making systems, any downtime creates severe immediate consequences and steep financial losses. To address these vulnerabilities, businesses are adopting architectural independence, which involves running separate, parallel environments with isolated data pathways and distinct operational teams. This approach ensures that a failure in the primary system does not spread to the backup. Furthermore, companies must view AI as both a major security risk and a helpful recovery asset. On one hand, automated models introduce supply chain risks and potential data corruption. On the other hand, they can predict infrastructure failures and trigger self-healing protocols. Ultimately, technology and enterprise leaders are advised to thoroughly map their complex system dependencies, test for total model failures, and transition from reactive troubleshooting to building autonomous safeguards that keep essential operations running smoothly during unexpected disruptions.