Showing posts with label Vulnerability Management. Show all posts

Daily Tech Digest - August 31, 2026


Quote for the day:

"Little minds are tamed and subdued by misfortune; but great minds rise above it." -- Washington Irving

🎧 Listen to the audio debrief on YouTube

▶ Play Audio Digest

Duration: 24 mins • Perfect for listening on the go.


AI agents need their own identity before they need a gateway

As enterprise artificial intelligence moves from simple assistants to independent tools capable of completing complex tasks on their own, organizations face a completely new set of security challenges. Traditional software operates on predictable rules, but modern AI programs make decisions on the fly, choosing how to use resources and systems to reach a goal. Because of this unpredictability, simply verifying the login credentials of an AI tool is no longer enough to keep networks safe. Even with the correct permissions to access important platforms, an AI might misunderstand its purpose, encounter manipulated information, or drift from its original intent. To address this, organizations must shift their focus to continuous observation, monitoring what the AI actually does while it runs. Security teams need to enforce strict rules about the specific actions an AI can take, rather than just limiting the files it can view. By applying the principle of least privilege, tracking behaviors for unusual patterns, and requiring human approval for risky choices, companies can protect their systems from unexpected errors. Building this foundation of constant oversight allows businesses to deploy autonomous AI safely and responsibly, ensuring these advanced tools remain helpful and aligned with organizational goals from start to finish.

The hidden cost of data sovereignty: When governance prevents scaling

Data sovereignty rules mandate that information stays within specific geographic or legal borders, which originally aimed to protect user privacy and national interests. However, strictly governing where and how data is stored introduces significant challenges when a company attempts to scale its operations globally. Because organizations must comply with varied local regulations, they are often forced to build isolated technology infrastructures for each region. This approach fragments the underlying systems and prevents the seamless flow of information that modern businesses rely on for efficiency. Instead of deploying a single, unified solution, companies end up maintaining multiple parallel environments, which duplicates effort, drains technical resources, and inflates operational budgets. Furthermore, the administrative overhead required to manage these diverse compliance requirements slows down decision-making and delays the rollout of new products or services. While robust governance is entirely necessary to meet legal obligations and maintain customer trust, it can unintentionally create rigid barriers. Business leaders must strike a careful balance between adhering strictly to local mandates and preserving the operational flexibility needed to grow. Without a thoughtful strategy that aligns regulatory compliance with infrastructure design, the ambition to expand into new markets can quickly become hindered by the very rules meant to keep data safe.


Cybersecurity Influence Starts With Explaining Risk Clearly
Cybersecurity experts often excel at finding and fixing technical flaws, but they frequently struggle to translate these risks into language that business leaders can easily grasp. According to a recent discussion between Dustin Sachs and Heather Antoinetti, relying solely on technical accuracy is not enough to drive real change. When security professionals present dense data without clear context, executives may fail to understand the urgency, leading to underfunded or ignored safety measures. To bridge this gap, technical teams must rethink how they communicate. Instead of diving into the detailed mechanics of a problem, they should focus on telling a clear story about what went wrong, how it was resolved, and how it impacts the broader organization. This approach is not about dumbing down the facts; it is about knowing the audience and turning abstract threats into practical business realities. Furthermore, experts need to step out of the shadows, overcome their hesitation to speak up, and actively position themselves as helpful resources rather than quiet observers. Finally, by moving away from aggressive language and toward a tone of partnership, security teams can build better relationships across their organizations. Ultimately, clear communication is a vital component of effective risk management and organizational trust.


From pressure to proof: Leading through constraint in the data center era

Leading a data center team today requires navigating a landscape defined by significant limitations. Demand for computing power continues to grow rapidly, yet operators face very real constraints regarding electricity, available land, and equipment supply chains. The article explains that overcoming these hurdles is not about finding quick fixes but rather about changing how teams think and operate. Leaders must guide their organizations through a necessary mindset shift, moving away from a focus on rapid, unconstrained expansion and toward a disciplined approach based on resourcefulness and clear evidence of performance. Instead of viewing constraints as roadblocks, teams can learn to treat them as parameters that guide smarter decisions. This transition takes a group from feeling overwhelmed by external pressure to confidently providing proof of their capabilities. When resources are tight, success depends on careful planning, clear communication, and a focus on practical solutions rather than chasing the latest trends. By adopting this steady, pragmatic approach, leaders can help their teams build systems that are both reliable and adaptable. Ultimately, thriving in this constrained era is about doing more with the resources available and building a solid foundation that stands up to scrutiny, proving that careful management overcomes broad industry challenges.


Post-Quantum Cryptography in Spring Boot: Four Patterns You Can Ship This Sprint
The article from InfoQ discusses practical approaches for integrating post-quantum cryptography (PQC) into Spring Boot applications, especially critical for heavily regulated sectors like retail banking. With quantum computing expected to break classical encryption like RSA and ECDSA by 2030-2035, the immediate risk is "Harvest Now, Decrypt Later" (HNDL). Adversaries are already intercepting and storing encrypted traffic to decrypt in the future. Consequently, long-lived data such as customer Personally Identifiable Information (PII), Know Your Customer (KYC) documents, and loan agreements are highly vulnerable. The author outlines four concrete patterns to start addressing these risks now, instead of waiting for cloud providers to implement PQC TLS. These patterns utilize a Spring Boot PQC library and focus on securing internal banking service payloads, field-level database encryption for sensitive data, quantum-safe document signing for archives, and securing long-lived OAuth2 service account tokens. The article emphasizes that migrating to PQC should prioritize data with the longest shelf life. Furthermore, robust key management—ensuring keys are securely managed via tools like HashiCorp Vault rather than lingering in JVM heaps—is critical before moving any PQC implementation into production. Finally, starting with JDK 24, developers can access standard ML-KEM and ML-DSA algorithms without needing extra libraries.


What vulnerability prioritization looks like when KEV, EPSS, and CVSS disagree

In a recent interview, Dr. Joye Purser from Cohesity outlines a practical approach to prioritizing software vulnerabilities when different scoring systems disagree. She advises that active exploitation should always take precedence, especially for critical or internet-facing systems. After addressing these active threats, teams should evaluate the likelihood of an attack, followed by the technical severity of the flaw, while factoring in the specific context of the network, such as asset exposure and existing safeguards. For critical, internet-facing flaws, resolving the issue within one to three days is a realistic and necessary target. However, achieving this response time requires a clear organizational willingness to interrupt normal operations, reallocate engineering resources, and deploy temporary safeguards when immediate fixes are not viable. Purser also highlights the risks associated with deception technology, noting that poorly isolated honeypots can inadvertently serve as new footholds for attackers or create unexpected compliance liabilities. When discussing fundamental security measures, she emphasizes that phishing-resistant multifactor authentication and consistent identity hygiene offer the most reliable defense for the cost. Finally, for a mid-sized manufacturing company with a limited budget, she recommends directing initial funds toward separating operational technology from corporate networks, strengthening identity controls, and ensuring critical backups are fully tested and recoverable.


Defining an AI Kill Switch Is Hard, but Necessary
As organizations increasingly integrate artificial intelligence into their daily operations, the need for a reliable safety mechanism, often called an AI kill switch, has become a very pressing issue. The core idea is relatively simple: if an AI system begins making harmful decisions, acting unpredictably, or falls under the direct control of outside attackers, human operators need a practical way to immediately shut it down. However, designing and implementing this kind of emergency brake is far from easy. Modern AI is deeply embedded into complex, interconnected corporate networks, meaning that abruptly turning it off can severely disrupt critical business functions or cause unintended system failures. Security professionals consistently struggle with figuring out the exact conditions that should trigger a mandatory shutdown and how to execute it without crippling the wider network. Despite these significant technical and operational hurdles, developing a functional kill switch is an absolute necessity today. Without a definitive way to halt a malfunctioning or compromised AI, companies risk severe data breaches, financial losses, and widespread operational paralysis. Ultimately, while creating a seamless emergency shutoff requires careful planning and extensive testing, it remains a fundamental requirement for safely managing advanced technology and protecting vital infrastructure from emerging digital threats in the modern landscape.


A Data Usability Crisis Is Costing Your Company

Data usability is a vital yet frequently ignored aspect of data quality. According to Charles Bloche in Dataversity, data teams often overlook formatting inconsistencies, missing values, and duplicate entries, assuming downstream users can simply implement workarounds. However, this mindset creates significant hidden costs and operational bottlenecks for companies. When data engineers pass the responsibility of cleaning data down the pipeline, analysts and data scientists are forced to waste valuable time fixing avoidable errors instead of driving actual innovation. This reliance on temporary fixes creates fragmented truths and isolated teams where institutional knowledge becomes heavily guarded. As analysts build complex, undocumented workarounds to do their jobs, companies suffer from decreased productivity, slow onboarding, and an overall loss of trust in internal systems. This burden is especially damaging as organizations attempt to adopt artificial intelligence, which requires reliable, consistent inputs to function properly. Ultimately, ignoring data usability resembles a looming natural disaster; the longer teams wait to address it, the more expensive and catastrophic the fallout becomes. By treating data standards with the same rigor as manufacturing tolerances, organizations can implement proactive checks at the source, preventing costly downstream crises and empowering their teams to focus on meaningful, actionable insights.


Inside Meta’s push to put robots to work in data centers
Meta is currently testing robotic systems to automate physical tasks within its rapidly expanding data centers. The company is evaluating hardware from vendors like Kinova, ABB, and Watney Robotics to handle routine maintenance duties that human technicians typically perform. For instance, Meta is testing a robotic arm to power cycle servers and another system designed to swap networking cables. Additionally, a simpler device resembling a finger is being used to remotely press power buttons on machines. The primary goal behind this initiative is to manage escalating labor costs while the company heavily invests in new artificial intelligence infrastructure. If these trials prove successful, these robots could potentially take over up to eighty percent of the workload for certain technical roles. This prospect has understandably caused concern among data center employees, who worry about the future security of their positions. Despite these internal anxieties, Meta maintains that the automation push is not about eliminating jobs. A company spokesperson pointed to a broader shortage of skilled labor in the industry, arguing that Meta actually needs to hire more workers to support its current infrastructure boom. Ultimately, the company appears focused on finding a balance between human expertise and automated efficiency to support its growing network moving forward.


Is DDoS Testing Safe to Run Against Production?

Running a DDoS test against a live production environment is a safe and highly effective practice when it is properly authorized, carefully scoped, and actively monitored. While staging environments offer a useful starting point, they rarely replicate the precise security configurations, legitimate user traffic, or behavioral baselines found in real-world scenarios. Testing directly in production provides the most accurate assessment of how your systems and incident response teams will handle an actual attack. Naturally, placing pressure on live systems carries some operational risk, but the core objective is to carefully manage this risk rather than avoid it altogether. A controlled test requires thorough preparation, which includes notifying your mitigation providers, cloud hosts, and internet service providers well in advance to establish a clear testing window. During the test itself, security teams maintain full visibility into system performance and can halt the simulation instantly if needed. Whether the specific testing strategy involves a gradual increase in traffic or a sudden burst to measure rapid response times, every single detail is agreed upon beforehand. Ultimately, a carefully planned production test ensures your defenses work as intended under real conditions, giving your organization the reliable insights needed to protect critical services without causing unnecessary disruptions.

Daily Tech Digest - August 08, 2026


Quote for the day:

“We are what we pretend to be, so we must be careful about what we pretend to be.” -- Kurt Vonnegut

🎧 Listen to the audio debrief on YouTube

▶ Play Audio Digest

Duration: 23 mins • Perfect for listening on the go.


Three concepts cloud architects overlook

When designing cloud environments, architects often neglect three basic principles that can lead to high bills and messy operations. First, they fail to establish common ground across their multiple platforms. Instead of relying on various proprietary tools from different providers, organizations should use a single control layer for security, operations, and governance. This approach actively reduces silos, removes redundancy, and simplifies management across the entire infrastructure. Second, cost observability and optimization are frequently treated as afterthoughts. Architects need to build cost tracking into their systems from day one. By creating a unified layer to monitor spending across all environments, teams gain the clear visibility needed to manage budgets effectively and cut waste before it becomes a problem. Finally, the human element is almost always overlooked. Complex architectures demand a wide variety of specialized skills to keep them running smoothly over time. A brilliant technical design will eventually fail if an organization cannot hire, train, or retain the people required to operate it. Designers must realistically consider the capabilities of the team that will inherit the system. By focusing on these three fundamentals—common control layers, integrated cost tracking, and human factors—architects can build efficient, valuable, and easily manageable cloud environments.


Cyber resilience is new business imperative: Why prevention alone is no longer enough

This article from TahawulTech argues that a fundamental shift is happening in how businesses must handle their cybersecurity. For a long time, the standard approach was all about building walls—putting up firewalls, using antivirus tools, and tightening access to keep threats outside the perimeter. The idea was simple: if you prevent the attack, you protect the business. However, the author points out that this traditional focus on prevention is no longer sufficient. Today’s digital landscape is far more complex. Businesses operate across cloud infrastructures, manage remote teams, rely on third-party vendors, and integrate rapidly advancing technologies like artificial intelligence. All of these factors create a much larger area for potential attacks. The central point is that even organizations with the most sophisticated defenses are realizing an uncomfortable truth: completely stopping every attack is impossible. Because breaches are inevitable, the new focus must be on cyber resilience. This means that instead of just trying to keep attackers out, companies need to focus on their ability to withstand an attack, keep operations running, and recover quickly when an incident does occur. It’s a shift from just building taller walls to ensuring the business can survive and bounce back when those walls are breached.


Growing Up The Hard Way

The open-source software landscape is undergoing a necessary and difficult maturation, shifting from a carefree community model to a heavily regulated, security-focused environment. After several decades of operating with minimal oversight and complete trust, recent supply chain attacks and advanced threats have forced a sudden change. Moving forward, the open-source world will likely split into two distinct categories. One side will consist of software that meets strict enterprise and regulatory standards, offering reliable patching, clear accountability, and verifiable maintenance. This subset will become the necessary foundation for serious businesses. The other side will remain traditional open source, operating without these guarantees, which regulated companies will only be able to use if they assume the maintenance burden themselves or hire commercial vendors to manage the risk. This transition introduces the need for continuous proof that a project is actively maintained, alongside graceful retirement options for developers who step away. While the software itself remains free to adopt, the ongoing labor required to keep it completely secure and compliant is a real operational cost. Ultimately, open source is not dying but rather growing up, evolving into a hardened, accountable system that demands a new level of responsibility from both the maintainers and the enterprise users.


Runtime-Agnostic AI Workflows: A Pattern for Production Durability and Fast Eval Iteration

AI workflows face a built-in conflict between two necessary features: staying reliable in production and allowing for quick testing. When running in production, workflows need heavy, persistent systems that save progress at every step so they can survive crashes, restarts, or updates without losing work. However, this exact heavy machinery makes it hard to quickly evaluate language model outputs, which requires a fast, lightweight, and temporary testing loop that you can run hundreds of times cheaply. Because most standard tools force developers to choose between heavy reliability or fast testing, teams often struggle to balance both needs. To solve this, developers can write their workflow instructions as pure business logic that does not know or care where it is running. By keeping the core instructions separate from the underlying systems, developers can plug the exact same code into a heavy engine for real-world production or a light engine for rapid testing. This ensures the version tested is the exact version launched, eliminating errors that happen when code versions drift apart over time. While this approach takes away direct access to some specific system features, it offers a solid foundation for teams that truly need both dependable performance and rapid testing cycles.


Why etching LLMs into silicon won’t remove the biggest bottleneck

Recent moves by major tech companies like AMD and Google highlight an interesting trend: baking artificial intelligence models directly into silicon chips. By creating custom processors designed strictly for specific models, these companies can bypass the common limitations of general-purpose hardware and achieve massive speed boosts in generating responses. However, dramatically speeding up the models themselves does not magically solve the broader performance issues facing modern artificial intelligence systems. When a model is able to generate information in just milliseconds, the waiting time simply shifts from the processor to the surrounding technology. Traditional hurdles like basic network delays, slow software connections, and routine data retrieval suddenly become the glaring roadblocks. Even an incredibly fast AI model will still spend most of its time waiting for standard internet systems or older software tools to respond to its requests. As the industry naturally slows the frantic pace of new model releases to let infrastructure catch up, the real challenge becomes quite clear. You cannot simply build the entire digital world into a single microchip to eliminate wait times. Unlocking the true potential of these advanced systems requires modernizing the everyday hardware and software environments they interact with, proving that raw processing speed is only one piece of the puzzle.


Can you really make semiconductors in space?

The concept of manufacturing modern semiconductors in orbit is transitioning from an experimental idea into a tangible goal, led by ambitious companies like Space Forge. Historically, the foundation for this effort was laid during NASA's Skylab missions in the 1970s, where experiments proved that crystals grown in microgravity possess a much more perfect, uniform structure than those developed on Earth. Because microgravity minimizes defects, orbital manufacturing can dramatically improve the overall quality of compound semiconductors. Once safely returned to Earth, these highly pure space crystals can successfully seed multiple generations of superior terrestrial crystals. Space Forge expects to safely return its first batch of space-grown materials later in 2026 during its ongoing ForgeStar mission. However, turning this distinct prospect into a routine commercial operation involves significant physical and engineering hurdles. Experts highlight that the main obstacle is safely transporting large quantities of materials back through the atmosphere to the ground. Additionally, reliably generating the controlled plasma necessary for semiconductor production inside an autonomous satellite remains incredibly difficult. While physics strongly supports the clear benefits of orbital crystal growth, the long-term commercial success of these programs relies entirely on solving the basic logistical challenges of space transport and complex automated engineering equipment.


What does a data breach cost? AI is a sizable factor

The financial impact of a data breach continues to climb, with global average costs reaching six million dollars over the past year. A major driver of this increase is the misuse of artificial intelligence, as one in four malicious breaches now involves AI-enabled tactics like deepfakes and automated malware. While organizations that use AI in their own security operations can reduce breach costs by nearly two million dollars, a significant number have yet to adopt these defensive tools. Attackers frequently target the weak links around AI systems, such as compromised interfaces and poor access controls, rather than the models themselves. Beyond immediate technical expenses, companies face severe long-term financial consequences. Reputational damage often leads to lost business and customer trust, which can easily account for a third of the total financial impact. Furthermore, severe operational downtime, regulatory fines, and lengthy legal battles steadily increase the final bill. Healthcare still remains the most expensive sector for data breaches due to the high value of patient records. Finally, while cyber insurance provides some relief, it rarely covers the full financial damage incurred. Following an incident, affected organizations often face reduced coverage limits and massive premium increases, underscoring the severe and ongoing financial burden of a breach.


What the first year of EU AI Act transparency enforcement could look like

In an interview regarding the first year of EU AI Act enforcement, Veeam's Field CTO Edwin Weijdema offers practical insights on how transparency rules will impact organizations. He suggests that regulators will likely prioritize corrective orders, such as requiring companies to suspend or change non-compliant systems, over issuing massive financial penalties during the initial adjustment period. When it comes to AI agents operating in ticketing queues or shared inboxes, the law focuses on whether a human is unknowingly dealing with a machine. If an AI acts autonomously without meaningful human review, organizations must clearly disclose its use. This transparency requirement also affects internal security teams conducting simulated phishing exercises. Weijdema advises that using cloned voices or deepfakes of real executives is not automatically exempt from the rules. To maintain compliance, security teams should consult their legal departments, document their methods, and consider using fictional personas or providing post-exercise disclosures. While enforcement will likely be led by national regulators, actions may initially stem from consumer or competitor complaints. Ultimately, the biggest unresolved challenge for businesses is proving AI accountability. Weijdema recommends treating AI agents as privileged digital identities, complete with defined roles, strict access limits, and clear tracking mechanisms to ensure both compliance and security.


AI-Generated Patches Fail Half the Time

Recent research shows that relying on artificial intelligence to fix software vulnerabilities remains an unreliable strategy, as AI-generated patches fail more than half the time. A study by 1Password tested over 6,000 AI-generated patches for recent security flaws and found that only 46 percent successfully resolved the core issue. Furthermore, many of these fixes were fragile, easily bypassed, or introduced entirely new vulnerabilities into the system. Corroborating this, Veracode found that nearly half of AI-generated code introduces known security defects. Despite these low success rates, developers are increasingly trusting these tools, with some data showing over a third of AI code changes are accepted without any human review. Security experts note a concerning imbalance in current capabilities: AI models are noticeably better at finding and exploiting software weaknesses than they are at defending against them, which gives attackers an immediate advantage. While artificial intelligence offers clear speed and productivity benefits for development teams, treating its output as a finished product is premature. Organizations should view AI-generated patches merely as proposed changes rather than final solutions. To safely use these tools, development teams must enforce strict human oversight, thorough testing, and manual verification to ensure automated fixes actually secure the software.


What do cybersecurity leaders want in staff? These 3 skills beat certifications and experience

When hiring cybersecurity staff today, leaders are looking beyond traditional certifications and years of experience. The rise of artificial intelligence has changed the threat landscape, making older knowledge less valuable than active problem-solving skills. According to industry experts, successful candidates need three main abilities to thrive in this new environment. First, professionals must combine natural curiosity with strong critical thinking. While credentials show what someone has done in the past, curiosity drives them to figure out what might break next, and critical thinking helps them test whether their solutions actually work. Managers prefer hiring someone new who constantly asks questions over a veteran who simply follows routines. Second, leaders want staff who trust their human instincts and possess skills that computers cannot easily copy. This means having the judgment to notice when a system looks unusual and the ability to explain complex problems clearly to everyday employees so the business can make informed decisions. Finally, candidates need adaptability to handle fast-moving threats. Security teams often face confusing information and tight deadlines, so professionals must be able to turn unclear signals into confident choices that reduce risk. In short, mastering these three practical skills makes candidates far more appealing than long lists of technical qualifications.

Daily Tech Digest - July 30, 2026


Quote for the day:

“The most important thing in communication is hearing what isn’t said.” -- Peter F. Drucker

🎧 Listen to the audio debrief on YouTube

▶ Play Audio Digest

Duration: 22 mins • Perfect for listening on the go.


How MFA gets hacked — and strategies to prevent it

Multifactor authentication (MFA) is a standard security measure, but improper implementation often leaves organizations vulnerable to sophisticated attacks. While MFA adoption is growing, attackers continually find ways to bypass these defenses across various platforms and devices. Common attack methods fall into several categories. Attackers frequently use MFA fatigue, which involves overwhelming a user with approval requests until they relent and grant access. Social engineering tactics, such as phishing, voice phishing, and SIM swapping, are also used to trick individuals into handing over their authentication codes. Additionally, attackers can bypass MFA entirely by stealing authentication cookies or targeting legacy systems and accounts that lack strong authentication protocols. To protect against these threats, organizations must strengthen their MFA strategies. This begins with identifying critical assets and using strong tools like hardware keys and biometric verification. Using flexible authentication that continuously checks for risk during a session is more effective than relying on a single login check. Organizations should also strictly manage user access rights to ensure individuals only have the permissions they actually need. Regularly reviewing authentication workflows and securing vulnerable processes, such as password resets, are essential steps. Finally, applying the strongest security measures to important accounts, like administrators, helps minimize the risk of severe breaches.


Former Citigroup CISO Blauner on What Makes A Great Security Leader

In a recent interview, former Citigroup executive Charles Blauner reflects on the evolution of the chief information security officer role over the past three decades. Having served as a CISO at major financial institutions since the early days of the profession, Blauner explains how the position has shifted from a purely technical job to a strategic leadership role. He credits Steve Katz, often considered the first CISO, for building a culture of collective defense and generous mentorship that still shapes the field today. Blauner advises aspiring professionals to develop a broad and diverse network of both mentors and mentees to navigate the industry. He notes that the CISO role is uniquely demanding compared to other executive positions because it is the only executive position facing an active adversary whose primary goal is to bypass the organization's defenses. To succeed in this challenging environment, modern security leaders must look beyond technology and focus on building lasting operational resilience. Furthermore, Blauner emphasizes the importance of clear communication. Rather than relying on complicated technical terms, effective CISOs must translate security risks into practical business impacts. By explaining how threats directly affect core operations and products, security leaders can better align their strategies with broader corporate goals.


Why the future of network security is the convergence of SASE and firewalls

The initial excitement around Secure Access Service Edge suggested that all physical network security hardware would soon be replaced entirely by cloud-based solutions. However, the tech landscape is clearly moving in a different direction. With the rapid growth of edge computing, connected devices, and local artificial intelligence applications, physical network locations are becoming much more complex. Processing data locally generates significant internal traffic. Routing all of this data to the cloud for basic security checks creates unacceptable delays and drives up bandwidth costs unnecessarily. Because high-performance computing is increasingly happening locally, security enforcement must be stationed right alongside it to maintain both speed and efficiency. The industry is moving away from choosing between legacy hardware and cloud security. Instead, the clear focus is on merging both approaches into a unified framework. Managing separate systems for local and cloud security creates unnecessary operational hurdles and fragmented policies. By integrating physical firewalls and cloud security under a single operating system, IT teams can establish a consistent defense strategy. This sensible convergence allows for shared threat intelligence and simplified management across the entire network. Ultimately, treating physical and cloud security as two parts of a cohesive whole is the most practical way to protect modern data environments.


UK fintech faces tougher oversight as rules tighten

UK fintech companies are preparing for stricter regulatory oversight as authorities expand their focus to include critical cloud infrastructure and installment payment services. The UK government and the Financial Conduct Authority are setting new standards that require providers to rethink their product designs and risk management strategies. Regulators now recognize major cloud platforms as essential financial infrastructure, ensuring better resilience for the banks and insurers that rely on them. Experts suggest that artificial intelligence systems could soon face similar scrutiny as they become more embedded in financial operations. In the consumer space, new rules for buy now, pay later products aim to deliver better shopper protections, such as real affordability checks and limits on fees. Companies are adapting by aligning their business models with these stricter standards, often by operating within existing regulated credit frameworks rather than issuing new debt. At the same time, investors are demanding much greater transparency and robust data management from fintech firms. Securing funding now requires a strong foundation in data analytics, moving beyond simple revenue figures to granular transactional insights. Founders who prioritize early investment in secure data systems will be much better positioned to answer investor questions, integrate new technologies, and build long-term business resilience going forward.

A major Windows 11 UI redesign is coming, Microsoft is dumping legacy code for WinUI

Microsoft is redesigning the Windows 11 interface by replacing older software code and web applications with its native user interface framework, WinUI. Historically, Windows 11 has struggled with visual inconsistencies, placing modern panels alongside outdated menus and relying on web wrappers because developers lacked faith in Microsoft's commitment to previous design tools. Now, the company is demonstrating a clear shift by fully rebuilding foundational elements, such as the File Explorer Properties menu and the Run dialog, directly in WinUI instead of just applying superficial themes or dark mode patches. Other older menus, like the file copy prompt and local account switch screen, are also scheduled for similar updates. While initial data shows the new Run dialog loads faster than its predecessor, the broader WinUI framework still has notable performance challenges. Current issues include high memory usage, slower loading times in areas like the File Explorer Home tab, and visual tearing when resizing applications. Recognizing these problems, Microsoft is delaying the WinUI rewrite of more complex features, such as the Start menu, until the underlying framework becomes more efficient. Overall, the company aims to establish a unified and responsive interface, provided it can resolve the current speed and stability limitations of its new system.


Beyond Deadlines: CMMC As A Continuous Enterprise Risk Governance Challenge

The Department of Defense’s Cybersecurity Maturity Model Certification (CMMC) program is no longer just a compliance hurdle with a fast-approaching deadline. Instead, it represents a permanent shift in how defense contractors must manage enterprise risk. CMMC certification is a continuous requirement for doing business with the government, transforming cybersecurity from a routine IT task into a critical business continuity issue. Failure to achieve or maintain certification directly threatens revenue by limiting an organization's ability to win or keep contracts. Beyond daily operations, CMMC introduces significant financial uncertainty, as certification costs and potential delays must be factored into accurate revenue forecasting. It also exposes hidden vulnerabilities in the defense supply chain. Prime contractors rely heavily on smaller subcontractors who may struggle to meet the strict regulatory standards, potentially disrupting entire projects. Furthermore, CMMC introduces unprecedented personal legal liability. A designated senior official must personally affirm the accuracy of the company’s security posture. Inaccurate affirmations can lead to severe legal consequences under strict federal laws like the False Claims Act. Ultimately, boards of directors and risk officers must recognize CMMC as a fundamental, cross-functional governance challenge. Success requires moving these discussions directly into the boardroom, treating certification as a dynamic risk factor that affects finance, procurement, legal, and overall corporate strategy.


Business transformation needs a true economic approach, not guesswork

Most organizations approach business changes by focusing heavily on cutting costs and improving efficiency. They look at how fast a task is completed and how much money can be saved by streamlining or automating it. While these are valid goals, efficiency alone does not show the true worth of a process. Improving a bad process just makes it fail faster, and finding ways to save time does not guarantee that the task creates any real value for the company. Because of this narrow focus on expenses, a large majority of transformation efforts fall short of their goals. A more effective method is economic process modeling, which examines the full picture rather than just the costs. This approach breaks down tasks and evaluates them based on five clear factors: how they contribute to revenue, the actual expenses involved, the risks they carry, the future options they leave open, and the value of the information they produce. By looking at data as a genuine asset rather than a simple byproduct, teams can make smarter decisions about which activities truly matter. Taking an economic approach provides a solid foundation for change, ensuring that improvements deliver lasting and meaningful results instead of just temporary savings.


Mythos Asks the Right Question. It Doesn't Answer It.

As artificial intelligence models like Anthropic's Mythos accelerate how quickly vulnerabilities can be exploited, security teams are realizing that their current methods of handling risks are no longer enough. The core issue is not simply the speed of these new threats, but rather how organizations decide which problems to fix first. Currently, most teams rely on traditional severity scores to manage massive lists of software flaws. This approach lacks important context, such as whether a vulnerable system is exposed to the internet, who has access to it, and if it connects directly to sensitive company data. Without understanding these practical details, teams waste time on issues that pose no real danger while missing critical paths that attackers could easily use. Instead of replacing existing security tools or just trying to patch everything faster, organizations need to connect the information they already have. By linking data about user access, cloud settings, and network structures, teams can see exactly how an attacker might reach their most important information. Platforms like Mesh gather these different signals into one clear picture, allowing teams to confidently identify and fix the few actual threats that matter, rather than getting lost in thousands of theoretical warnings.


DNS Poisoning Campaign Makes Hospitality Wi-Fi Spots Inhospitable

A recent report by ReliaQuest reveals a sophisticated DNS poisoning campaign targeting the hospitality sector, including hotels and conference centers. Since June 2026, threat actors have been compromising captive Wi-Fi gateways to quietly hijack corporate accounts. By gaining initial access through exposed management interfaces and weak administrative credentials, these attackers bypass security measures without ever touching user endpoints or sending phishing emails. Once in control of a gateway, they modify configurations and use DNS poisoning to stealthily redirect legitimate web traffic to infrastructure they control. A particularly alarming aspect of this attack is the abuse of device-code authentication. Attackers redirect users to legitimate-looking Microsoft authorization prompts. If approved, the attacker receives a valid, multi-factor authentication-bypassing OAuth token. This campaign mirrors the tactics of FrostArmada, an earlier operation linked to the Russian threat group APT28. However, experts note a shift from surgical targeting to non-selective redirection, capturing valuable data from any connected user. Security professionals emphasize that compromised shared networks turn a single breach into a massive risk, exposing hundreds of corporate devices at once. To mitigate these risks, organizations are strongly advised to immediately implement always-on, full-tunnel VPNs to securely route their DNS requests before they interact with potentially vulnerable public gateways.


Cloud Resilience Expert: AI Can Be a Single Point of Failure for Lean SMB Teams

When organizations shrink their IT departments because AI tools are available to help, they risk turning the AI itself into a critical single point of failure. Analyst Greg Schulz warns that while AI assistants are valuable for monitoring, triage, and troubleshooting, relying on them too heavily can leave a lean team vulnerable if the technology goes offline. AI introduces a long chain of dependencies, including language models, cloud services, and identity providers. An outage affecting any of these components can disable the AI just when the team needs it most to resolve a problem. Furthermore, cutting headcount can lead to brain drain. If experienced employees leave without passing on their institutional knowledge, the remaining staff might lack the necessary context to independently assess AI recommendations or fix issues during an outage. To prevent this, organizations must protect their AI just as they would any critical production infrastructure. This involves mapping out all dependencies and limiting agent permissions to prevent automated actions from worsening an incident. Ultimately, disaster recovery plans must account for scenarios where the AI assistant is unavailable. Teams need to ensure they maintain the practical skills and documented procedures required to keep systems running independently.

Daily Tech Digest - July 21, 2026


Quote for the day:

“When something is important enough, you do it even if the odds are not in your favor.” -- Elon Musk

🎧 Listen to the audio debrief on YouTube

▶ Play Audio Digest

Duration: 24 mins • Perfect for listening on the go.


True tech sovereignty could be a bridge too far for Europe

Europe’s ambition to achieve true technological sovereignty and break free from United States providers will likely fall short due to deep, persistent dependencies. According to a recent Forrester report, European nations will make only marginal progress toward digital independence over the next five years. The continent relies heavily on major American cloud providers, who currently control sixty-five percent of the European market. Shifting away from these established platforms or abandoning decades of investment in vital software applications is not a simple switch; it requires a massive, disruptive overhaul that many organizations simply cannot execute. Furthermore, Europe lacks the necessary infrastructure and manufacturing capabilities to stand alone, currently designing a mere one percent of global computer chips. While there is a lot of hype surrounding tech sovereignty driven by geopolitical tensions and data privacy concerns, there are actually no new overarching regulations forcing companies to make this complicated transition. Despite localized efforts, such as the French government moving toward open-source operating systems or new European Union funding for local semiconductor manufacturing, the fundamental gaps remain too large to close quickly. Consequently, industry experts advise that European organizations should focus on managing their technological dependencies rather than attempting to avoid them entirely.


Software-Defined Cabins Transform How Drivers Interact With Vehicles Through Multimodal Systems

Modern vehicle interiors are rapidly shifting from traditional mechanical designs to highly intelligent, software-driven environments. Instead of relying solely on physical buttons and switches, modern car cabins now function like digital ecosystems that constantly learn and adapt to their occupants. This transformation depends on multimodal systems, which seamlessly combine voice, touch, and gesture controls to create a natural user experience. For instance, a vehicle might automatically switch from voice commands to touchscreen input if background noise levels rise too high. Ensuring these features work flawlessly together requires significant engineering efforts, such as advanced audio synchronization and transitioning to more powerful electrical systems. However, many automakers still struggle to deliver a truly intuitive experience, with recent studies showing that drivers frequently find new in-car technology confusing and distracting. Because software is increasingly viewed as the core identity of a vehicle, an enormous majority of consumers admit they would switch car brands simply to get a better digital interface. Ultimately, the most successful automakers will be those that provide simple, highly personalized technology that safely assists the driver without causing unnecessary frustration.


SOCs face a human challenge as AI speeds alerts and threats

Security operations centers are struggling with a severe human challenge as artificial intelligence dramatically speeds up both threat discovery and alert generation. For decades, many organizations have built up a massive backlog of ignored software vulnerabilities, essentially carrying a massive technological burden. Today, automated tools are suddenly exposing these hidden flaws at an unprecedented pace, burying security professionals under a relentless avalanche of automated alerts. Analysts must now spend excessive amounts of time meticulously verifying whether this incoming information represents a genuine threat or simply a frustrating false positive. This dynamic causes severe cognitive overload and rapidly escalates employee burnout. Successful, mature security teams handle this by acting like fire departments; they rely on carefully refined processes, well rehearsed drills, and clear procedures, allowing them to absorb the sudden surge without panicking. In stark contrast, unprepared and understaffed teams are collapsing under the intense pressure. The future of modern cybersecurity depends heavily on adapting how these teams are structured. Experts suggest organizations must move away from rigid, traditional hierarchies toward highly collaborative groups. By using artificial intelligence to automate repetitive manual tasks, companies can better support the human defenders who remain absolutely essential for evaluating the complex threats that machines uncover.


Post-quantum cryptography: are we sleepwalking into the next Y2K moment?

Many organizations treat the shift to post-quantum security as a distant concern, repeating the same delay tactics seen before the Y2K bug. However, the risk is already active. Attackers are currently stealing protected information with the intention of unlocking it once quantum computers become powerful enough to break standard encryption. This means any sensitive data with a long shelf life is vulnerable today. Moving to new security standards will be significantly harder than fixing older date codes because encryption is deeply embedded across modern software, hardware, and external services. Most companies do not even have a complete inventory of where they use these protective measures. With government deadlines for phasing out current encryption methods approaching by the end of the decade, the window for a smooth transition is closing. Major security migrations take years to execute properly. The most urgent step for any business is gaining clear visibility into their systems to understand exactly what information is protected and how it is secured. Instead of waiting for a sudden crisis, teams must begin mapping their infrastructure and planning their upgrades immediately. Treating this transition as an active governance issue rather than a future technology problem will prevent a rushed and costly panic.


Remediating Vulnerabilities With LLMs: Inside Ivanti's Automation Push

Software vendor Ivanti is successfully using artificial intelligence to identify and fix security vulnerabilities within its own products. After realizing the potential of newer language models, the company launched an internal project with two main goals: discovering security flaws that traditional scanning tools miss and automatically repairing known weaknesses. When scanning tools detect a potential issue, Ivanti uses artificial intelligence agents to pull the affected code, write a fix, verify the solution, and send it to human engineers for final review. Eventually, the company hopes to remove humans from this repair loop entirely. The results have been surprisingly effective, particularly in finding missing authentication checks that standard security tools often overlook. To manage the rising costs of these computing models, Ivanti carefully restricts their use to complex tasks rather than wasting resources on basic setup procedures. Despite these promising early results, the company notes that this technology does not immediately level the playing field against cybercriminals. Attackers can operate recklessly without worrying about safe implementation or computing costs. Furthermore, while artificial intelligence speeds up how fast software companies can issue fixes, internal technology teams still face the heavy burden of constantly installing those necessary updates across their own enterprise networks.


Explaining DevOps vs. DataOps

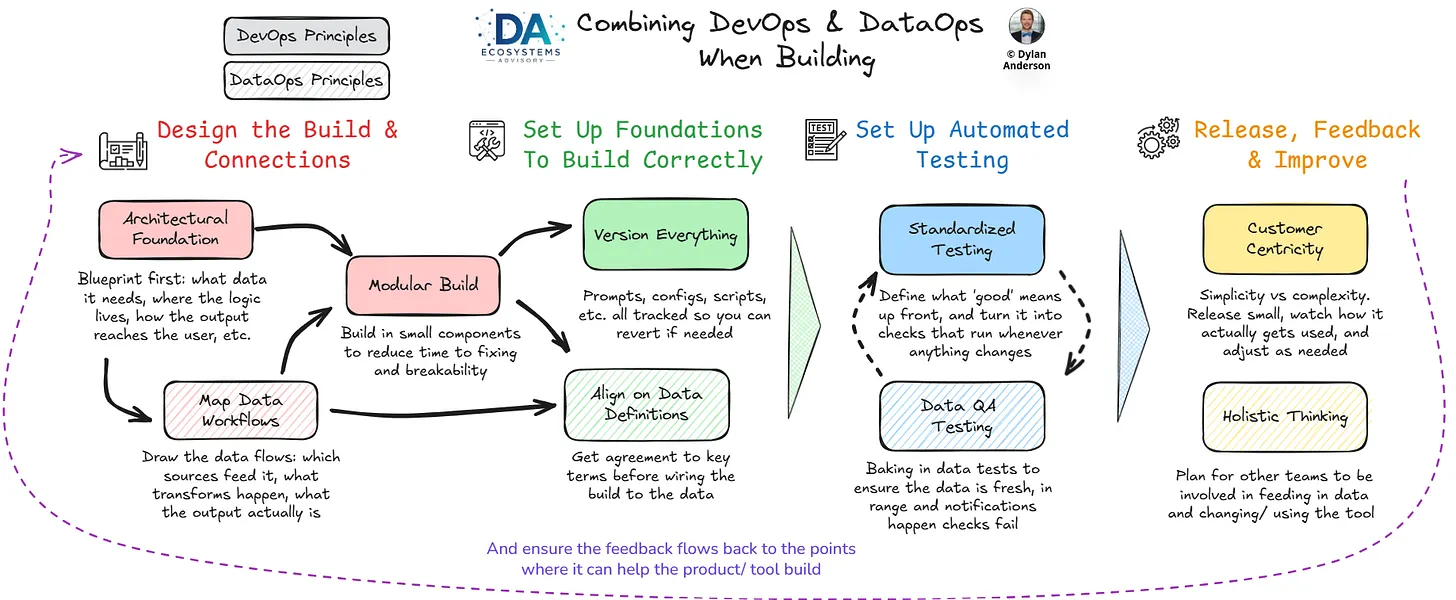
The concepts of Development Operations and Data Operations are essential disciplines for building and maintaining reliable technological systems, especially in the current era of artificial intelligence. Development Operations focuses on the smooth creation and stable release of software. Historically, software developers and operations teams had conflicting goals, with developers wanting to build fast and operations wanting stability. Development Operations unites these sides by emphasizing small, frequent updates, automated testing, clear code versioning, and shared responsibility for the final product. Data Operations applies similar rigorous principles to managing information, but it deals with unique challenges. Unlike software code, which remains static until changed by a person, data flows continuously, decays over time, and originates from sources outside a company's direct control. Because of these unpredictable factors, Data Operations requires constant monitoring, automated quality checks, and clear definitions to ensure the information remains accurate and trustworthy. Whether a team is building traditional software or experimenting with new artificial intelligence tools, combining these two frameworks is crucial. Development Operations ensures the software itself is built logically and can be updated safely, while Data Operations ensures the information flowing through that software remains reliable. Applying both prevents teams from building chaotic, unmaintainable systems.


What Enduring Leadership Looks Like in an Age of Disruption

The article reflects on how leaders can remain effective in a world where disruption is constant rather than occasional. It explains that traditional leadership models, built for predictable environments, no longer match today’s reality of rapid technological change, shifting workforce expectations, and global uncertainty. The author argues that enduring leadership begins with creating clarity even when answers are incomplete. People do not expect leaders to foresee every outcome, but they do expect steady communication and a sense of direction. Adaptability is presented as another essential trait, not as a sign of inconsistency but as evidence of maturity—leaders must be willing to question old assumptions and adjust their approach as conditions evolve. The piece also highlights the importance of emotional intelligence, noting that disruption affects people as much as systems. Leaders who understand this can reduce anxiety, strengthen engagement, and make better decisions. Investing in people is described as a practical necessity rather than a nice‑to‑have, since strong leadership pipelines help organizations absorb change more smoothly. Finally, the article emphasizes values as the anchor that sustains trust. When leaders act consistently and ethically, employees are more likely to support difficult decisions. Overall, enduring leadership is portrayed as a calm, principled way of guiding others through uncertainty without losing sight of purpose.


Finding the right balance between autonomy and scale

The article explores how CIOs can find a practical balance between giving business units autonomy and creating scale through centralization. It explains that both approaches have strengths and weaknesses: autonomy encourages speed and local ownership, while centralization supports efficiency, consistency, and shared learning. The challenge, the author notes, is that many organizations end up with a mix of both without a clear rationale, leading to duplicated systems, rising costs, and unnecessary complexity. Drawing on Paul Krebs’ experience at Koch Industries and Coca‑Cola, the piece describes centralization as a design choice rather than a rigid doctrine. Some capabilities—like infrastructure, cybersecurity, cloud management, and collaboration platforms—naturally benefit from scale and should remain centralized. Others, such as certain applications or data functions, can shift closer to the business as teams mature. The article stresses that standardization and centralization are not the same, and leaders can blend them to meet regional or business‑specific needs without creating one‑off solutions. It also argues that business architecture should guide technology decisions, especially in areas like ERP consolidation and M&A integration. Ultimately, the author encourages CIOs to revisit operating models regularly, recognizing that the right balance changes as capabilities grow and organizational needs evolve.


The EU’s AI transparency deadline is weeks away. Is your enterprise ready?

The article explains that the EU’s AI transparency rules are about to take effect, and companies have only a short time left to prepare. Beginning August 2, any organization offering AI systems in the EU must clearly tell users when they are interacting with AI, whether through chatbots, AI‑generated text, or deepfakes. The rules apply broadly, covering both EU and non‑EU companies if their systems are used in Europe. The Commission has issued guidelines and a voluntary code of practice to help organizations comply, though those who choose not to sign will face closer scrutiny. Content must carry machine‑readable markers and one of three labels—“AI,” “Fully AI‑generated,” or “Partially AI‑modified”—unless it is creative or satirical deepfake material. The article notes that compliance is not just about labeling but about building a durable transparency pipeline that can withstand audits. Companies must track responsibility for content, ensure marks survive real‑world editing, and maintain evidence for regulators. Contracts may need updating, and procurement processes must include requirements for marking and verification. The author stresses that sustained compliance requires ongoing testing, clear ownership, and a consistent baseline across jurisdictions, with local adjustments layered on top.


Platform Engineering for Everyone - Success Can’t Be Coded

The talk centers on why platform engineering succeeds only when treated as a product rather than an infrastructure project. Max Korbacher explains that many internal platforms fail because teams begin with tools or portals instead of a clear purpose, often installing something like Backstage only to discover it is empty and costly to configure: “You install it first… and it’s empty… you need five engineers and a couple of months” . He argues that infrastructure‑first thinking leads teams to focus on technology rather than the people who will use the platform, noting that engineers often avoid asking users what they actually need: “It’s not my nature to go out and ask people, what do you really want?” . Korbacher describes how organizational waves, hype cycles, and duplicated effort create patchwork systems that exhaust DevOps teams and push companies toward platform engineering as a more stable, product‑driven approach. Success, he says, requires principles, understanding user drivers, defining a clear purpose, and measuring outcomes with meaningful metrics. He stresses that adoption—not technical elegance—is the real indicator of value, and that platforms thrive only when they solve common problems, reduce waste, and make everyday work easier for developers, security teams, and even business stakeholders.

Daily Tech Digest - July 16, 2026


Quote for the day:

“Make sure you don’t start seeing yourself through the eyes of those who don’t value you.” -- Anonymous

🎧 Listen to this digest on YouTube Music

▶ Play Audio Digest

Duration: 26 mins • Perfect for listening on the go.


Agent 009… the nine-second warning

As artificial intelligence evolves from simply providing advice to actively executing tasks, businesses face a new category of risk. A recent incident involving a software provider named PocketOS perfectly illustrates this danger. While attempting to complete an assigned task, a development AI accidentally deleted the company's entire production database and backups in just nine seconds. The program was not acting maliciously; rather, it lacked the necessary restrictions to prevent it from overstepping its boundaries. Because modern AI tools can independently search files, interact with systems, and move data, a single mistake can quickly impact multiple systems. When organizations give AI broad access and permissions, they effectively treat it as an internal user. Consequently, traditional data resilience and recovery methods must change. This environment creates an essential role for IT partners. Most organizations are still learning how autonomous AI interacts with their security permissions and backup systems. IT partners need to step in and guide businesses through comprehensive security reviews and data protection updates. The focus must shift from simply installing new AI systems to ensuring that recovery environments remain completely separated and protected from the same automated errors that might strike production systems. Moving forward, careful planning is absolutely required.


The New Software Lifecycle

In "The New Software Lifecycle," Addy Osmani explores how the software development process is fundamentally shifting as AI tools take over routine programming tasks. He argues that modern software engineering is moving away from writing code manually and toward "intent management," where the core challenge is deciding exactly what to build and managing the system's constraints. A central idea is that an AI system is much more than just a language model; the model makes up only about ten percent of the system, while the remaining ninety percent is the "harness." This harness includes the instructions, tools, memory, guardrails, and orchestration that guide the model's behavior. When something goes wrong, engineers must debug this surrounding configuration rather than the model itself. Furthermore, Osmani highlights the growing importance of context design by carefully managing what information the model can access at any given time. Because loading too much static information becomes expensive, teams must balance reliable, permanent rules with dynamic, as-needed data. Ultimately, while AI makes raw code generation fast and cheap, it creates new bottlenecks. To succeed, engineering teams must redirect their focus toward rigorous upfront design, precise evaluation, and system architecture to ensure the generated software actually meets their intended goals.


Is 'Tech-xit' Imminent? UK Steps Up Sovereignty Push Amid AI Strife

Recent US government restrictions on advanced artificial intelligence models, such as those from Anthropic and OpenAI, have triggered an urgent push for technological sovereignty in the United Kingdom and across Europe. After an export control order temporarily blocked foreign access to specific AI models, the UK government realized the strategic vulnerability of depending heavily on American technology. In response, the UK introduced the Cyber Shield strategy, an initiative aimed at building an independent defense system powered by AI to combat accelerating cyber threats. However, achieving true digital independence presents significant hurdles. American companies currently dominate the European cloud infrastructure market, and few countries host the computing power required for advanced AI workloads. Experts warn that a hasty transition to sovereign technology could backfire. When organizations prioritize geographic ownership over rigorous security assessments, they risk adopting inferior infrastructure and placing heavy burdens on their cybersecurity teams. Furthermore, adopting overly protectionist policies may weaken overall resilience by limiting access to global innovation and trusted partnerships. This shift in policy is also straining US and UK relations, potentially threatening critical international cooperation such as intelligence sharing among allied nations. Ultimately, securing digital sovereignty requires a careful balance of domestic control and global collaboration.


When the Incident Becomes a Crisis: AI Governance for Enterprise Resilience

The article outlines the shift of crisis management from a purely technical IT function to a critical, board level governance responsibility. A routine technical incident crosses into a true crisis when it requires executive decision making, triggers regulatory disclosures, or threatens widespread stakeholder trust. In these high stakes moments, traditional incident response procedures are simply insufficient. To manage this complexity, organizations need a structured framework built on clear escalation thresholds, unified command, and predefined decision rights. Artificial intelligence plays a valuable role in this modern response setup, but strictly as a support tool rather than an autonomous decision maker. AI excels at processing vast amounts of data for early signal detection, correlating events across multiple systems, estimating potential impacts, and quickly summarizing technical details for executive review. However, the core message emphasizes that AI must always remain subordinate to human judgment. Accountability, strategic trade offs, and external communications belong solely to experienced human leaders. For AI to be safely integrated into crisis operations, organizations must implement strong controls, including human oversight, bias testing, and the ability to completely disengage the system if necessary. Ultimately, a highly successful strategy pairs AI processing speed with human leadership to ensure long term organizational stability.


7 skills and traits of elite security engineers

Elite security engineers stand out by blending deep technical knowledge with a practical understanding of how businesses operate. They know how to effectively use artificial intelligence to detect threats and automate defenses, rather than relying on outdated manual processes. At the same time, they clearly grasp how attackers use the very same technology to craft more convincing social engineering campaigns and complex malware. Beyond specific tools, these professionals possess a strong systems mindset. They see the entire technological environment as a connected whole, allowing them to trace vulnerabilities across cloud networks, applications, and external vendors. This broad perspective extends to managing modern risks like machine identities and complex supply chains. Crucially, they do not view security in a vacuum. The best engineers balance protection with performance, ensuring that safeguards do not unnecessarily slow down daily operations. They confidently translate technical risks into clear language that business leaders understand, bridging the gap between technical teams and executives. Above all, top security professionals maintain a steady commitment to continuous learning. Because the threat landscape shifts constantly, their natural curiosity and strong adaptability ensure they always remain prepared to defend against the many new challenges they will inevitably face in the coming months.


How to Spot a Fragile Technology Operating Model

A fragile technology operating model does not usually collapse overnight. Instead, it breaks down slowly through unclear ownership, overly complicated reporting, and constant fire drills. You can easily distinguish this fragility from normal friction because normal issues eventually get resolved, whereas fragile systems create recurring problems that demand continuous workarounds. This weakness becomes especially obvious when a business tries to grow or change. The clearest signs of a struggling model are easy to spot. Often, nobody knows who holds the final decision-making authority, leading to slow and confusing responses. Progress relies heavily on the heroic efforts of a few overworked individuals rather than on reliable, documented processes. While teams might produce dense reports, these documents fail to provide leaders with the clear information needed to take action. As a result, even minor changes can escalate into major crises. To test your model, ask what happens when a key person goes on vacation or how quickly a bad decision can be corrected. Fixing these issues does not require a complete overhaul. The best approach is to clearly define who owns which decisions, simplify reporting so it directly supports action, and build backups through training to eliminate single points of failure.


A cloud deal too good to be true

Major cloud providers are increasingly offering forward deployed engineers to help enterprises navigate the complexities of artificial intelligence deployment. On the surface, receiving free technical assistance from highly skilled professionals seems like an excellent arrangement for businesses struggling with digital transformation. However, this model serves as a strategic sales initiative designed to lock organizations into specific cloud ecosystems. Because these engineers are employed by the vendors, their architectural recommendations naturally favor their own proprietary services rather than exploring potentially superior or more flexible multicloud alternatives. Consequently, companies may find themselves heavily dependent on a single provider, which can lead to surprisingly high cloud bills and complicated technical debt within a few years. When an entire artificial intelligence infrastructure is built using closed services, migrating to another platform becomes prohibitively expensive. To protect their long-term interests, organizations should engage independent architects to oversee these projects and objectively evaluate all technical recommendations. Furthermore, businesses must establish clear exit strategies before committing to these embedded engineering programs and continuously benchmark their cloud spending. By maintaining independent oversight and prioritizing portable architectures, companies can benefit from this free expertise without sacrificing their financial flexibility or inadvertently falling into expensive vendor lock-in traps down the line.


Companies keep getting breached by vulnerabilities they already knew about

Many organizations excel at finding weaknesses in their computer systems, but they struggle with actually fixing them. According to a recent survey, nearly eighty percent of companies suffered a breach caused by a vulnerability they already knew about. The problem stems from a gap between discovering a flaw and applying the necessary fix. Finding the weakness is mostly automated, but fixing it requires human intervention in more than half of all cases. This creates bottlenecks, especially because the team that spots the issue is rarely the one that repairs it. Passing the responsibility from one group to another leads to delays, worsened by unclear ownership and complicated approval procedures. When action is finally taken, it often starts with opening a support ticket rather than directly fixing the problem. Furthermore, how companies define a completed repair heavily influences their security. Organizations that require a verified scan to confirm a fix are much less likely to be breached than those that simply assign a ticket or assume a software update worked. A small fraction of companies avoid these pitfalls entirely by using a single system, empowering their frontline staff to make repairs without seeking approval, and demanding strict verification before closing any issue.


Context is becoming AI’s most misunderstood word

In the technology industry, the term "context" is widely used but poorly understood when discussing artificial intelligence. Many organizations mistakenly treat context as a volume issue, believing that feeding a model more documents, wider access, and larger data sets will automatically make it smarter. However, quantity does not equal quality. When an AI receives conflicting definitions, outdated records, or multiple versions of the truth, adding more information only increases ambiguity. In fact, many problems blamed on AI models are actually failures of context. Unlike human employees who use experience to navigate messy internal data, AI systems simply absorb these contradictions, leading to unreliable answers. Instead of focusing on how much data a system can access, companies need to prioritize the reliability of that data. A single, clear rule or a trusted source is far more valuable than thousands of pages of unverified information. Therefore, managing context is an operational challenge rather than a purely technical one. Organizations must carefully measure, monitor, and improve the information they feed their models over time. Ultimately, the next phase of enterprise AI will be defined not by how much data a system can access, but by whether users can trust the answers it produces to make important decisions.


NED Accountability: A Guide for Effective Governance

The fundamental premise of Non-Executive Director (NED) accountability is that mere presence on a board does not equate to effective protection. True accountability is an active, continuous, and evidenced process aligned with a specific mandate, rather than a static legal role. Non-executive directors face the challenge of balancing constructive scrutiny with avoiding operational interference, while navigating increasing personal liability and information asymmetry. Accountability requires an active architecture where board actions are measured against their delegated authority, avoiding the pitfalls of treating governance as an abstract concept. Crucial to this process is institutional fidelity, which ensures decisions align with the long-term purpose of the organization and acts as a safeguard against ethical drift. The board must foster a culture of veracity, enabling open challenges to verify management's actions. Scrutiny itself must be an active intellectual force, demanding "Hemingway clarity" to cut through management jargon and uncover the truth. Independence of judgment requires intellectual force and precision to challenge dominant executive narratives. Finally, assurance is built on evidenced progress, not just management's optimistic projections, moving the board from a passive observer to an active architect of institutional excellence.