Showing posts with label crypto agility. Show all posts

Daily Tech Digest - October 05, 2026


Quote for the day:

“The more you loose yourself in something bigger than yourself, the more energy you will have.” -- Norman Vincent Peale


Data Has No Passport: Why Global Privacy Governance Must Catch Up With AI

At the CruiseCon Privacy and AI 2026 event, Accenture privacy lead Adriana Antunes Winkler highlighted a growing challenge: while data moves globally and instantly, privacy regulations remain fragmented and bound by local jurisdictions. With around eighty percent of the world covered by varying data protection frameworks, companies often struggle to keep up. Winkler advised against building separate privacy programs for every new law, as this causes confusion and conflict. Instead, she recommended a strategy built on a common global foundation with specific local adjustments only where legally necessary. This prevents the burden of simply applying the strictest rules everywhere. Winkler emphasized that operational controls, not just written policies, are what actually protect privacy. These controls require clear ownership, testing, and proof of function. The rise of artificial intelligence complicates this further, as AI often infers new personal details rather than just storing collected information. She suggested focusing on the specific actions AI takes and the systems it accesses, treating it as a data map driven by actions. Ultimately, whether data crosses international borders, runs through AI systems, or eventually processes in orbital satellites, organizations must rely on a unified, adaptable governance system that manages common standards while addressing specific local requirements.


Crypto-Agility Distrust Readiness

When major internet authorities decide to stop trusting a flawed digital certificate, the resulting fallout can cripple the countless services relying on it. While technical bodies like browser developers excel at making the call to pull a failing root certificate, there is currently no coordinated national plan for what happens to the broader economy the morning after. Historically, isolated incidents have been contained, but the dual threats of rapidly advancing artificial intelligence and a forced timeline for quantum-safe encryption mean that widespread disruptions are becoming more likely. The blast radius of a sudden distrust event can vary wildly across different sectors, and responding effectively requires advance preparation rather than improvisation. To survive this accelerating risk, organizations must create reliable certificate inventories, designate clear response liaisons, and run tabletop exercises to test their readiness. On a larger scale, a designated national coordinator is urgently needed to connect technical decision-makers with the sectors facing the consequences. Ultimately, building true resilience requires organizations to eliminate single points of trust by adopting multiple issuing authorities and automating certificate lifecycles, ensuring they can pivot smoothly when a crisis hits instead of scrambling to rebuild.


Measuring AI With the Wrong Ruler

When evaluating artificial intelligence systems, getting caught up in grand labels distracts from what truly matters: reliability, cost, and fitness for the job. The technology industry often assumes that larger, more capable models are inherently better, but deploying a massive system for a straightforward task is wasteful and risky. It is very similar to dropping a race car engine into a riding lawnmower. Raw power without proper control or necessity only creates hazards. Instead of obsessing over raw machine intelligence, which mirrors our flawed fixation on human IQ scores, we should focus on building operational wisdom. This means designing tools that clearly understand context, respect their own boundaries, and know exactly when to seek human intervention. Historical missteps in automotive software, where complex features completely overwhelmed inadequate hardware, prove that mismatched computing power leads to frustrating failures for end users. To make better decisions, organizations need a practical measurement framework that strictly aligns system complexity with the actual criticality of the task. By focusing on calibrated computing, businesses can ensure they deploy software with verifiable competence. This thoughtful approach prioritizes restraint, safety, and hardware capacity over industry hype, ultimately resulting in technology that simply works properly for its intended daily purpose.


Should cybersecurity be nationalised?

The conversation around digital safety is gradually shifting from treating it as a private expense to recognizing it as a public good. While full government ownership is not currently under consideration, experts argue that the traditional model of individual corporate defense is no longer sustainable. Today, private companies are routinely expected to fend off sophisticated attacks from foreign nations, a task for which most lack the necessary resources. Small businesses are particularly vulnerable and they often become the weak link that exposes broader networks to risk. Because hardening the defenses of one company inherently protects the wider community, securing digital infrastructure shares clear parallels with public utilities like street lighting. This shared benefit naturally raises important questions regarding funding and accountability. The emerging consensus suggests a model where the state might fund security measures that are executed by private firms, ensuring broader protection without complete nationalization. As this policy debate unfolds, organizations must adapt by viewing their security practices not merely as an internal budget item, but as a core component of public trust and reputation. Moving forward, businesses should firmly anticipate stricter sector requirements and expect to demonstrate baseline security standards simply to operate within shared modern networks.


IT modernization: Still a make-or-break project for CIOs

IT modernization remains a vital, ongoing mission for CIOs, taking on renewed urgency as artificial intelligence reshapes the technology landscape. The rise of AI and natural language tools means that systems built just a few years ago, such as traditional reporting dashboards and specialized chatbot software, may already be obsolete. IT leaders are now approaching modernization and application rationalization with a business-first strategy, evaluating tools not by their age, but by the tangible value and flexibility they provide. Consolidating software limits wasteful spending, reduces unneeded complexity, and creates a clean data environment essential for advanced technologies. While moving to modern solutions can cut maintenance costs and limit security risks, CIOs face practical challenges, including upfront migration expenses, data extraction difficulties, and internal resistance to letting go of highly customized legacy systems. Some organizations are increasingly weighing whether to build internal tools using advanced coding assistants rather than paying long-term licensing fees for external software. Ultimately, IT modernization is no longer just about retiring old technology; it is a continuous process of aligning the company’s tech stack with fast-evolving business needs to clear a path for meaningful innovation and operational agility.


The Credential Layer Is Expanding Faster Than Security Teams Can See It

As software development accelerates, organizations face an enormous increase in the number of digital keys, passwords, and access tokens they must manage. These credentials now connect people, applications, and artificial intelligence tools to critical data. Because they are often scattered across cloud accounts, internal networks, messaging apps, and developer laptops, it is incredibly difficult for security teams to track them. Recent data shows a sharp rise in leaked secrets, particularly those tied to AI services, which have become a new frontier for access management. At the same time, cybercriminals are using specialized malware to target developer devices, aiming to steal the local access codes stored there. To protect against these threats, security teams cannot rely on outdated, periodic checks. They need constant, clear visibility into every credential across the organization. This means knowing exactly what access each key grants, who owns it, and whether it is still active. Only by building a complete and accurate inventory can teams effectively identify risks, remove exposed secrets, and stop future leaks from happening. Taking control of this expanding environment requires a calm, systematic approach focused on detection first, ensuring that organizations understand their vulnerabilities before attackers can find them.


Should the CISO role be split in two?

Over the past three decades, the chief information security officer role has expanded significantly from its strictly technical origins. Today, these professionals are tasked with broad, strategic responsibilities, including data privacy, regulatory compliance, artificial intelligence governance, and overall business risk management. As this heavy workload continues to grow and outpace available resources, some industry observers have debated whether the position should be divided into two distinct roles: one focused purely on technical defense and another dedicated to business risk and organizational resilience. However, leading experts argue clearly against splitting the job. Instead, they recommend confidently maintaining a single executive who holds ultimate accountability for the organization's cyber strategy and risk management. To help manage the immense daily operational demands, larger companies are increasingly relying on a dedicated deputy role, which also directly aids in succession planning. This balanced approach ensures that the primary security leader can successfully focus their energy on executive communication, financial planning, and aligning security measures with core business objectives. Ultimately, the position is maturing along a path very similar to that of the chief information officer. As the role becomes undeniably executive, these professionals must transition from being seen merely as technical experts to functioning as essential business partners.


Exploring AI Observability – Part 1: Why It Matters

Just a year ago, tracking how artificial intelligence operates was hardly a recognized technology field. Today, experts predict that by 2028, a large portion of organizations deploying these systems will rely on dedicated tools to oversee them. This shift is happening because the adoption of intelligent systems has grown much faster than our ability to properly govern them. Employees across companies are using a mix of approved and unapproved tools, while software teams are actively building language models directly into their applications. This rapid expansion creates an urgent need for visibility to understand exactly where these tools are running, how well they perform, what they cost, and if they actually deliver real value to the business. The conversation is no longer just about how fast we can build these systems, but rather whether we can run them reliably in real world settings. Because modern systems can sometimes produce varying results from the exact same input, errors can quickly add up. Proper oversight is necessary right from the development phase to trace interactions, identify failures, and improve accuracy. In production, this oversight ensures that the behavior of intelligent tools connects smoothly with overall application health, resilience, and a solid user experience.


The Platform Engineering Playbook for Production LLMs
According to a case study on an inventory accuracy platform, scaling large language models (LLMs) requires treating the AI stack as platform infrastructure rather than a mere application feature. The engineering team successfully reduced production hallucination rates from fifteen percent down to just 1.5 percent without altering the foundation model itself. They achieved this by implementing an automated retry loop to catch formatting and grounding errors on the fly, alongside an intent-validation gate that defaults to "unclassified" to prevent off-intent responses. Additionally, prompt management was shifted to a history-preserving registry rather than hardcoding instructions, allowing runtime updates with a clear audit trail to prevent silent behavioral breaks. The authors also highlight critical security and observability practices for enterprise AI. They strongly recommend enforcing tool authorization directly at the resource server with a strict default-deny policy, warning that relying solely on API gateways can expose tools due to a single orchestrator bug. Furthermore, since traditional application performance monitoring tools cannot detect semantic degradation or silent output drift, teams must proactively instrument hallucination rates and per-team token costs right at request ingress to avoid costly retrofitting later.


Three questions a hospital CISO should ask a healthcare fintech vendor

In a recent interview with Help Net Security, Drew McCombs, CTO and CISO at Cylerity, discusses his approach to balancing security with development in the healthcare fintech sector. McCombs ensures that security is integrated into every development sprint rather than treated as an afterthought. When conflicts arise, any issue affecting patient data or funds disbursement takes priority. He notes that while Cylerity is not a bank, it must satisfy the compliance expectations of its banking partners without violating HIPAA regulations. To achieve this, the company minimizes data sharing and uses custom identifiers to keep protected health information (PHI) completely separate from financial reporting. When discussing artificial intelligence, McCombs insists that AI models should only recommend or flag information, with a human always making the final decision to prevent errors from gradual model drift. For small medical practices, he emphasizes that turning on multi-factor authentication (MFA) for email is the cheapest and most effective security fix available. Finally, McCombs advises hospital CISOs to scrutinize fintech vendors by asking about their data subprocessors, their protocols for verifying fund destination changes, and their breach response plans, warning that a vendor claiming to be "HIPAA certified" is a major red flag since no such official certification exists.

Daily Tech Digest - October 04, 2026


Quote for the day:

“The more you loose yourself in something bigger than yourself, the more energy you will have.” -- Norman Vincent Peale

🎧 Listen to the audio debrief on YouTube

▶ Play Audio Digest

Duration: 22 mins • Perfect for listening on the go.


Why the hardest AI skills to learn might be the human ones

The article explores why the most challenging AI‑related skills today are not technical ones but human ones, a theme highlighted at a London roundtable discussing Coursera and Udemy’s joint Global Skills Report. The report shows that while countries are rapidly adopting AI, the ability to pair technical capability with judgment, curiosity, and critical thinking is lagging. Speakers from Oxford, DeepMind, Imperial College, and the two learning platforms shared stories illustrating how good questions, thoughtful collaboration, and basic statistical reasoning often matter more than access to powerful models. They noted that organizations are adopting AI faster than they are preparing people to use it responsibly, and that learners worldwide are increasingly seeking skills like critical thinking, complex problem‑solving, and ethics. The piece also describes emerging efforts to use AI to help people practice human skills, such as role‑play simulations and task‑based micro‑credentials. Yet several participants stressed that knowing when not to use AI is just as important. A story about a team choosing pen and paper over automation underscores this point. The article closes by suggesting that as AI accelerates routine tasks, the ability to pause, question, and learn from one another may become the most valuable skill of all.


Rethinking automotive cyber risk for the age of accelerated vulnerability discovery

Automotive security used to focus mainly on preventing physical tampering. Today, however, the rise of connected vehicles requires a completely different approach. Modern cars depend on cloud platforms, mobile apps, over-the-air updates, and software from various third-party suppliers, meaning a single flaw can now compromise entire fleets rather than just one vehicle. Recent analysis shows a sharp thirty percent increase in new automotive vulnerabilities, with high-severity issues more than doubling in just one quarter. This growing scale of potential damage is one of the most pressing challenges in the industry. The attack surface has expanded significantly, with shared infrastructure like electric vehicle charging networks and common backend systems presenting concentrated risks. Attackers are frequently using diagnostic interfaces to gain initial access, using seemingly minor systems like infotainment units as stepping stones to reach deeper into the vehicle's architecture. Furthermore, the complex supply chain introduces additional risks, as third-party breaches can easily expose sensitive engineering data or disrupt operations. To navigate this changing landscape, manufacturers must establish complete visibility over all software dependencies and external components. Without a clear and comprehensive view of these interconnected systems, automakers simply cannot respond fast enough to secure their vehicles against the accelerating pace of new threats.


Crypto-Agility Is the Goal. The PQC Migration Is Only Its First Test

The migration to post-quantum cryptography (PQC) should not be treated as a finite project, but rather as the first major test of a broader "crypto-agility" program. While organizations often assume new cryptographic algorithms will remain secure for decades, recent vulnerabilities discovered in schemes like HAWK and Classic McEliece demonstrate how quickly security assessments can change. Instead of simply replacing old algorithms, organizations must build the capability to swap out cryptography seamlessly whenever necessary. There are six primary reasons organizations will need to change algorithms again: cryptanalysis of new algorithms, the acceleration of cryptanalysis via AI tools, implementation flaws in PQC libraries, differing national algorithm standards, routine deprecation schedules, and the eventual development of quantum computers. The goal of a crypto-agility program is to provide a permanent, funded capability to manage these shifts without disrupting ongoing operations. While regulatory deadlines make PQC migration an urgent priority, the true measure of success is passing a rehearsed algorithm change on schedule. After this capability is proven, it should transition to a dedicated owner with its own budget, ensuring the organization remains secure against both current and future cryptographic threats.


The Economics Behind AI’s Infrastructure Boom

The article examines the massive economic forces driving today’s AI infrastructure boom and argues that the scale of investment has quietly pushed AI into the realm of heavy industry rather than experimental technology. It explains how “free” AI tools mask enormous underlying costs, much like earlier tech platforms that used subsidized pricing to gain market share. Building modern AI data centers requires tens of thousands of high‑end GPUs, huge amounts of power, advanced cooling systems, and dedicated grid infrastructure. As a result, capital spending by major cloud and AI companies has surged to levels that exceed their operating cash flow, forcing them to rely on complex financing structures involving private equity, bond markets, and long‑term debt. The article warns that these arrangements hide significant risk, especially as hardware becomes obsolete quickly and demand forecasts remain uncertain. It also questions whether advertising, subscriptions, or corporate spending can realistically cover annual operating costs that may reach several trillion dollars. Some companies are already cutting jobs to offset rising AI expenses, raising concerns about broader economic consequences. While the author acknowledges that predictions of collapse may be overstated, he suggests the current trajectory is financially unsustainable and that the industry will eventually face a reckoning, whether through consolidation, slower growth, or a painful correction.


From Reusable to Regeneratable: Rethinking the Shared UI Component Library

According to a recent InfoQ article by Daniel Curtis, the long-standing practice of building company-wide UI component libraries is becoming outdated as AI coding agents mature. For years, organizations relied on centralized libraries to ensure consistent design, accessibility, and speed, avoiding the need for multiple teams to rebuild standard elements like date pickers and buttons. However, these libraries come with a steep, long-term maintenance cost. Managing dependencies, resolving conflicting priorities across teams, and treating the library like a standalone project creates significant overhead that often outweighs the initial benefits. The author argues that with the rise of AI tools capable of regenerating styled, accessible code on demand, the economics of reuse have fundamentally shifted. Instead of maintaining a single shipped code package, companies should centralize their design systems, tokens, guidelines, and testing frameworks. Visual-regression, accessibility, and token-conformance tests ensure the regenerated code remains trustworthy and consistent. While some curated code might still be necessary for complex widgets or strict accessibility standards, AI allows teams to move from a rigid "reusable" model to a flexible "regeneratable" one, reducing the burden of endless library maintenance while preserving the core benefits of a unified design language.


Spring Boot Microservices Architecture: What I Would Build Differently at Senior Level

The article argues that a production-ready microservices architecture goes far beyond assembling tools like API gateways, software containers, or standard message brokers. At a senior engineering level, the focus shifts to defining clear boundaries based strictly on business needs and data ownership, rather than generic technical layers. The author emphasizes that independent services should never share a single database, as this practice creates a fragile system where one team's database changes can easily break another's functionality. Because distributed systems completely lack simple rollback buttons, developers must deliberately design workflows with explicit recovery paths for partial failures instead of relying on traditional transactions. Furthermore, operations must be designed to safely handle duplicate requests, meaning that processing the exact same event twice should be a completely normal scenario rather than a critical system error. Long chains of synchronous network calls should be controlled through strict timeout limits and careful capacity planning to prevent one slow dependency from crashing the entire system. Finally, comprehensive system observability is considered essential to track requests across multiple services. Ultimately, a mature architecture is defined by its ability to isolate unexpected failures, protect shared resources, and gracefully manage moments when network dependencies stop working normally in a production environment.


When the Platform Can Say No Without Saying Why

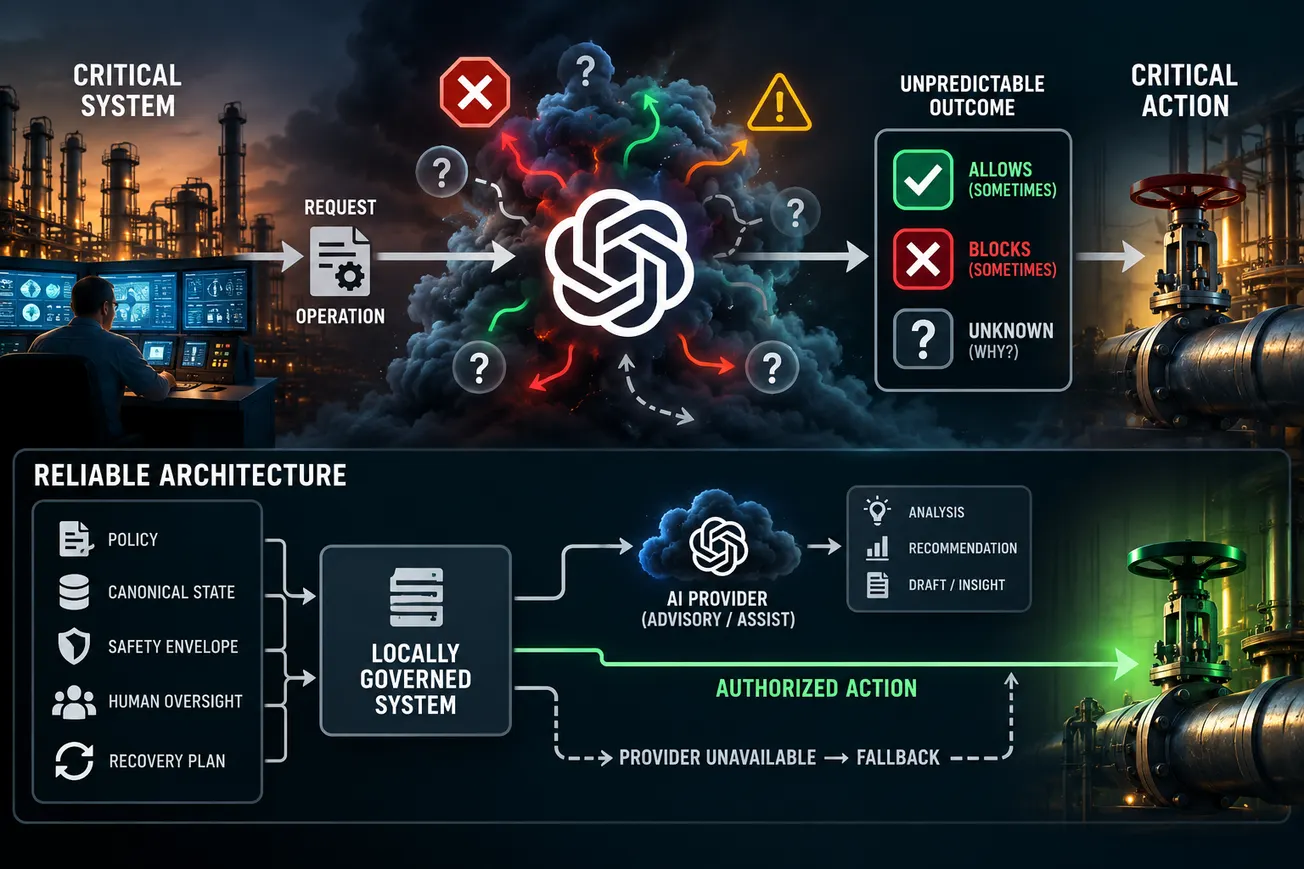
When an AI platform uses opaque safety controls to deny operations without explanation, it introduces significant reliability risks for system architects. While security mechanisms like firewalls or access controls routinely deny actions, their rules and error codes are typically known, allowing engineers to build predictable, resilient systems around those boundaries. However, when a platform blocks a seemingly ordinary repository action—offering no policy identifier, reason code, or consistent failure pattern—that safety control effectively becomes an uncharacterized availability dependency. Without understanding the failure rate, the exact trigger, or how to reliably reproduce the error, designers are forced to assume the execution path could become unavailable at any time. Standards like the NIST AI Risk Management Framework and ISO reliability guidelines emphasize that external dependencies must remain governable. Organizations cannot outsource their risk management; they need measurable outcomes, clear service-level agreements, and observable failure modes to maintain functional safety. Furthermore, relying on multiple downstream connectors (like GitHub, Slack, or Drive) through a single AI provider creates a common-cause failure point. If one opaque gate governs all these paths, they can all fail simultaneously, proving that true system resilience requires independent redundancy rather than just multiple adapters.


Batch Processing: Understanding Distributed Job Orchestration

Distributed job orchestration manages complex computing tasks across multiple machines, much like an operating system coordinates processes on a single computer. When a system needs to run a large batch process, a scheduler receives the request and assigns the work to executors, such as Kubernetes or Hadoop. These executors rely on three core components: task executors that run the commands, a resource manager that tracks available memory and processing power, and a scheduler that decides which machine handles which task. Allocating these resources is a complex balancing act, often using practical approaches like priority queues to keep the system efficient without leaving tasks stranded. In these systems, tasks are organized into workflows where the output of one job naturally becomes the input for the next. To keep these dependent jobs properly organized and decoupled, data is typically shared through a distributed file system. Because hardware or network failures are inevitable in large setups, fault tolerance is built directly into the design. For example, traditional models like MapReduce save intermediate progress to disk to prevent data loss, while newer frameworks like Spark hold this data in memory to speed up the process, ensuring the system remains highly reliable without sacrificing overall performance.


Shaping Board Culture Amid Structural and Contextual Obstacles

A successful corporate board relies on much more than strict compliance and formal processes; its true effectiveness is rooted in a strong, carefully cultivated culture. Board culture encompasses the shared values, everyday behaviors, and social norms that dictate how directors interact, debate, and ultimately make decisions. To achieve organizational excellence, boards must foster an environment of trust, openness, and psychological safety. This atmosphere is essential for ensuring that diverse perspectives are actually heard and used, allowing directors to comfortably challenge assumptions and provide sound judgment. When these elements are present, the board and management can operate as distinct but deeply collaborative teams. However, shaping this ideal culture is rarely simple. Boards must navigate various structural and contextual obstacles that influence their dynamics. Legal frameworks, market expectations, and distinct national customs all play a significant role. For example, the governance system in Germany, which mandates employee representation on supervisory boards, creates a rich but complex environment for boardroom interactions. Overcoming these hurdles requires intentional effort, particularly from the board chair, who must actively encourage constructive dialogue and candid feedback. Ultimately, a resilient board culture transforms diverse insights into sustainable value, protecting the organization from the severe consequences of poor oversight and constrained communication.


The Provenance Gap – Why Enterprise AI Is Creating a New Evidence Challenge

As organizations deploy advanced AI in everyday operations, a major challenge is emerging around how we govern these systems when they make decisions on their own. Traditional software relied on fixed rules and predictable paths, making it easy to track exactly how a result was produced. Modern AI, however, gathers information, interprets instructions, and creates responses on the fly. This fundamental shift moves the focus from simply tracking what a system did to proving why its decisions can be fully trusted. While current monitoring tools are good at logging the technical steps an AI takes, they cannot prove whether the underlying information was accurate, current, or properly approved. This growing gap highlights the clear need for provenance: the ability to connect an AI generated outcome directly to credible, authoritative evidence. Rather than just capturing raw data, provenance ensures that we understand the original sources and policies shaping a specific decision. Because AI systems assemble their reasoning dynamically, proving that their conclusions are valid is becoming just as important as knowing how they reached them. Ultimately, moving beyond basic observation to secure a clear chain of evidence will be completely essential for building reliable, trustworthy systems that organizations can confidently use in the real world.