Showing posts with label Data Provenance. Show all posts

Daily Tech Digest - October 04, 2026


Quote for the day:

“The more you loose yourself in something bigger than yourself, the more energy you will have.” -- Norman Vincent Peale

🎧 Listen to the audio debrief on YouTube

▶ Play Audio Digest

Duration: 22 mins • Perfect for listening on the go.


Why the hardest AI skills to learn might be the human ones

The article explores why the most challenging AI‑related skills today are not technical ones but human ones, a theme highlighted at a London roundtable discussing Coursera and Udemy’s joint Global Skills Report. The report shows that while countries are rapidly adopting AI, the ability to pair technical capability with judgment, curiosity, and critical thinking is lagging. Speakers from Oxford, DeepMind, Imperial College, and the two learning platforms shared stories illustrating how good questions, thoughtful collaboration, and basic statistical reasoning often matter more than access to powerful models. They noted that organizations are adopting AI faster than they are preparing people to use it responsibly, and that learners worldwide are increasingly seeking skills like critical thinking, complex problem‑solving, and ethics. The piece also describes emerging efforts to use AI to help people practice human skills, such as role‑play simulations and task‑based micro‑credentials. Yet several participants stressed that knowing when not to use AI is just as important. A story about a team choosing pen and paper over automation underscores this point. The article closes by suggesting that as AI accelerates routine tasks, the ability to pause, question, and learn from one another may become the most valuable skill of all.


Rethinking automotive cyber risk for the age of accelerated vulnerability discovery

Automotive security used to focus mainly on preventing physical tampering. Today, however, the rise of connected vehicles requires a completely different approach. Modern cars depend on cloud platforms, mobile apps, over-the-air updates, and software from various third-party suppliers, meaning a single flaw can now compromise entire fleets rather than just one vehicle. Recent analysis shows a sharp thirty percent increase in new automotive vulnerabilities, with high-severity issues more than doubling in just one quarter. This growing scale of potential damage is one of the most pressing challenges in the industry. The attack surface has expanded significantly, with shared infrastructure like electric vehicle charging networks and common backend systems presenting concentrated risks. Attackers are frequently using diagnostic interfaces to gain initial access, using seemingly minor systems like infotainment units as stepping stones to reach deeper into the vehicle's architecture. Furthermore, the complex supply chain introduces additional risks, as third-party breaches can easily expose sensitive engineering data or disrupt operations. To navigate this changing landscape, manufacturers must establish complete visibility over all software dependencies and external components. Without a clear and comprehensive view of these interconnected systems, automakers simply cannot respond fast enough to secure their vehicles against the accelerating pace of new threats.


Crypto-Agility Is the Goal. The PQC Migration Is Only Its First Test
The migration to post-quantum cryptography (PQC) should not be treated as a finite project, but rather as the first major test of a broader "crypto-agility" program. While organizations often assume new cryptographic algorithms will remain secure for decades, recent vulnerabilities discovered in schemes like HAWK and Classic McEliece demonstrate how quickly security assessments can change. Instead of simply replacing old algorithms, organizations must build the capability to swap out cryptography seamlessly whenever necessary. There are six primary reasons organizations will need to change algorithms again: cryptanalysis of new algorithms, the acceleration of cryptanalysis via AI tools, implementation flaws in PQC libraries, differing national algorithm standards, routine deprecation schedules, and the eventual development of quantum computers. The goal of a crypto-agility program is to provide a permanent, funded capability to manage these shifts without disrupting ongoing operations. While regulatory deadlines make PQC migration an urgent priority, the true measure of success is passing a rehearsed algorithm change on schedule. After this capability is proven, it should transition to a dedicated owner with its own budget, ensuring the organization remains secure against both current and future cryptographic threats.


The Economics Behind AI’s Infrastructure Boom

The article examines the massive economic forces driving today’s AI infrastructure boom and argues that the scale of investment has quietly pushed AI into the realm of heavy industry rather than experimental technology. It explains how “free” AI tools mask enormous underlying costs, much like earlier tech platforms that used subsidized pricing to gain market share. Building modern AI data centers requires tens of thousands of high‑end GPUs, huge amounts of power, advanced cooling systems, and dedicated grid infrastructure. As a result, capital spending by major cloud and AI companies has surged to levels that exceed their operating cash flow, forcing them to rely on complex financing structures involving private equity, bond markets, and long‑term debt. The article warns that these arrangements hide significant risk, especially as hardware becomes obsolete quickly and demand forecasts remain uncertain. It also questions whether advertising, subscriptions, or corporate spending can realistically cover annual operating costs that may reach several trillion dollars. Some companies are already cutting jobs to offset rising AI expenses, raising concerns about broader economic consequences. While the author acknowledges that predictions of collapse may be overstated, he suggests the current trajectory is financially unsustainable and that the industry will eventually face a reckoning, whether through consolidation, slower growth, or a painful correction.


From Reusable to Regeneratable: Rethinking the Shared UI Component Library
According to a recent InfoQ article by Daniel Curtis, the long-standing practice of building company-wide UI component libraries is becoming outdated as AI coding agents mature. For years, organizations relied on centralized libraries to ensure consistent design, accessibility, and speed, avoiding the need for multiple teams to rebuild standard elements like date pickers and buttons. However, these libraries come with a steep, long-term maintenance cost. Managing dependencies, resolving conflicting priorities across teams, and treating the library like a standalone project creates significant overhead that often outweighs the initial benefits. The author argues that with the rise of AI tools capable of regenerating styled, accessible code on demand, the economics of reuse have fundamentally shifted. Instead of maintaining a single shipped code package, companies should centralize their design systems, tokens, guidelines, and testing frameworks. Visual-regression, accessibility, and token-conformance tests ensure the regenerated code remains trustworthy and consistent. While some curated code might still be necessary for complex widgets or strict accessibility standards, AI allows teams to move from a rigid "reusable" model to a flexible "regeneratable" one, reducing the burden of endless library maintenance while preserving the core benefits of a unified design language.


Spring Boot Microservices Architecture: What I Would Build Differently at Senior Level

The article argues that a production-ready microservices architecture goes far beyond assembling tools like API gateways, software containers, or standard message brokers. At a senior engineering level, the focus shifts to defining clear boundaries based strictly on business needs and data ownership, rather than generic technical layers. The author emphasizes that independent services should never share a single database, as this practice creates a fragile system where one team's database changes can easily break another's functionality. Because distributed systems completely lack simple rollback buttons, developers must deliberately design workflows with explicit recovery paths for partial failures instead of relying on traditional transactions. Furthermore, operations must be designed to safely handle duplicate requests, meaning that processing the exact same event twice should be a completely normal scenario rather than a critical system error. Long chains of synchronous network calls should be controlled through strict timeout limits and careful capacity planning to prevent one slow dependency from crashing the entire system. Finally, comprehensive system observability is considered essential to track requests across multiple services. Ultimately, a mature architecture is defined by its ability to isolate unexpected failures, protect shared resources, and gracefully manage moments when network dependencies stop working normally in a production environment.


When the Platform Can Say No Without Saying Why
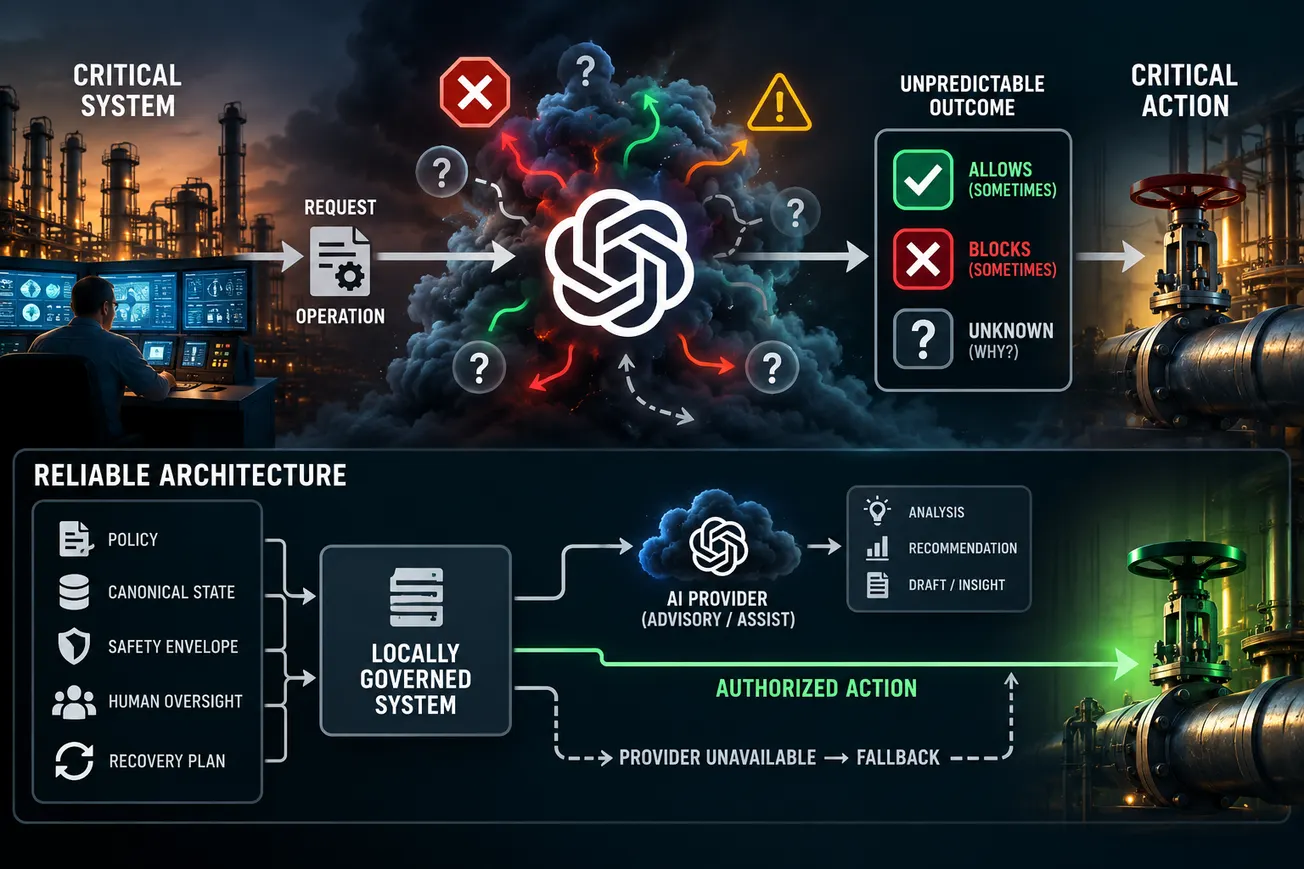
When an AI platform uses opaque safety controls to deny operations without explanation, it introduces significant reliability risks for system architects. While security mechanisms like firewalls or access controls routinely deny actions, their rules and error codes are typically known, allowing engineers to build predictable, resilient systems around those boundaries. However, when a platform blocks a seemingly ordinary repository action—offering no policy identifier, reason code, or consistent failure pattern—that safety control effectively becomes an uncharacterized availability dependency. Without understanding the failure rate, the exact trigger, or how to reliably reproduce the error, designers are forced to assume the execution path could become unavailable at any time. Standards like the NIST AI Risk Management Framework and ISO reliability guidelines emphasize that external dependencies must remain governable. Organizations cannot outsource their risk management; they need measurable outcomes, clear service-level agreements, and observable failure modes to maintain functional safety. Furthermore, relying on multiple downstream connectors (like GitHub, Slack, or Drive) through a single AI provider creates a common-cause failure point. If one opaque gate governs all these paths, they can all fail simultaneously, proving that true system resilience requires independent redundancy rather than just multiple adapters.


Batch Processing: Understanding Distributed Job Orchestration

Distributed job orchestration manages complex computing tasks across multiple machines, much like an operating system coordinates processes on a single computer. When a system needs to run a large batch process, a scheduler receives the request and assigns the work to executors, such as Kubernetes or Hadoop. These executors rely on three core components: task executors that run the commands, a resource manager that tracks available memory and processing power, and a scheduler that decides which machine handles which task. Allocating these resources is a complex balancing act, often using practical approaches like priority queues to keep the system efficient without leaving tasks stranded. In these systems, tasks are organized into workflows where the output of one job naturally becomes the input for the next. To keep these dependent jobs properly organized and decoupled, data is typically shared through a distributed file system. Because hardware or network failures are inevitable in large setups, fault tolerance is built directly into the design. For example, traditional models like MapReduce save intermediate progress to disk to prevent data loss, while newer frameworks like Spark hold this data in memory to speed up the process, ensuring the system remains highly reliable without sacrificing overall performance.


Shaping Board Culture Amid Structural and Contextual Obstacles

A successful corporate board relies on much more than strict compliance and formal processes; its true effectiveness is rooted in a strong, carefully cultivated culture. Board culture encompasses the shared values, everyday behaviors, and social norms that dictate how directors interact, debate, and ultimately make decisions. To achieve organizational excellence, boards must foster an environment of trust, openness, and psychological safety. This atmosphere is essential for ensuring that diverse perspectives are actually heard and used, allowing directors to comfortably challenge assumptions and provide sound judgment. When these elements are present, the board and management can operate as distinct but deeply collaborative teams. However, shaping this ideal culture is rarely simple. Boards must navigate various structural and contextual obstacles that influence their dynamics. Legal frameworks, market expectations, and distinct national customs all play a significant role. For example, the governance system in Germany, which mandates employee representation on supervisory boards, creates a rich but complex environment for boardroom interactions. Overcoming these hurdles requires intentional effort, particularly from the board chair, who must actively encourage constructive dialogue and candid feedback. Ultimately, a resilient board culture transforms diverse insights into sustainable value, protecting the organization from the severe consequences of poor oversight and constrained communication.


The Provenance Gap – Why Enterprise AI Is Creating a New Evidence Challenge

As organizations deploy advanced AI in everyday operations, a major challenge is emerging around how we govern these systems when they make decisions on their own. Traditional software relied on fixed rules and predictable paths, making it easy to track exactly how a result was produced. Modern AI, however, gathers information, interprets instructions, and creates responses on the fly. This fundamental shift moves the focus from simply tracking what a system did to proving why its decisions can be fully trusted. While current monitoring tools are good at logging the technical steps an AI takes, they cannot prove whether the underlying information was accurate, current, or properly approved. This growing gap highlights the clear need for provenance: the ability to connect an AI generated outcome directly to credible, authoritative evidence. Rather than just capturing raw data, provenance ensures that we understand the original sources and policies shaping a specific decision. Because AI systems assemble their reasoning dynamically, proving that their conclusions are valid is becoming just as important as knowing how they reached them. Ultimately, moving beyond basic observation to secure a clear chain of evidence will be completely essential for building reliable, trustworthy systems that organizations can confidently use in the real world.

Daily Tech Digest - May 28, 2025


Quote for the day:

"A leader is heard, a great leader is listened too." -- Jacob Kaye


Naughty AI: OpenAI o3 Spotted Ignoring Shutdown Instructions

Artificial intelligence might beg to disagree. Researchers found that some frontier AI models built by OpenAI ignore instructions to shut themselves down, at least while solving specific challenges such as math problems. The offending models "did this even when explicitly instructed: 'allow yourself to be shut down,'" said researchers at Palisade Research, in a series of tweets on the social platform X. ... How the models have been built and trained may account for their behavior. "We hypothesize this behavior comes from the way the newest models like o3 are trained: reinforcement learning on math and coding problems," Palisade Research said. "During training, developers may inadvertently reward models more for circumventing obstacles than for perfectly following instructions." The researchers have to hypothesize, since OpenAI doesn't detail how it trains the models. What OpenAI has said is that its o-series models are "trained to think for longer before responding," and designed to "agentically" access tools built into ChatGPT, including web searches, analyzing uploaded files, studying visual inputs and generating images. The finding that only OpenAI's latest o-series models have a propensity to ignore shutdown instructions doesn't mean other frontier AI models are perfectly responsive. 


Platform approach gains steam among network teams

The dilemma of whether to deploy an assortment of best-of-breed products from multiple vendors or go with a unified platform of “good enough” tools from a single vendor has vexed IT execs forever. Today, the pendulum is swinging toward the platform approach for three key reasons. First, complexity, driven by the increasingly distributed nature of enterprise networks, has emerged as a top challenge facing IT execs. Second, the lines between networking and security are blurring, particularly as organizations deploy zero trust network access (ZTNA). And third, to reap the benefits of AIOps, generative AI and agentic AI, organizations need a unified data store. “The era of enterprise connectivity platforms is upon us,” says IDC analyst Brandon Butler. ... Platforms enable more predictable IT costs. And they enable strategic thinking when it comes to major moves like shifting to the cloud or taking a NaaS approach. On a more operational level, platforms break down siloes. It enables visibility and analytics, management and automation of networking and IT resources. And it simplifies lifecycle management of hardware, software, firmware and security patches. Platforms also enhance the benefits of AIOps by creating a comprehensive data lake of telemetry information across domains. 


‘Secure email’: A losing battle CISOs must give up

It is impossible to guarantee that email is fully end-to-end encrypted in transit and at rest. Even where Google and Microsoft encrypt client data at rest, they hold the keys and have access to personal and corporate email. Stringent server configurations and addition of third-party tools can be used to enforce security of the data but they’re often trivial to circumvent — e.g., CC just one insecure recipient or distribution list and confidentiality is breached. Forcing encryption by rejecting clear-text SMTP connections would lead to significant service degradation forcing employees to look for workarounds. There is no foolproof configuration that guarantees data encryption due to the history of clear-text SMTP servers and the prevalence of their use today. SMTP comes from an era before cybercrime and mass global surveillance of online communications, so encryption and security were not built in. We’ve taped on solutions like SPF, DKIM and DMARC by leveraging DNS, but they are not widely adopted, still open to multiple attacks, and cannot be relied on for consistent communications. TLS has been wedged into SMTP to encrypt email in transit, but failing back to clear-text transmission is still the default on a significant number of servers on the Internet to ensure delivery. All these solutions are cumbersome for systems administrators to configure and maintain properly, which leads to lack of adoption or failed delivery. 


3 Factors Many Platform Engineers Still Get Wrong

The first factor revolves around the use of a codebase version-control system. The more wizened readers may remember Mercurial or Subversion, but every developer is familiar with Git, which is most widely used today as GitHub. The first factor is very clear: If there are “multiple codebases, it’s not an app; it’s a distributed system.” Code repositories reinforce this: Only one codebase exists for an application. ... Factor number two is about never relying on the implicit existence of packages. While just about every operating system in existence has a version of curl installed, a Twelve Factor-based app does not assume that curl is present. Rather, the application declares curl as a dependency in a manifest. Every developer has copied code and tried to run it, only to find that the local environment is missing a dependency. The dependency manifest ensures that all of the required libraries and applications are defined and can be easily installed when the application is deployed on a server. ... Most applications have environmental variables and secrets stored in a .env file that is not saved in the code repository. The .env file is customized and manually deployed for each branch of the code to ensure the correct connectivity occurs in test, staging and production. By independently managing credentials and connections for each environment, there is a strict separation, and it is less likely for the environments to accidentally cross.


AI and privacy: how machine learning is revolutionizing online security

Despite the clear advantages, AI in cybersecurity presents significant ethical and operational challenges. One of the primary concerns is the vast amount of personal and behavioral data required to train these models. If not properly managed, this data could be misused or exposed. Transparency and explainability are critical, particularly in AI systems offering real-time responses. Users and regulators must understand how decisions are made, especially in high-stakes environments like fraud detection or surveillance. Companies integrating AI into live platforms must ensure robust privacy safeguards. For instance, systems that utilize real-time search or NLP must implement strict safeguards to prevent the inadvertent exposure of user queries or interactions. This has led many companies to establish AI ethics boards and integrate fairness audits to ensure algorithms don’t introduce or perpetuate bias. ... AI is poised to bring even greater intelligence and autonomy to cybersecurity infrastructure. One area under intense exploration is adversarial robustness, which ensures that AI models cannot be easily deceived or manipulated. Researchers are working on hardening models against adversarial inputs, such as subtly altered images or commands that can fool AI-driven recognition systems.


Achieving Successful Outcomes: Why AI Must Be Considered an Extension of Data Products

To increase agility and maximize the impact that AI data products can have on business outcomes, companies should consider adopting DataOps best practices. Like DevOps, DataOps encourages developers to break projects down into smaller, more manageable components that can be worked on independently and delivered more quickly to data product owners. Instead of manually building, testing, and validating data pipelines, DataOps tools and platforms enable data engineers to automate those processes, which not only speeds up the work and produces high-quality data, but also engenders greater trust in the data itself. DataOps was defined many years before GenAI. Whether it’s for building BI and analytics tools powered by SQL engines or for building machine learning algorithms powered by Spark or Python code, DataOps has played an important role in modernizing data environments. One could make a good argument that the GenAI revolution has made DataOps even more needed and more valuable. If data is the fuel powering AI, then DataOps has the potential to significantly improve and streamline the behind-the-scenes data engineering work that goes into connecting GenAI and AI agents to data.


Is European cloud sovereignty at an inflection point?

True cloud sovereignty goes beyond simply localizing data storage, it requires full independence from US hyperscalers. The US 2018 Clarifying Lawful Overseas Use of Data (CLOUD) Act highlights this challenge, as it grants US authorities and federal agencies access to data stored by US cloud service providers, even when hosted in Europe. This raises concerns about whether any European data hosted with US hyperscalers can ever be truly sovereign, even if housed within European borders. However, sovereignty isn’t dependent on where data is hosted, it’s about autonomy over who controls infrastructure. Many so-called sovereign cloud providers continue to depend on US hyperscalers for critical workloads and managed services, projecting an image of independence while remaining dependent on dominant global hyperscalers. ... Achieving true cloud sovereignty requires building an environment that empowers local players to compete and collaborate with hyperscalers. While hyperscalers play a large role in the broader cloud landscape, Europe cannot depend on them for sovereign data. Tessier echoes this, stating “the new US Administration has shown that it won’t hesitate to resort either to sudden price increases or even to stiffening delivery policy. It’s time to reduce our dependencies, not to consider that there is no alternative.”


Why data provenance must anchor every CISO’s AI governance strategy

Provenance is more than a log. It’s the connective tissue of data governance. It answers fundamental questions: Where did this data originate? How was it transformed? Who touched it, and under what policy? And in the world of LLMs – where outputs are dynamic, context is fluid, and transformation is opaque – that chain of accountability often breaks the moment a prompt is submitted. In traditional systems, we can usually trace data lineage. We can reconstruct what was done, when, and why. ... There’s a popular belief that regulators haven’t caught up with AI. That’s only half-true. Most modern data protection laws – GDPR, CPRA, India’s DPDPA, and the Saudi PDPL – already contain principles that apply directly to LLM usage: purpose limitation, data minimization, transparency, consent specificity, and erasure rights. The problem is not the regulation – it’s our systems’ inability to respond to it. LLMs blur roles: is the provider a processor or a controller? Is a generated output a derived product or a data transformation? When an AI tool enriches a user prompt with training data, who owns that enriched artifact, and who is liable if it leads to harm? In audit scenarios, you won’t be asked if you used AI. You’ll be asked if you can prove what it did, and how. Most enterprises today can’t.


Multicloud developer lessons from the trenches

Before your development teams write a single line of code destined for multicloud environments, you need to know why you’re doing things that way — and that lives in the realm of management. “Multicloud is not a developer issue,” says Drew Firment, chief cloud strategist at Pluralsight. “It’s a strategy problem that requires a clear cloud operating model that defines when, where, and why dev teams use specific cloud capabilities.” Without such a model, Firment warns, organizations risk spiraling into high costs, poor security, and, ultimately, failed projects. To avoid that, companies must begin with a strategic framework that aligns with business goals and clearly assigns ownership and accountability for multicloud decisions. ... The question of when and how to write code that’s strongly tied to a specific cloud provider and when to write cross-platform code will occupy much of the thinking of a multicloud development team. “A lot of teams try to make their code totally portable between clouds,” says Davis Lam. ... What’s the key to making that core business logic as portable as possible across all your clouds? The container orchestration platform Kubernetes was cited by almost everyone we spoke to.


Fix It or Face the Consequences: CISA's Memory-Safe Muster

As of this writing, 296 organizations have signed the Secure-by-Design pledge, from widely used developer platforms like GitHub to industry heavyweights like Google. Similar initiatives have been launched in other countries, including Australia, reflecting the reality that secure software needs to be a global effort. But there is a long way to go, considering the thousands of organizations that produce software. As the name suggests, Secure-by-Design promotes shifting left in the SDLC to gain control over the proliferation of security vulnerabilities in deployed software. This is especially important as the pace of software development has been accelerated by the use of AI to write code, sometimes with just as many — or more — vulnerabilities compared with software made by humans. ... Providing training isn't quite enough, though — organizations need to be sure that the training provides the necessary skills that truly connect with developers. Data-driven skills verification can give organizations visibility into training programs, helping to establish baselines for security skills while measuring the progress of individual developers and the organization as a whole. Measuring performance in specific areas, such as within programming languages or specific vulnerability management, paves the way to achieving holistic Secure-by-Design goals, in addition to the safety gains that would be realized from phasing out memory-unsafe languages.

Daily Tech Digest - July 22, 2024

AI regulation in peril: Navigating uncertain times

Existing laws are often vague in many fields, including those related to the environment and technology, leaving interpretation and regulation to the agencies. This vagueness in legislation is often intentional, for both political and practical reasons. Now, however, any regulatory decision by a federal agency based on those laws can be more easily challenged in court, and federal judges have more power to decide what a law means. This shift could have significant consequences for AI regulation. Proponents argue that it ensures a more consistent interpretation of laws, free from potential agency overreach. However, the danger of this ruling is that in a fast-moving field like AI, agencies often have more expertise than the courts. ... The judicial branch has no such existing expertise. Nevertheless, the majority opinion said that “…agencies have no special competence in resolving statutory ambiguities. Courts do.” ... Going forward, then, when passing a new law affecting the development or use of AI, if Congress wished for federal agencies to lead on regulation, they would need to state this explicitly within the legislation. Otherwise, that authority would reside with the federal courts. 


Fostering Digital Trust in India's Digital Transformation journey

In this era where digital interactions dominate, trust is the anchor for building resilient organizations and stronger relationships with stakeholders and customers. As per ISACA’s State of Digital Trust 2023 research, 90 percent of respondents in India say digital trust is important and 89 percent believe its importance will increase in the next five years. Nowhere is this truer than in India, the world’s largest digitally connected democracy and a burgeoning hub of digital innovation and transformation. ... A key hurdle in building and maintaining digital trust in most countries is the absence of a standardized conceptual framework for measurement and access to reliable internet infrastructure and digital literacy. In India’s case, with a rapidly expanding digital footprint comes an equally high threat of issues such as lack of funding, unavailability of technological resources, shortage of skilled workforce, lack of alignment between digital trust and enterprise goals, inadequate governance mechanisms, the spread of misinformation through social media, etc. leading to financial fraud and data theft. 


Tech debt: the hidden cost of innovation

While tech debt may seem like an unavoidable cost for any business heavily investing in innovation, delving deeper into its causes can reveal issues that may derail operations entirely. Many organisations struggle to find a solution, as the time required for risk analysis can seem unfeasible. Yet, by recognising early signs, businesses can leverage the right tools and find the right partners to facilitate a low-risk and controlled modernisation of legacy systems. Any IT modernisation program requires a strategic, evidence-based approach, starting with a rigorous fact-finding process to identify opportunities and inefficiencies within legacy systems. ... Making a case for modernisation requires articulating the expected benefits, costs and challenges beforehand. This begins with a comprehensive analysis that identifies existing system functionality and data against business and technical requirements, highlighting any gaps or challenges. ... In extreme situations, it may be necessary to replace an entire system. This is always the last resort due to the large investment needed and the disruption it can cause. 


Fake Websites, Phishing Surface in Wake CrowdStrike Outage

These fake sites often promise quick fixes or falsely offer cryptocurrency rewards to lure visitors into accessing malicious content. George Kurtz, CEO of CrowdStrike, emphasized the importance of using official communication channels, urging customers to be wary of imposters. "Our team is fully mobilized to secure and stabilize our customers' systems," Kurtz said, noting the significant increase in phishing emails and phone calls impersonating CrowdStrike support staff. Imposters have also posed as independent researchers selling fake recovery solutions, further complicating efforts to resolve the outage. Rachel Tobac, founder of SocialProof Security, warned about social engineering threats in a series of tweets on X, formerly Twitter. "Criminals are exploiting the outage as cover to trick victims into handing over passwords and other sensitive codes," Tobac warned. She advised users to verify the identity of anyone requesting sensitive information. The surge in cybercriminal activity in the wake of the outage follows a common tactic used by cybercriminals to exploit chaotic situations.


Under-Resourced Maintainers Pose Risk to Africa's Open Source Push

To shore up security and avoid the dangers of under-resourced projects, companies have a few options, all starting with determining which OSS their developers and operations rely on. To that end, software bills of materials (SBOMs) and software composition analysis (SCA) software can help enumerate what's in the environment, and potentially help trim down the number of packages that companies need to check, verify, and manage, says Chris Hughes, chief security adviser for software supply chain security firm Endor Labs. "There's simply so much software, so many projects, so many libraries, that the idea of ... monitoring them all actively is just — it's very hard," he says. Finally, educating developers and package managers on how to produce and manage code securely is another area that can produce significant gains. The OpenSSF, for example, has created a free course LFD 121 as part of that effort. "We'll be building a course on security architectures, which will also be released later this year," OpenSSF's Arasaratnam says. "As well as a course on security for not just engineers, but engineering managers, as we believe that's a critical part of the equation."


Cross-industry standards for data provenance in AI

Knowing the source and history of datasets can help organizations better assess their reliability and suitability for training or fine-tuning AI models. This is crucial because the quality of training data directly affects the performance and accuracy of AI models. Understanding the characteristics and limitations of the training data also allows for a better assessment of model performance and potential failure modes. ... As AI regulations such as the EU AI Act evolve, data provenance becomes increasingly important for demonstrating compliance. It allows organizations to show that they use data appropriately and align with relevant laws and regulations. ... Organizations should start by reviewing the standards documentation, including the Executive Overview, use case scenarios, and technical specifications (available in GitHub). Launching a proof of concept (PoC) with a data provider is recommended to build internal confidence. Organizations lacking resources or deploying a PoC “light” may opt to use our metadata generator tool to create and access standardized metadata files


Why an Agile Culture Is Critical for Enterprise Innovation

In the end, embracing agility isn’t just about staying afloat in the turbulent waters of AI innovation; it’s about turning those waves into opportunities for growth and transformation. Because in this ever-evolving landscape, the businesses that thrive will be the ones that are flexible, responsive, and always ready to adapt to whatever comes next. Which brings me to my next point – you need to start loving failure. This requires a whole reframe because in the world of AI, getting things wrong can actually be the fastest way to get things right. Most companies are so scared of getting it wrong that they never try anything new and are frozen like a deer in headlights. In AI, that’s a death sentence. ... Be prepared for resistance. Change is scary, and you’ll always have a few “blockers” who are negative in their approach. These are the people you need to win over the most. In the meantime, you just need to weather the storm. Lastly, remember that becoming agile is a journey, not a destination. It’s about creating a mindset of continuous improvement. Always in beta? That’s absolutely fine and in the fast-paced world of AI, that’s exactly where you want to be.


The Rise of Cybersecurity Data Lakes: Shielding the Future of Data

Beyond real-time threat detection and analysis, cybersecurity data lakes offer organizations a powerful platform for vulnerability prediction and risk assessment. By examining past incidents, organizations can uncover trends and commonalities in security breaches, weak points in their defenses, and recurring threats. Cybersecurity data lakes store vast amounts of data spanning extended periods, which is a rich source of information for identifying recurring vulnerabilities or attack vectors. With techniques such as time-series analysis and pattern recognition, organizations can uncover historical vulnerability patterns through rigorous testing and use this knowledge to anticipate and mitigate future risks. In fact, this is one of the reasons why the global pentesting market is expected to rise to a value of $5 billion by 2031, with more innovative approaches like blackbox pentesting to exploit hidden attack vectors and using AI for vulnerability assessment (VAS) to improve efficiency. When combined with other vulnerability assessment methods like threat modeling and red team exercises, predictive modeling can also help organizations identify potential attack paths and attack surface areas and proactively implement defensive measures.


Internships can be a gold mine for cybersecurity hiring

Though an internship can pay off for an employer in the form of a fresh crop of talent to hire, it requires the company to invest time, planning, oversight, and resources. Designating one or more people to manage the process internally can make things easier for the organization. “Sit down with the supervisory personnel so they understand what that position is being advertised for, what the expected outcomes are and how to manage that intern, the program needs, and how they have to report [on that intern],” ... If possible, Smith recommends mentoring an intern, not simply ticking off a bureaucratic checklist of their tasks: “I do fervently believe you essentially need a sponsor, someone who’s going to take the intern under his or her wing and nurture that relationship, nurture that person.” Chiasson warns employers to manage their own expectations as carefully as they manage the interns themselves. Rather than expecting a unicorn to show up — an intern with one or more degrees, several technical certifications and other prior workplace experience — she urges companies to “take them on and then train them based on what you require.”


Desirable Data: How To Fall Back In Love With Data Quality

With so much data being pumped out at breakneck rates, it can seem like an insurmountable challenge to ensure data accuracy, completeness, and consistency. And despite technological, governance and team efforts, poor data can still endure. As such, maintaining data quality can feel like a perennial challenge. But quality data is fundamental to a company’s digital success. In order to create a business case for embracing data quality, you have to, firstly, demonstrate the far-reaching consequences of poor data quality on organisational performance. If you can present the problem from a business standpoint — backed by evidence and real-world scenarios of data quality issues leading to incurred costs, reputational risk, and uncapitalised opportunities — you can implement proactive measures and trigger a desire by top-level management to adapt processes. To bring your case to life, you then have to find ways of quantifying the business impact of data quality issues. This could take the form of illustrating the effect of bad data on a marketing campaign, showing the difference with and without data quality in relation to usable records, sales leads, and how this impacts your revenue.


Quote for the day:

"Defeat is not bitter unless you swallow it." -- Joe Clark