
14 ways attackers abuse cloud services to hack your enterprise
As enterprises migrate to hybrid and cloud environments, cyberattackers are evolving from "living off the land" to "living off the cloud," blending malicious activities into legitimate business traffic. Instead of relying on traditional malware that triggers alarms, adversaries are increasingly abusing trusted APIs, native administrative tools, and SaaS platforms to bypass conventional defenses. Attackers route command-and-control communications through reputable services like OpenAI, Microsoft Graph API, and Google Sheets, making the traffic look like routine developer or employee activity. They also exploit cloud identities, such as OAuth tokens and service accounts, to move laterally and access sensitive data without needing to compromise local servers directly. Further tactics include staging malware in object storage buckets, exfiltrating data via everyday tools like Slack, abusing ephemeral serverless functions to mask reconnaissance scans, and weaponizing identity tenant relationships. By exploiting the inherent trust and API-driven nature of modern cloud architecture, these cloud-native attack chains effectively turn the enterprise's operational backbone into a highly evasive attack surface.
From Microservices to Agents: the Next Evolution of Distributed Systems
The shift toward artificial intelligence agents marks a significant evolution in software architecture, moving away from traditional microservices. While microservices focused on breaking down complex applications into smaller, predictable parts with clear ownership boundaries, agentic systems focus on distributing decision-making. Instead of following pre-programmed, step-by-step logic, these new AI agents determine their actions dynamically. They analyze the context and their goals in real-time to decide which tools to use and how to sequence their reasoning. This means execution paths are no longer entirely determined during the design phase but adapt as the system runs. While this makes systems more capable of handling complex or vague situations, it introduces new challenges in reliability. The quality of a system's decisions becomes just as critical as its speed or availability. When these systems fail, they often suffer from silent drops in reasoning quality rather than crashing entirely. To manage this effectively, systems need built-in boundaries for the agents, continuous evaluation loops, and reliable fallback mechanisms.
How hybrid infrastructure is making quantum commercially actionable today
The quantum computing industry is currently in a critical "prepare for quantum" phase. While fault-tolerant quantum hardware is still developing, organizations cannot afford to wait passively. Integrating geographically isolated quantum processors with enterprise IT through secure, low-latency interconnection is an infrastructure challenge that must be addressed today. This preparation is essential for sectors like life sciences, where delays in drug discovery can be incredibly costly. A prime example is Qubit Pharmaceuticals, which utilizes a hybrid approach with its ATLAS platform. This four-layer system combines high-fidelity physics simulations, a synthetic quantum chemistry data engine, a specialized AI foundation model, and an emulator that simulates up to 40 qubits on classical hardware. By leveraging secure interconnection fabrics provided by partners like Equinix, companies can seamlessly link classical computing, HPC, AI, and early quantum capabilities. Building this hybrid infrastructure now allows organizations to experiment, gain operational familiarity, and seamlessly scale their capabilities as quantum hardware matures, ensuring they are ready to harness quantum utility when it arrives.
What Recent Cybersecurity Incidents Teach About the Duty to Mitigate Vendor and Service-Provider Risk
Recent cybersecurity incidents demonstrate that organizations face immense risks from third-party vendors and service providers, shifting the focus from internal defenses to external supply chains. Regulatory bodies increasingly expect companies to maintain a strict duty of vendor oversight, meaning organizations cannot simply outsource accountability for data protection. Real-world examples highlight this shift. The MOVEit software breach showed that companies can face severe legal and financial consequences from a vendor's vulnerability, regardless of their own internal controls. The Change Healthcare attack emphasized operational dependency risk, illustrating the disaster that occurs when a critical vendor goes offline. Furthermore, the PowerSchool lawsuit revealed that oversight must extend to subcontractors who have system access. To mitigate these threats, businesses must integrate vendor oversight into their core governance structure. This requires conducting thorough initial evaluations, negotiating clear contractual protections for incident response, and continuously monitoring vendor security practices. Treating vendor management as an ongoing legal and operational responsibility is essential for maintaining resilience when external failures cause major internal disruptions.

The CIO’s new recovery problem: Knowing what ‘good’ looks like
Disaster recovery used to focus primarily on how quickly a business could restore its systems and resume normal operations. Today, modern technology environments are far more complex, spanning cloud platforms, software-as-a-service applications, and constantly changing identities. This complexity sprawl presents a new challenge for technology leaders: figuring out what a healthy system actually looks like before attempting to restore it. Simply bringing a system back online is no longer enough if you cannot guarantee it is secure and trustworthy. To build true resilience, organizations must maintain an accurate inventory and clear dependency mapping while the environment is still functioning properly. Testing a recovery plan must also evolve beyond verifying backups. It should evaluate whether the team can make critical decisions under pressure, understand shifting dependencies, and confirm that the restored environment is safe to use. While speed remains a priority during a crisis, restoring systems without confidence introduces severe risk. Technology leaders must establish a clear definition of a trusted state before an incident ever occurs.

When Business Continuity Plans Depend on One Person Knowing What to Do
Even when business continuity plans are well-documented and regularly tested, they often contain a hidden vulnerability: relying too heavily on specific individuals. While organizations meticulously map out system and supply chain dependencies, they frequently overlook personnel dependencies. This reliance becomes clear during a crisis when teams instinctively turn to a single experienced manager, technical expert, or executive rather than following established procedures. The article suggests a straightforward way to expose this weakness during recovery exercises: deliberately remove key personnel from the scenario. If progress halts, deputies hesitate to make decisions, or critical workarounds suddenly become unavailable, the organization has identified a dangerous point of failure. These exercises often reveal that designated alternates lack the practical authority or historical knowledge to step in effectively when the primary decision-maker is absent. Recognizing these human dependencies allows organizations to correct them before a real emergency by formally documenting vital workarounds, transferring knowledge, and granting alternates the real authority they need to lead under pressure.
Can AI stop good candidates from getting lost in the hiring pile?
Artificial intelligence is shifting from a basic background tool into an active partner for recruitment teams. As hiring volumes grow, qualified applicants are frequently overlooked simply because recruiters lack the time to review everyone. To solve this, companies are using artificial intelligence voice agents to handle the initial stages of screening. These agents can conduct first-round interviews at any time, answer standard questions about the role, and generate structured reports for the hiring team. This approach eliminates long waiting periods for applicants and ensures every application receives attention. However, technology cannot replace the core of recruitment. While artificial intelligence excels at repeatable tasks and gathering information, the final decision must remain human. Assessing an individual's motivations, understanding how they think, and building a genuine connection require human judgment. Furthermore, companies must be fully transparent when using these tools. Candidates need to know they are speaking with software, not a person. When applied responsibly, this technology prevents strong applicants from falling through the cracks while preserving the vital human element of hiring.
Gartner’s top tech trends for 2027 expand—and constrain—AI capabilities
Gartner recently outlined ten strategic technology trends for 2027, focusing on expanding artificial intelligence capabilities while establishing stricter controls. Over the next few years, businesses will move beyond text-based models toward systems designed for complex math, continuous voice reasoning, and physical world simulation for robotics. As these systems produce output faster than humans can review, the second phase emphasizes necessary limits. Organizations will need dedicated frameworks to manage machine identities, verify coding output, and provide specific business context to prevent rogue actions or compliance failures. Automated security patching will also become essential to close vulnerabilities quickly. Finally, looking further ahead, companies will aim to reduce reliance on specific cloud providers by adopting easily replaceable applications and independent technologies. A notable long-term shift involves biological computing, where lab-grown organic systems could eventually handle complex data tasks using far less energy than traditional silicon hardware. By planning across these three horizons, technology leaders can balance autonomous capabilities with the security required for steady operations.
Coding Agents Moved the Bottleneck From Writing to Reviewing PRs
Artificial intelligence coding agents have significantly accelerated software development, but they have also shifted the primary bottleneck from writing code to reviewing it. Because these agents generate larger and more frequent pull requests, the volume of code needing review has outpaced the capacity of human engineers. This growing queue of unreviewed work often remains hidden because traditional productivity metrics focus on generation speed rather than review efficiency. Consequently, development teams face mounting quality debt. Overwhelmed reviewers might miss architectural flaws or security vulnerabilities, especially since AI-generated code typically looks clean and passes basic tests. To address this, organizations must recognize that hiring more reviewers is not a sustainable solution. Instead, they should implement dedicated AI review agents designed specifically to catch errors rather than generate new code. Additionally, capping the size of pull requests and tracking review metrics—such as wait times and review depth—can help maintain software quality without sacrificing the speed gained from AI development tools.
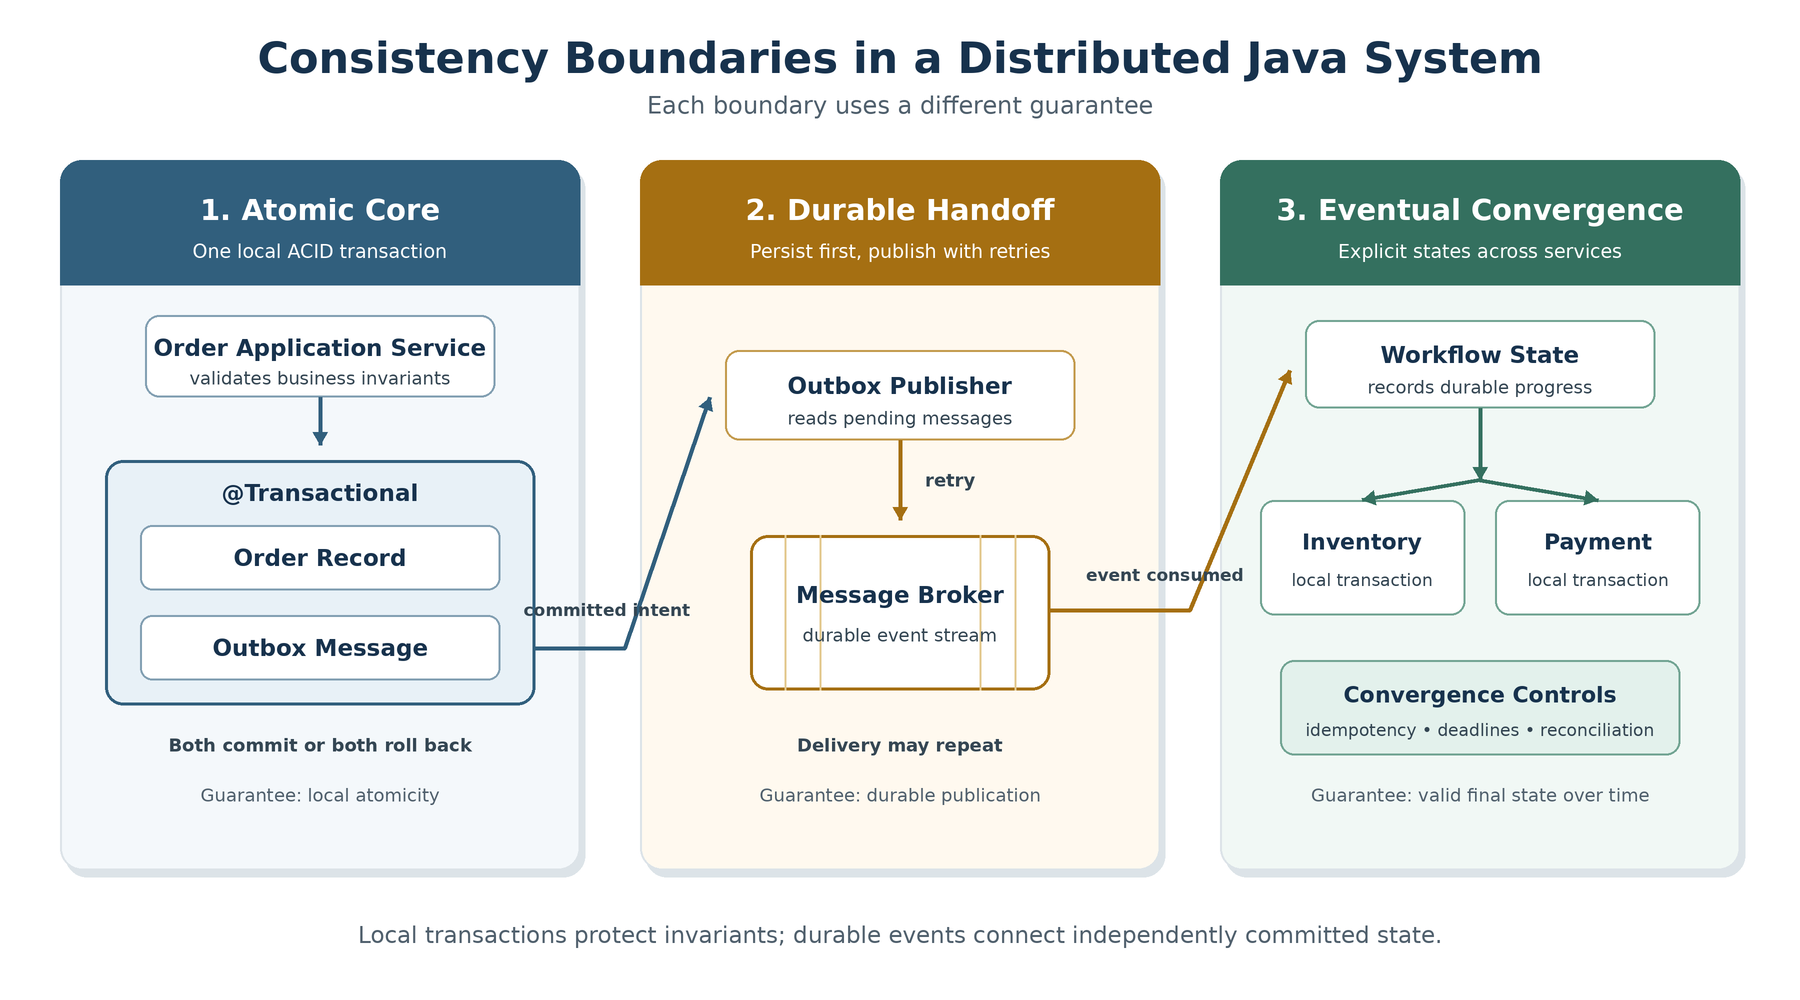
Where Should a Transaction End? Designing Consistency Boundaries in Distributed Java Systems
Designing distributed systems forces architects to decide exactly where a transaction begins and ends. Rather than splitting services first and worrying about data consistency later, the best approach starts with defining business invariants. These are the core rules that must always remain true together. The architecture should wrap its boundaries around these facts. When multiple pieces of data must change simultaneously to keep a rule intact, they belong in a single local transaction. Once that core state is secure, the system can use a durable handoff, like an outbox pattern, to safely communicate changes to other components. From there, eventual consistency can manage the broader workflow, but it must be an explicit process with clear recovery paths, not just a vague delay. Relying on synchronous call chains often creates hidden points of failure, so workflows should be modeled as durable states that can survive a crash. Ultimately, separating databases or breaking apart services is only valuable if it respects the underlying business rules that keep the entire system correct.


No comments:
Post a Comment