Quote for the day:
"The distance between insanity and genius is measured only by success." -- Bruce Feirstein
🎧 Listen to the audio debrief on YouTube
▶ Play Audio DigestDuration: 23 mins • Perfect for listening on the go.
Digital Twin Technology: A Comprehensive Guide
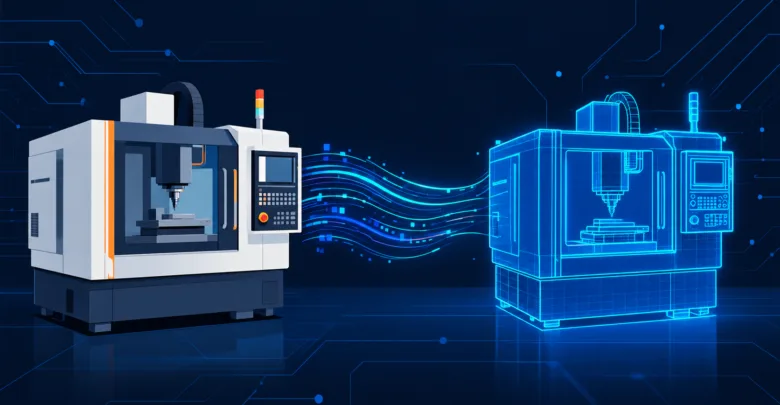 A digital twin is a dynamic, data-driven virtual replica of a physical object,
process, or system. Unlike a static 3D model or a traditional one-time
simulation, a digital twin continuously receives real-time data from sensors
attached to its physical counterpart. This steady flow of information ensures
the digital version mirrors the actual, current behavior of the real-world
entity rather than just its original design specifications. The technology
relies on three core components: the physical entity equipped with sensors, the
virtual model, and the continuous data connection linking them. By maintaining
this active connection, organizations can run highly accurate simulations, test
new scenarios, and predict failures without risking the actual physical asset.
The applications are broad and scalable, ranging from tracking a single
component like an engine bearing to managing complex networks like a
manufacturing production line or an entire modern city's infrastructure. While
the technology offers incredibly powerful predictive capabilities, building an
effective digital twin comes with several practical challenges. Organizations
must manage data quality, handle complex modeling requirements, and navigate
security concerns carefully. Because of this inherent complexity, experts
recommend starting with a single, well-defined use case before attempting to
scale up to larger, interconnected systems.
Three Hidden Traps That Shape Software Engineering Decisions
Engineering leaders face more than just technical challenges; they must also
navigate human behaviors and cognitive biases that heavily influence software
design and quality. The article outlines three common traps that developers
and technical leaders fall into. The first is the "status quo bias," where
teams stick to familiar tools or methods simply because "we've always done it
this way," often ignoring newer, more suitable options for current
requirements. The second trap is "complexity bias," which tempts engineers to
overengineer solutions by adding unnecessary layers, abstractions, or services
under the false assumption that complex designs are inherently more robust.
This often leads to systems that are harder to maintain and prone to failure.
Finally, the "broken windows" effect describes how an environment of poor code
quality or neglected technical debt silently lowers a team's engineering
standards. When developers see messy code or ignored warnings, they are more
likely to introduce new shortcuts, gradually degrading the entire system.
Recognizing and naming these biases helps teams pause, ask the right
questions, and make more deliberate, evidence-based decisions rather than
relying on flawed mental shortcuts.
 Many corporate boards believe that establishing policies and risk frameworks
is the key to governing artificial intelligence. However, Michael Covington
argues that effective AI governance is impossible without first achieving
comprehensive visibility into where and how AI is actually being used within
the organization. Just as with the adoption of SaaS, cloud computing, and
mobile technologies, companies are rushing to implement AI policies while
lacking a basic inventory of their AI assets. Currently, over 70% of
organizations deploy AI, yet more than 80% feel exposed to AI-related risks
because adoption has vastly outpaced governance. This visibility gap is
particularly dangerous because AI capabilities are increasingly embedded into
routine software updates, meaning new tools can enter the corporate
environment without any formal procurement or approval processes. This
unchecked expansion poses risks beyond just security, potentially leading to
unauthorized data access or widespread system disruptions. To solve this,
leadership must treat AI like any other core technology asset. By integrating
AI tracking into existing hardware, software, and cloud service inventories,
boards can achieve continuous visibility. This foundational step transforms AI
from an unmanaged liability into a measurable asset, allowing security,
compliance, and finance teams to govern its usage with confidence.
How can boards gain confidence in their organization’s AI adoption?
Many corporate boards believe that establishing policies and risk frameworks
is the key to governing artificial intelligence. However, Michael Covington
argues that effective AI governance is impossible without first achieving
comprehensive visibility into where and how AI is actually being used within
the organization. Just as with the adoption of SaaS, cloud computing, and
mobile technologies, companies are rushing to implement AI policies while
lacking a basic inventory of their AI assets. Currently, over 70% of
organizations deploy AI, yet more than 80% feel exposed to AI-related risks
because adoption has vastly outpaced governance. This visibility gap is
particularly dangerous because AI capabilities are increasingly embedded into
routine software updates, meaning new tools can enter the corporate
environment without any formal procurement or approval processes. This
unchecked expansion poses risks beyond just security, potentially leading to
unauthorized data access or widespread system disruptions. To solve this,
leadership must treat AI like any other core technology asset. By integrating
AI tracking into existing hardware, software, and cloud service inventories,
boards can achieve continuous visibility. This foundational step transforms AI
from an unmanaged liability into a measurable asset, allowing security,
compliance, and finance teams to govern its usage with confidence.The Factory Can Survive the Cyberattack. Can It Survive the Recovery?
Manufacturers have spent years investing in their ability to detect cyber
threats, but detecting an attack is really only the beginning of the battle.
In a factory setting, recovering from a cyber incident is far more complex
than simply restoring digital assets or standard computer applications. It
requires carefully bringing operational technology, such as programmable logic
controllers and industrial machinery, back online in the correct sequence to
avoid further issues. A technically successful software restoration can still
result in operational failure if physical processes are restarted incorrectly
or unsafely. To build true recovery readiness, manufacturers must map
production dependencies outward from the physical process rather than inward
from the network. This means identifying which critical operations must return
first and defining the specific utilities, vendors, and human approvals
required to support them. Organizations should assign recovery authority
across tech, operations, and management teams ahead of time to prevent
decision bottlenecks during an emergency. Finally, factories must practice
realistic recovery scenarios where ideal conditions, such as the availability
of key personnel or clean backups, are deliberately removed. Ultimately, a
resilient manufacturer treats operational recovery as a designed and measured
production capability, ensuring a safe, controlled return to dependable
operations across the entire plant.
Why Enterprise AI ROI Is An Architecture Problem
 Many companies struggle to see a positive financial return from their
artificial intelligence efforts because of flawed system architecture, rather
than the raw cost of the intelligence itself. Most organizations mistakenly
build these capabilities by attaching them to disjointed legacy systems,
forcing every new project to recreate rules and data connections from scratch.
This fragmentation scatters information and makes proving economic value
nearly impossible. To solve this and improve financial outcomes, businesses
must adopt four core architectural changes. First, they should mandate a
shared knowledge foundation to centralize enterprise data, eliminating the
need to repeatedly rebuild integrations for each new tool. Second, they need
to route tasks to the appropriate model based on complexity; simple tasks
should use smaller, less expensive models, reserving advanced systems only for
complex, high-value reasoning. Third, companies should prioritize groups of
specialized tools over a single, massive program. Breaking tasks down into
narrower, focused parts reduces the data processed at each step, significantly
cutting costs and improving speed. Finally, organizations must build security
and compliance directly into the core platform rather than adding them to
individual applications, ensuring controls remain reusable and highly
transparent. Ultimately, centralized architecture lowers deployment costs and
clarifies actual value for the overall business.
Website Tracking Technologies Face Growing Litigation and Regulatory Scrutiny
Many companies use website tracking technologies like pixels, software
development kits, session replay scripts, and chat tools to better understand
how visitors interact with their pages. Working quietly behind the scenes,
these tools gather data when a person clicks a button, views a product, or
fills out a form. They then share this activity with third-party analytics and
advertising companies. For years, businesses have relied on these insights to
measure website traffic, track the effectiveness of marketing campaigns, and
personalize the user experience. However, this routine data collection has
recently become the center of a rapidly expanding wave of legal and regulatory
action. Because these tools frequently transmit visitor information
automatically and often before a user formally agrees to share their data,
they have drawn severe scrutiny from privacy advocates and government
agencies. Regulators and plaintiffs' attorneys are now scrutinizing exactly
what information gets shared, with whom, and whether proper consent was
obtained. In many recent lawsuits, these common marketing tools are being
classified as wiretapping and eavesdropping devices that unlawfully disclose
personal information. Ultimately, while tracking technologies provide
businesses with valuable insights into customer behavior, they are now
introducing substantial legal risks that demand careful oversight and strict
compliance.
 Clean Architecture provides a structured way to build software by firmly
separating core business rules from external details like databases, user
interfaces, and frameworks. This approach relies on a central principle called
the Dependency Rule, which dictates that source code dependencies must only
point inward. The architecture is typically divided into five distinct layers
to manage these boundaries. At the very center are Entities, which represent
pure, framework-independent business logic that rarely changes. Surrounding
them are Use Cases, which define application-specific rules and coordinate
data flow without knowing about the database or web framework. Next are
Interface Adapters, such as controllers and presenters, which carefully
translate data between the inner core and the outside world. Further out is
the Infrastructure layer, containing concrete implementations like third-party
libraries and database adapters. Finally, the outermost layer consists of
Frameworks and Drivers, which act as the basic glue holding the application
together at startup. By strictly enforcing this inward dependency throughout
the codebase, developers can ensure their applications remain completely
testable and highly adaptable over time. This clear structure allows teams to
comfortably swap out databases or web interfaces down the line without ever
risking the fundamental logic that makes the product work.
Clean Architecture: 5 Layers Every Developer Should Understand in 2026
Clean Architecture provides a structured way to build software by firmly
separating core business rules from external details like databases, user
interfaces, and frameworks. This approach relies on a central principle called
the Dependency Rule, which dictates that source code dependencies must only
point inward. The architecture is typically divided into five distinct layers
to manage these boundaries. At the very center are Entities, which represent
pure, framework-independent business logic that rarely changes. Surrounding
them are Use Cases, which define application-specific rules and coordinate
data flow without knowing about the database or web framework. Next are
Interface Adapters, such as controllers and presenters, which carefully
translate data between the inner core and the outside world. Further out is
the Infrastructure layer, containing concrete implementations like third-party
libraries and database adapters. Finally, the outermost layer consists of
Frameworks and Drivers, which act as the basic glue holding the application
together at startup. By strictly enforcing this inward dependency throughout
the codebase, developers can ensure their applications remain completely
testable and highly adaptable over time. This clear structure allows teams to
comfortably swap out databases or web interfaces down the line without ever
risking the fundamental logic that makes the product work.
The duality nobody priced in: The changing landscape of enterprise tech architecture and Agentic AI era
Enterprise technology is currently undergoing its most significant architectural shift in thirty years, driven primarily by the transition to agentic artificial intelligence. For decades, traditional enterprise systems were designed to standardize business processes, keeping core operations highly structured while placing customizations and early AI tools safely at the outer edges. Generative AI fundamentally breaks this familiar pattern by moving from transaction-driven operations to intent-driven software. Instead of following rigid, pre-defined rules, agentic applications accept a specific goal and determine their own path, effectively shifting business logic into a complex central orchestration layer. While this promises considerably faster software production, it introduces substantial new challenges in data governance, cost management, system testing, and operational oversight. Organizations now face a choice in how to integrate this technology: replacing old automation, layering agents over existing systems, running them in parallel, or embedding them deeply into core frameworks. Ultimately, true success requires much more than just launching rapid prototypes to showcase capabilities. The enterprises that will thrive in the coming decade are those that resist the urge to rush and instead focus on building robust architectural foundations, carefully balancing the speed of new technology with necessary operational reliability and long-term security.With the Rise of AI Agents, SOC 2 Should Adapt or Risk Irrelevance
 The rapid adoption of AI agents is exposing significant blind spots in
traditional SOC 2 compliance frameworks. Originally designed with human actors
in mind, SOC 2 controls rely on foundational assumptions that do not apply to
machine identities. Because the framework does not explicitly mandate treating
AI agents as a distinct class of users, organizations can pass audits while
harboring unrecognized security risks. Specifically, four core assumptions are
now breaking down. First, unlike human users who require formal approval
before account creation, agents are often spawned automatically or indirectly.
Second, determining the true owner of an agent is frequently a matter of
guesswork rather than a clear record. Third, because AI agents often operate
using borrowed human credentials, access logs cannot reliably distinguish
between human and machine activity. Finally, traditional least-privilege
principles limit an agent's reach but fail to explain its actual intended
purpose. These gaps weaken critical controls, such as offboarding processes
that overlook active agents tied to former employees, and change management
where agents bypass genuine segregation of duties. To maintain true security,
organizations must look beyond the compliance checklist, intentionally track
machine identities, and match an agent's access directly to its specific
purpose.

