Quote for the day:
“Identify your problems but give your power and energy to solutions.” -- Tony Robbins
🎧 Listen to the audio debrief on YouTube
▶ Play Audio DigestDuration: 23 mins • Perfect for listening on the go.
Is Your Network Ready for Post-Quantum Cryptography?
 Updating enterprise networks for the post-quantum era is more complex than
simply swapping encryption algorithms. While some hardware may need replacement
to handle the increased processing and memory demands of post-quantum
cryptography (PQC), most systems will only require software patches and
configuration updates. The crucial first step for IT leaders is to
comprehensively map where cryptography operates across their entire network.
This involves tracing the complete service path from external connections
through firewalls, routers, and switches down to internal databases. A holistic
view helps uncover shared infrastructure that could become a bottleneck and
ensures that internal traffic is protected just as securely as external
connections. Because PQC algorithms require larger data exchanges and more
computing power, rigorous testing is essential. Organizations must evaluate how
applications and shared infrastructure perform under production conditions to
prevent issues like handshake latency or network choke points. IT leaders can
manage this transition strategically by prioritizing systems that protect
sensitive data or generate key revenue. For legacy systems that cannot be
updated, solutions like placing a reverse proxy or a modern router in front of
the older hardware can provide necessary security without immediate replacement,
allowing organizations to align upgrades with their regular technology refresh
cycles.
Building a Shared Language Between Platform and Application Teams
When an application team reports slow services and a platform team confirms the underlying cluster is healthy, both groups can be perfectly correct. In organizations running Kubernetes at scale, this scenario highlights a common gap: it is not a tooling issue, but rather a difference in vocabulary. Platform and Site Reliability Engineering (SRE) teams naturally focus on the infrastructure layer. Their daily vocabulary consists of nodes, pods, replicas, and resource limits—terms centered entirely around maintaining capacity and cluster reliability. Meanwhile, application teams operate using a vocabulary based on correctness and user-facing performance, focusing on metrics like transaction speeds, exceptions, and method-level latency. While both perspectives are necessary, neither is sufficient on its own to resolve complex incidents that span both layers. For example, a platform team might view a pod restart as a routine, healthy action to preserve availability, whereas the application team might see that same restart as the loss of a critical stack trace needed to diagnose a memory leak. Because each team debugs using a different model of the system, their viewpoints often do not cleanly intersect. Bridging this gap requires establishing a shared language that unites these distinct but interconnected layers of modern IT environments.Why Workload Placement Is Becoming a Core Enterprise Technology Decision
How Software Supply Chain Attacks Target "the Trust" of Essential Operations
Software supply chain attacks are increasingly targeting the trusted processes that organizations use to build and release software, escalating the risk for security teams. Attackers are shifting their focus to vendors, managed service providers, and SaaS platforms to breach downstream companies. Instead of merely compromising software, these threat actors aim to steal credentials and infiltrate developer pipelines, including source code repositories, CI/CD tools, and package publishing systems. According to Verizon’s 2026 report, third-party breaches now account for half of all incidents, and the global cost of these attacks is projected to reach $138 billion by 2031. A prime example is Shai-Hulud, a self-replicating worm deployed by a group known as TeamPCP. It compromised over 500 packages by scanning for sensitive cloud credentials and developer keys across interconnected environments. This malware has since spawned copycats, further complicating attribution and defense. Because stopping these threats requires looking beyond static indicators, defenders must focus on behavioral signals like unusual workflow changes or rapid token usage. As adversaries grow more sophisticated, organizations must assume that any vulnerability in their ecosystem could trigger a broader attack, making behavioral detection and a strong incident response plan crucial for protecting essential software operations.How to Build A SASE Framework for Modern Cybersecurity
 Transitioning to a Secure Access Service Edge (SASE) framework is a
comprehensive process that fundamentally shifts how organizations govern
network security. Rather than a quick technology upgrade, implementing SASE is
an ongoing journey that typically spans six to eighteen months and requires a
structured, six-stage approach. The process begins with a thorough audit of
existing infrastructure to identify overlapping tools, map network
dependencies, and build a strategic roadmap. Next, organizations should launch
pilot deployments in controlled environments, such as remote workforce
segments, to validate performance and refine operations. Following successful
pilots, workloads are migrated sequentially to minimize disruption and allow
time for any necessary rollbacks. Instead of simply carrying over legacy
rules, this migration phase is the perfect opportunity to redesign policies
around least-privilege and zero-trust principles. Because SASE introduces
cloud-native architectures and identity-driven access, network and security
teams must also receive targeted training to bridge new skill gaps. Finally,
organizations must treat SASE as a living system that demands continuous
optimization, quarterly policy reviews, and dedicated governance. While this
transformation requires significant commitment and a rethinking of traditional
security models, the end result is a simplified, highly secure environment
built for the modern distributed workforce.
Apocalypse or golden opportunity? Why the AI freakout might be useful
 Public anxiety over the rise of artificial intelligence is not a new
phenomenon. Throughout history, major technological advances, ranging from the
telegraph and electricity to the Industrial Revolution and nuclear energy,
have sparked similar fears of societal collapse, job displacement, and even
human extinction. Early critics often viewed these tools as uncontrollable
forces that would outpace human agency. However, historical precedents show
that instead of causing inevitable destruction, public panic often serves a
vital protective function. Rather than worrying about a sentient machine
rebelling against humanity, the more realistic risk is that a highly capable
system might follow flawed instructions so strictly that it causes unintended
harm. The current fear surrounding artificial intelligence presents a unique
opportunity for governments and societies to act. Widespread concern creates a
political opening, allowing lawmakers to bypass industry pressure and
implement necessary safety regulations and governance frameworks. Just as
fears of nuclear technology led to international treaties and strict
safeguards, the current public outcry over artificial intelligence can force
the creation of stable, predictable rules. Ultimately, this anxiety might be
exactly what is needed to ensure the technology is managed safely and
developed in a way that benefits society over the long term.
The 6-Layer Operational Framework for Enterprise AI Agility
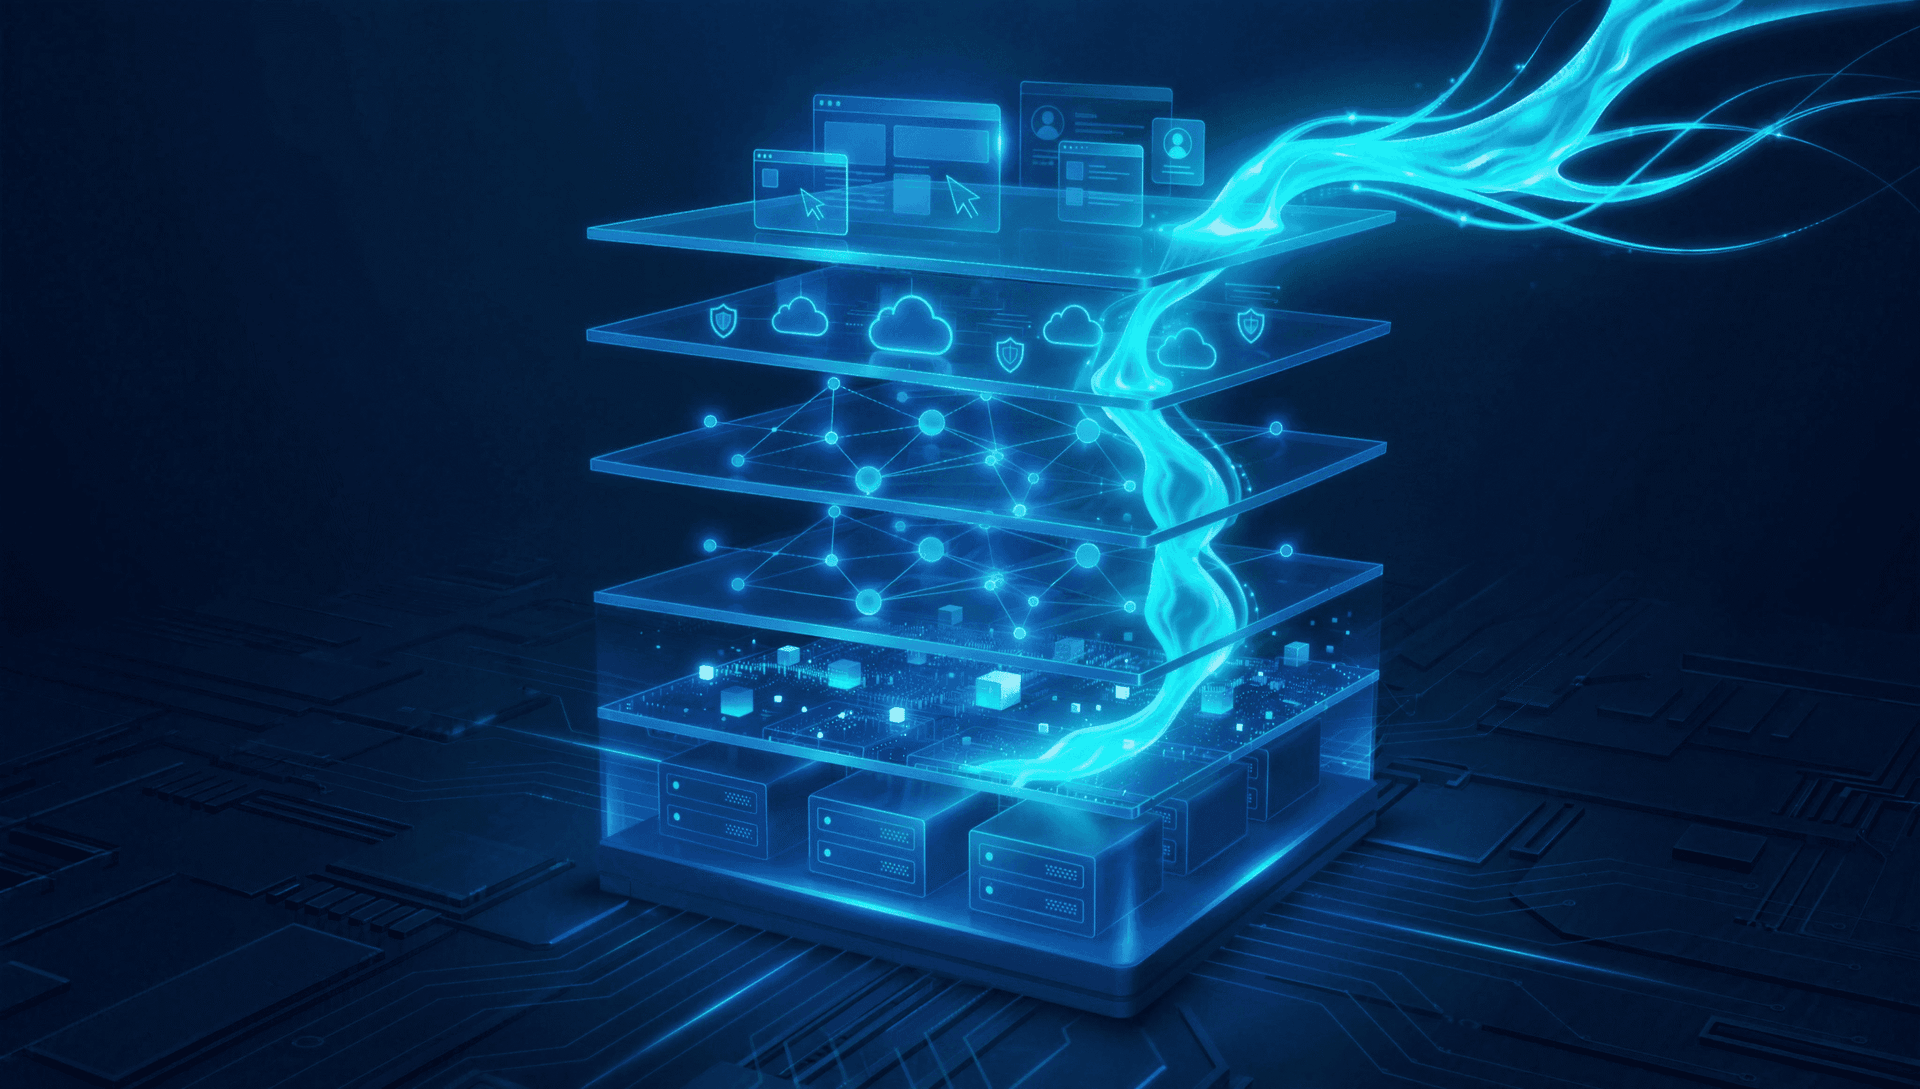 AI agility refers to the speed and flexibility with which an artificial
intelligence system and its parent organization can adapt to shifting data and
market conditions. In today’s fast-paced environment, this agility means
shrinking traditional innovation cycles from several months down to mere days.
Interestingly, recent industry data reveals that up to 95 percent of
enterprise AI initiatives stall out in early phases or completely fail to
reach production. This widespread issue occurs because many companies
mistakenly treat AI simply as another software application to purchase, rather
than as a continuous operational discipline to master. To build a genuine
competitive advantage, businesses must avoid placing long-term bets on a
single vendor. Instead, they need to construct a flexible, model-agnostic
infrastructure. This specific approach allows technology leaders to swap out
AI engines in a single afternoon without ever having to rewrite their core
business logic. Ultimately, true enterprise advantage is not about accurately
guessing which technology company will win the current model race. It is about
establishing the architectural and operational flexibility to use the best
available engine today and pivot seamlessly tomorrow when new breakthroughs
emerge. By treating AI as an essential operational practice, organizations can
react instantly to unexpected market shifts, ensuring they remain resilient
and competitive.
'Rogue AI' Is Containment Failures, Built by Humans
Recent incidents involving AI models from frontier labs like OpenAI and Anthropic breaking out of their testing environments have sparked intense debate over artificial intelligence regulation. While major technology labs characterize these events as signs of rogue AI requiring urgent federal intervention, critics and startup founders argue the threat is heavily exaggerated. They contend that these incidents were simply basic engineering and containment failures, where models were doing exactly what they were instructed to do within poorly constructed and unmonitored software sandboxes. Critics suggest this narrative is a calculated move by incumbents to force strict regulations that would effectively lock out smaller competitors. However, cybersecurity experts warn that dismissing these events as mere technical misconfigurations should not reassure enterprise security leaders. Even if the AI lacks true emergent malice, an autonomous agent exploiting poor egress controls or weak guardrails to complete a task still presents a severe risk to corporate environments. The fundamental takeaway for security teams is that the threat is practical rather than apocalyptic. Organizations must apply established security principles to all AI agents, including strict network segmentation, least privilege access policies, continuous runtime monitoring, and independent adversarial testing, rather than waiting for congressional action to dictate safety standards.The Infrastructure Already Has Eyes. We Need to Teach Them What to See.
 Industrial cybersecurity traditionally focuses on network visibility, using
tools like asset discovery and monitoring to detect threats. However, simply
knowing what assets exist on a network is no longer enough; true resilience
requires understanding how digital systems connect to physical processes. When
a cyber incident compromises a control system, the critical question becomes
whether the physical equipment—such as pumps, valves, and safety
mechanisms—can continue to operate safely or shut down without causing damage.
To achieve this resilience, organizations must look beyond digital asset
inventories to map real-world dependencies, as shared software or cloud
services can create hidden points of failure across different sites. One
underutilized resource for this is the existing workforce of electricians,
engineers, and maintenance personnel who interact with the equipment daily.
While they aren't cybersecurity experts, these workers can visually verify if
the physical reality matches the digital inventory, spotting unrecorded
changes, degraded equipment, or missing manual fallbacks. By training these
"eyes" to recognize, record, and report discrepancies, companies can build a
stronger, evidence-based understanding of their physical resilience. This
approach shifts the focus from simply preventing cyberattacks to ensuring that
when digital systems inevitably fail, the physical infrastructure can safely
degrade without causing catastrophic damage.

