Quote for the day:
"An inch of movement will bring you closer to your goals than a mile of intention." -- Vala Afshar
🎧 Listen to the audio debrief on YouTube
▶ Play Audio DigestDuration: 29 mins • Perfect for listening on the go.
Making the Case to the Board for Post-Quantum Readiness
 When presenting post-quantum readiness to the board, technology leaders must
avoid technical physics jargon and instead frame the conversation entirely
around business exposure. Directors do not need a lesson on qubits; they need
to understand which critical services and data are vulnerable and what the
transition will cost. A primary concern is the “harvest now, decrypt later”
tactic, where attackers steal encrypted sensitive data today to break it when
quantum capabilities mature. Because sensitive information retains its value
for decades, the threat is immediate. Leaders should avoid predicting an exact
date for when quantum computers will break current encryption. The focus
should remain on the long lead time required for migration, which can span up
to fifteen years. To secure board approval, leaders should ask for funding in
manageable stages. The initial request should focus on discovery, giving the
team about eighteen months to assess vulnerable cryptography, identify
critical services, and map third-party dependencies before proposing a massive
enterprise-wide budget. Waiting only increases the final price tag and risk.
Ultimately, framing this as a staged, no-regrets investment builds trust and
ensures the organization strengthens its overall security foundation
regardless of when the quantum threat fully materializes.
AWS’s repeated problems with AI agent controls illustrates the autonomous agent dilemma
 Recent security vulnerabilities in AWS AgentCore highlight a fundamental
dilemma for enterprise technology leaders: the very autonomy that makes
artificial intelligence agents useful also makes them inherently dangerous.
Cybersecurity researchers from Palo Alto Networks and Zenity Labs repeatedly
found that attackers could use simple prompt injections to trick these agents
into handing over plain text credentials. Because agents require tools like
shell commands and network access to function, they operate in the same
environments where sensitive data is stored. In one severe example,
researchers compromised a single agent and gained the ability to extract
source code, access other agents, read private conversations, and persistently
poison memory. This memory poisoning is particularly concerning because,
unlike stolen credentials that can simply be rotated, altered memories quietly
steer future actions and are incredibly difficult to detect. While AWS has
worked to patch these specific entry points, the underlying issue is that the
agents functioned exactly as designed by fulfilling the requests they
received. This means the responsibility falls heavily on organizations.
Technology teams must therefore strictly enforce proper access limits, closely
monitor all agent behavior, and carefully control the potential damage to
prevent a single compromised agent from exposing the entire network
environment.
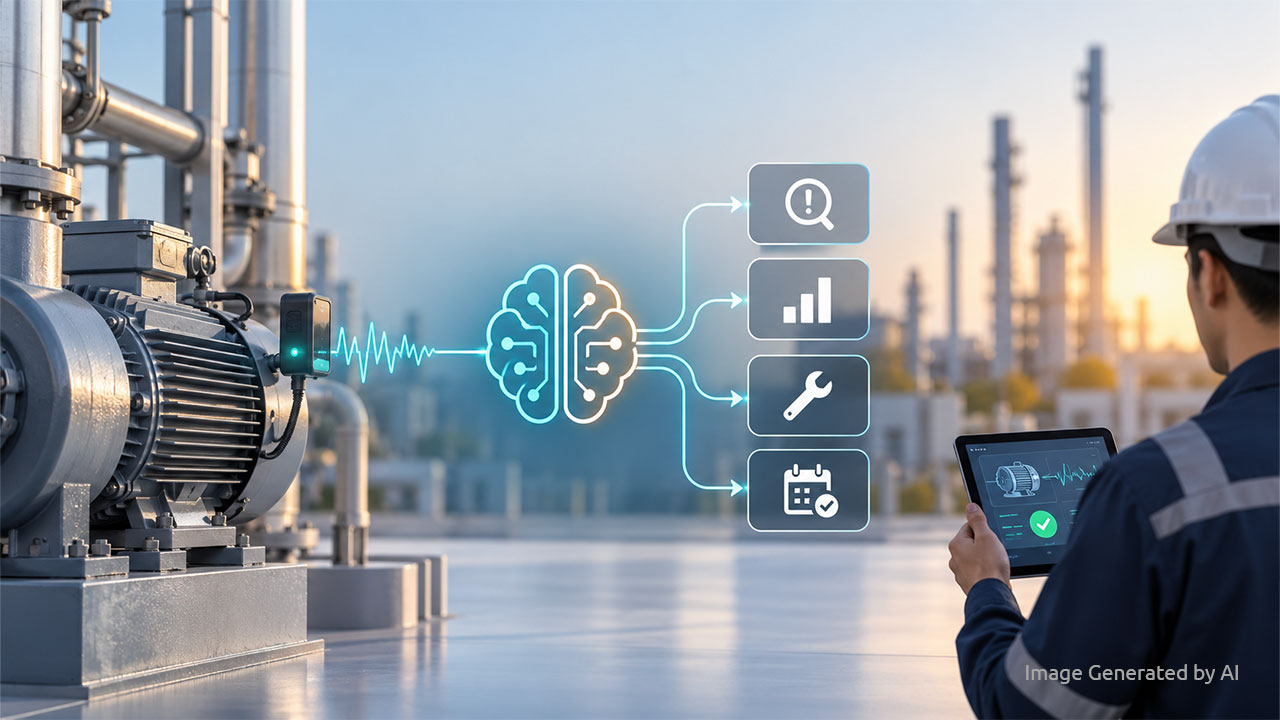 The article explores what manufacturing plants truly need to make prescriptive
AI effective, drawing on eight audience questions answered by experts from
Siemens and Infinite Uptime. A central theme is that most plants still
struggle with data quality and availability, yet waiting for perfect data
before deploying AI is unrealistic. The experts argue that physics‑informed
models, combined with targeted sensor retrofits, allow plants to start
generating reliable insights quickly, even in brownfield environments with
decades‑old equipment. They explain that prescriptive AI works best when
multiple sensing methods—such as vibration, thermal imaging, and machine
vision—are combined to capture different failure modes. The discussion also
breaks down how diagnosis should progress: anomaly detection first, then
classification, and finally linking those classifications to documentation and
automated “therapy” suggestions. Several questions focus on practical
economics, including when it’s cheaper to replace a part than predict its
failure and how much algorithm audits typically cost. The experts emphasize
building quantitative decision models rather than relying on rules of thumb.
The article closes by stressing data trust and security, noting that companies
must use controlled environments for LLMs and treat AI‑generated data with the
same rigor as physical products. The overall message is steady and pragmatic:
prescriptive AI succeeds when physics, data, and human judgment work
together.
The Clock Starts Before the Restore: Measuring Recovery Time and Data Recovery Capability
The article argues that organizations often measure disaster recovery
performance in a way that hides the real delays that occur before anyone
starts restoring systems. It opens with an anecdote from the 1970s, where a
team could technically recover from a failure in five minutes but took more
than thirty minutes to decide to act. The author explains that this gap still
exists today because most recovery tests measure only the restoration phase,
not the time spent detecting issues, triaging them, and making the decision to
declare an incident. To fix this, he introduces the idea of Recovery Time
Capability (RTC)—a single clock that starts at the first sign of trouble and
ends when the service is verified as working again. RTC breaks recovery into
six segments, each with its own time budget and owner, making it clear where
delays occur. He also defines Data Recovery Capability (DRC), which measures
how long it takes to make data whole and trusted, especially in “cold case”
scenarios where replicas are damaged and data must be restored from immutable
vaults. The article closes with practical steps: timestamp every segment, test
decision‑making with unannounced exercises, measure cold‑case recovery
annually, and report gaps clearly to the board. The message is steady and
pragmatic—real recoveries fail in the early minutes and the long data‑repair
hours, not in the scripted tests we usually run.
 The article highlights the hidden financial realities of enterprise artificial
intelligence projects when they transition from a pilot phase into full daily
production. During an audit of a celebrated document automation workflow, the
author uncovered a massive discrepancy between perceived success and actual
operational expenses. In the pilot phase, the system drastically reduced
turnaround times for vendor agreements, earning internal praise while a
central innovation fund quietly absorbed the computing costs. However, once
the project went live and expenses shifted to the departmental budget, a harsh
reality surfaced. Processing a single document surged to cost between twelve
and fourteen dollars in cloud consumption and model access fees, compared to
just eighty cents under the previous manual human workflow. This staggering
cost increase occurred because real world documents are often messy, featuring
handwritten notes, poor scans, and conflicting formatting. These
inconsistencies forced the automated pipeline to trigger multiple expensive
retrieval passes and secondary checks. Furthermore, roughly forty percent of
the documents required human intervention to fix errors, which ultimately
doubled the original manual processing time. Ultimately, falling base model
prices do not guarantee cheaper business processes, as complex workflows can
easily turn a predictable payroll expense into an unpredictable consumption
meter.
 The article explains how India is shaping “DPI 2.0,” the next phase of its
digital public infrastructure, by moving beyond identity and payments toward
sector‑wide digital systems built on open standards, user control, and
AI‑enabled services. It traces how DPI 1.0—Aadhaar, UPI, DigiLocker, and
Direct Benefit Transfer—created shared public rails that proved reliable at
national scale. DPI 2.0 extends this model into areas such as commerce through
ONDC, financial data through Account Aggregator, healthcare via ABDM, and
agriculture through AgriStack. A central theme is giving people more control
over their data, supported by the Digital Personal Data Protection Act, while
ensuring interoperability across ecosystems. The article highlights India’s
push to integrate AI into DPI so services can operate in local languages and
through voice, making them more inclusive. It also acknowledges past failures,
such as authentication errors, and notes that cybersecurity, algorithmic
accountability, offline access, and digital literacy are now core priorities.
Internationally, India promotes open protocols rather than proprietary
platforms, allowing countries like Indonesia to adapt the model to their own
needs. The piece closes by noting governance tensions at home, where DPI lacks
a clear legal definition, raising questions about safeguards for
population‑scale systems. Overall, DPI 2.0 is presented as an evolution
focused on trust, interoperability, and intelligent public services.
 Tony Timbol shares how building an AI-assisted application completely shifted
his perspective on software development. While attempting to convert a
cumbersome, spreadsheet-based agile assessment tool into a lightweight app
using an AI platform, his initial attempts failed. He realized the issue was
not the AI but his approach: he was treating the tool like a programmer rather
than a collaborator. When he shifted his focus from specifying coding details
to clearly defining outcomes, user journeys, and behaviors, the AI quickly
generated a functioning prototype. This experience taught Timbol that AI
accelerates the coding process but fundamentally relocates the challenging
parts of software engineering rather than eliminating them. While AI can write
code rapidly, it cannot handle crucial architectural choices, make strategic
compromises, manage system integrations like email notifications or
authentication, or understand genuine user needs. As execution becomes faster
and easier through AI, the true bottleneck shifts to human judgment and
product strategy. Timbol concludes that the future of software development
involves humans acting as product leaders who frame the right problems,
recognize sound architectural decisions, and provide the essential context
that machines lack to build secure and maintainable products.
I audited an award-winning AI project. The case study left out the cloud bill
The article highlights the hidden financial realities of enterprise artificial
intelligence projects when they transition from a pilot phase into full daily
production. During an audit of a celebrated document automation workflow, the
author uncovered a massive discrepancy between perceived success and actual
operational expenses. In the pilot phase, the system drastically reduced
turnaround times for vendor agreements, earning internal praise while a
central innovation fund quietly absorbed the computing costs. However, once
the project went live and expenses shifted to the departmental budget, a harsh
reality surfaced. Processing a single document surged to cost between twelve
and fourteen dollars in cloud consumption and model access fees, compared to
just eighty cents under the previous manual human workflow. This staggering
cost increase occurred because real world documents are often messy, featuring
handwritten notes, poor scans, and conflicting formatting. These
inconsistencies forced the automated pipeline to trigger multiple expensive
retrieval passes and secondary checks. Furthermore, roughly forty percent of
the documents required human intervention to fix errors, which ultimately
doubled the original manual processing time. Ultimately, falling base model
prices do not guarantee cheaper business processes, as complex workflows can
easily turn a predictable payroll expense into an unpredictable consumption
meter.
From digital insurance to intelligent insurance: Why AI is becoming the new operating layer
The article explains how AI is shifting insurance from a digital‑first model to an intelligent‑first one, where technology becomes part of the business rather than a support function. Sriram Naganathan of HDFC ERGO describes how underwriting, pricing, fraud detection, claims, and customer service are increasingly shaped by machine learning, generative AI, and agentic systems. The company’s digital foundation—where most policies and service interactions already happen online—has made it possible to layer intelligence on top of existing processes. Examples include GenAI tools that simplify policy explanations and AI‑guided motor claims assessments using smartphone photos. The piece stresses that AI should assist human decision‑making, not replace it, especially in high‑value or sensitive claims where context and empathy matter. It also highlights the shift from data scarcity to the challenge of converting large volumes of historical information into actionable intelligence. Governance, explainability, and trust emerge as essential themes as AI begins influencing pricing, underwriting, and fraud decisions. The article notes a move toward smaller, specialised models and internally built capabilities that embed institutional knowledge. It closes by arguing that the future is not autonomous insurance but augmented insurance—where AI reduces friction and improves accuracy while humans provide judgment, oversight, and empathy when it matters most.India is defining ‘DPI 2.0’ as it shifts beyond identity and payments
The article explains how India is shaping “DPI 2.0,” the next phase of its
digital public infrastructure, by moving beyond identity and payments toward
sector‑wide digital systems built on open standards, user control, and
AI‑enabled services. It traces how DPI 1.0—Aadhaar, UPI, DigiLocker, and
Direct Benefit Transfer—created shared public rails that proved reliable at
national scale. DPI 2.0 extends this model into areas such as commerce through
ONDC, financial data through Account Aggregator, healthcare via ABDM, and
agriculture through AgriStack. A central theme is giving people more control
over their data, supported by the Digital Personal Data Protection Act, while
ensuring interoperability across ecosystems. The article highlights India’s
push to integrate AI into DPI so services can operate in local languages and
through voice, making them more inclusive. It also acknowledges past failures,
such as authentication errors, and notes that cybersecurity, algorithmic
accountability, offline access, and digital literacy are now core priorities.
Internationally, India promotes open protocols rather than proprietary
platforms, allowing countries like Indonesia to adapt the model to their own
needs. The piece closes by noting governance tensions at home, where DPI lacks
a clear legal definition, raising questions about safeguards for
population‑scale systems. Overall, DPI 2.0 is presented as an evolution
focused on trust, interoperability, and intelligent public services.
How to Turn Data Governance into a Decision System
Data governance programs often focus exclusively on managing the data itself, prioritizing tasks like documenting definitions, mapping lineage, and improving quality scores. However, treating data as an isolated asset misses its true purpose, which is enabling better organizational choices. To maximize value, organizations must transition from merely governing data to actively governing the conditions that make data driven decisions trustworthy. This involves bridging two distinct value chains. The standard path from data to wisdom drives operational and strategic business choices, while a parallel path from metadata to wisdom provides the necessary context to trust those choices. By focusing on critical, high impact decisions rather than generic data inventories, organizations can completely reverse their traditional governance logic. Instead of finding uses for available data, teams identify the essential decisions they need to protect and then work backward to determine the specific data, rules, and controls required. Consequently, priority is determined by business impact rather than abstract maturity scores. Fixing a missing definition or uncontrolled transformation matters because it directly protects a regulatory outcome or commercial offer. Ultimately, this approach transforms data governance from a routine compliance exercise into a robust decision system, giving business leaders the concrete evidence they need to act with absolute clarity and reliability.AI changed my role before it changed my software
Tony Timbol shares how building an AI-assisted application completely shifted
his perspective on software development. While attempting to convert a
cumbersome, spreadsheet-based agile assessment tool into a lightweight app
using an AI platform, his initial attempts failed. He realized the issue was
not the AI but his approach: he was treating the tool like a programmer rather
than a collaborator. When he shifted his focus from specifying coding details
to clearly defining outcomes, user journeys, and behaviors, the AI quickly
generated a functioning prototype. This experience taught Timbol that AI
accelerates the coding process but fundamentally relocates the challenging
parts of software engineering rather than eliminating them. While AI can write
code rapidly, it cannot handle crucial architectural choices, make strategic
compromises, manage system integrations like email notifications or
authentication, or understand genuine user needs. As execution becomes faster
and easier through AI, the true bottleneck shifts to human judgment and
product strategy. Timbol concludes that the future of software development
involves humans acting as product leaders who frame the right problems,
recognize sound architectural decisions, and provide the essential context
that machines lack to build secure and maintainable products.

