Showing posts with label infrastructure. Show all posts

Daily Tech Digest - October 27, 2026

Quote for the Day
“We are no longer securing computers—we are securing society.”
— Mikko Hyppönen
Audio Edition — Listen to Today’s Digest
Narrated version of the Daily Tech Digest
Article Thumbnail

Cutting both ways: AI sharpens systems protection while opening new exploits for malicious actors

The recent article highlights the dual role of artificial intelligence in modern cybersecurity. While organizations use advanced AI models to quickly spot vulnerabilities in their source code, malicious actors are leveraging those exact same tools to exploit weaknesses faster than ever before. Because these highly sophisticated attacks often strike without warning, industry experts emphasize that standard defenses are no longer enough. Instead, the focus has shifted toward building true cyber resilience. This approach requires companies to maintain a strong recovery posture focused on deep data integrity, ensuring they can quickly restore clean, uncompromised information after an inevitable breach occurs. Furthermore, as emerging threats like post-quantum computing begin to surface, businesses face the urgent task of upgrading their foundational encryption and infrastructure layers. Ultimately, securing enterprise environments now demands continuous backup validation, reliable data pipelines, and a fundamental shift from treating security as an optional add-on to making it a core, inseparable part of every digital operation.

Read Original Article →

Communications Infrastructure Is Now A Security Issue

Enterprise communications platforms are no longer just background IT systems; they have become a critical part of mission assurance and core security infrastructure. Historically viewed simply as tools for routing calls and connecting people, these systems now support essential, regulated workflows and incident response efforts. When they fail, the disruption quickly ripples out to affect business continuity, impacting customers and employees alike. Consequently, modernization efforts, such as moving to the cloud or integrating artificial intelligence, must prioritize reliability and resilience over mere capability upgrades. Moving a vulnerable system to the cloud does not automatically make it secure; resilience must be built into the architecture from the start. AI, while powerful, introduces new risks that require the same strict access controls and oversight applied to privileged human users. Security leaders must identify critical communication workflows, define concrete resilience requirements, and regularly test against realistic failure scenarios in their tabletop exercises. Ultimately, modernizing communications should never compromise the systems a business depends on to survive a crisis.

Read Original Article →
Article Thumbnail

Does Your Manufacturing Data Deserve Your Trust?

Manufacturers today collect vast amounts of information from their production lines, but many struggle with a fundamental problem: they cannot trust their own data. As operations expand and new equipment is added, inconsistencies naturally develop across different systems. When teams see conflicting numbers for the same metric, discussions shift away from solving actual production issues and instead focus on figuring out which report is accurate. This lack of reliability slows down decision-making and drains operational confidence. Simply gathering more information is not the answer and often just creates additional noise. To make effective decisions, companies need data that is accurate, consistent, and easy to access across the entire organization. This reliable foundation is especially critical before investing in advanced technologies like artificial intelligence or predictive maintenance, which rely entirely on the quality of the information they process. Ultimately, the goal is not to hoard more statistics, but to build a dependable system where teams can confidently use the information they already have to improve their daily operations.

Read Original Article →
Article Thumbnail

A free open-source backup app that makes traditional backups feel outdated

The article describes how Kopia, a free open‑source backup tool, makes traditional backup methods feel outdated by focusing on snapshots and efficiency rather than repeated full copies. The author explains that most backup tools still follow the old pattern of selecting files, choosing a destination, and hoping the process works — often with key features locked behind paid subscriptions. Kopia stood out because it is flexible, doesn’t require an account, and supports Windows, macOS, and Linux through a simple graphical interface. After creating an encrypted repository, users can start with a basic setup and explore advanced options later. The real improvement comes from Kopia’s snapshot‑based design: instead of copying everything each time, it saves only new or changed data, making backups faster and less wasteful. Built‑in deduplication further reduces storage use by avoiding duplicate data. The article’s steady message is that Kopia offers a more modern, efficient, and transparent way to back up files without the complexity or cost of traditional tools.

Read Original Article →
Article Thumbnail

Choosing a Custom Business Software Development Company: A Testing and Quality Evaluation Framework

Selecting the right custom software development company requires looking past polished sales pitches and headline prices to evaluate factors that actually predict a project's success. Before speaking with vendors, clearly define your business problem, measurable success metrics, and absolute constraints. This clarity ensures you receive proposals based on your reality rather than vendor assumptions. When evaluating candidates, assess them across six key dimensions: their grasp of your underlying business goals, specific experience solving similar problems, their actual delivery process, the exact team members assigned to your project, the quality and maintainability of their code, and the alignment of their commercial terms with your risk tolerance. Watch out for red flags like detailed quotes provided without any discovery work or a reluctance to introduce the technical lead. To minimize risk, consider starting with a paid discovery phase. This small initial engagement allows you to test the working relationship, refine the project scope, and ensure your chosen vendor truly aligns with your objectives before committing to a major investment.

Read Original Article →
Article Thumbnail

What EvilTokens teaches us about defending against AI-assisted attacks

Artificial intelligence is changing the pace of cyberattacks, as demonstrated by a recent phishing tool called EvilTokens. Rather than stealing passwords, EvilTokens tricks users into granting access to their Microsoft accounts. Once inside, the tool uses AI to quickly figure out who handles payments, identify trusted business relationships, and write convincing fake emails. This automation speeds up the time it takes an attacker to move from initial access to actual harm. Because AI removes the usual hurdles that slow attackers down, traditional security measures based on average detection and response times are no longer enough. Even a fast response might be too late if the attacker can accomplish their goals in minutes. To defend against these faster threats, organizations need to test their entire security setup as a connected system, not just check individual tools in isolation. By understanding exactly how an attacker might move through their network, security teams can proactively close gaps and stop these automated threats before they cause lasting damage.

Read Original Article →
Article Thumbnail

Between alerts: What Attackers Do in the Spaces Ordinary Detection Misses

Modern cyber attackers are increasingly using artificial intelligence to move quickly, but they still rely on stealth to evade detection. To stay hidden, they operate in the quiet spaces between security alerts, dragging out their operations and hiding within standard administrative tools like DNS queries or SMB connections. Because these individual actions look like ordinary business operations, security teams and siloed tools often miss them. An attacker might spend days or weeks slowly gathering credentials or mapping systems without triggering a high-priority alarm. To catch these subtle intrusions, Security Operations Centers (SOCs) need network detection and response (NDR) platforms that capture detailed network evidence over time. Instead of just looking at isolated alerts, NDR provides the necessary context to connect distinct events into a clear timeline. By applying AI to this comprehensive network data, defense teams can quickly identify hidden relationships across hosts and protocols. This approach allows analysts to spot the broader progression of an attack and make smarter risk decisions, rather than getting overwhelmed by thousands of disconnected alerts.

Read Original Article →
Article Thumbnail

How to make enterprise APIs agent-ready

As large organizations integrate AI agents into their workflows, they face a major hurdle: connecting these agents to thousands of internal APIs. The standard approach of mapping every single API operation to a separate tool quickly breaks down. It creates high costs from excessive token usage, slows down response times, and confuses the AI, leading to poor accuracy. To solve this, technical teams are shifting to a method known as "code mode." Instead of overwhelming the agent with a massive list of individual tools, this approach provides a single, streamlined interface. The agent then writes and executes short code snippets to find exactly what it needs. This keeps the data load small and efficient. Just as importantly, organizations must route these agent requests through their existing API gateways. Doing so ensures that the agents follow the same security, authentication, and access rules as any other user. By treating AI agents as standard clients, companies can safely grant them access to essential systems without losing control or slowing down performance.

Read Original Article →
Article Thumbnail

CIOs rethink roles, skills, training, and talent models for the future

As technology rapidly changes how organizations operate, IT leaders are actively redesigning their teams, roles, and training methods to prepare for the future. With artificial intelligence taking over many routine coding and manual tasks, the traditional emphasis on deep, specialized technical skills is steadily shifting. Instead, companies increasingly value broad problem-solving abilities, strong communication, and a clear understanding of the business itself. IT professionals will need to focus less on simply building software and more on carefully deciding whether a project truly adds value before starting it. To keep up with this fast pace, long-term training programs are giving way to short, continuous lessons that happen directly on the job. Job roles are also becoming more flexible, with staff acting as general engineers who can move smoothly between different areas like networking and databases as needs arise. Ultimately, building a workforce that can quickly adapt, learn, and apply new tools to practical challenges is becoming the most reliable way to navigate an unpredictable technological landscape.

Read Original Article →
Article Thumbnail

IT and security leaders of the AI era must go back to basics and beware the hype

As artificial intelligence rapidly evolves, IT and security leaders must avoid getting distracted by the hype and instead focus on foundational security principles. While modern AI tools are powerful and can expose new vulnerabilities or discover system weaknesses faster than ever, the core issue remains poor identity management. Hackers and AI agents alike exploit basic failures, such as unrevoked access, forgotten credentials, and over-privileged accounts. When organizations adopt AI, they often deploy agents with broad permissions and unclear oversight, mirroring the mistakes made during the early days of cloud computing. To protect their systems, companies do not need entirely new security frameworks; they need to rigorously apply established practices. This means enforcing least privilege, ensuring just-in-time access, and maintaining strict oversight of both human and non-human identities. By mastering these basic controls and clearly assigning responsibility for entitlement governance, organizations can safely navigate the current wave of technological change without leaving their digital doors unlocked.

Read Original Article →

Daily Tech Digest - October 25, 2026

Quote for the Day
“The only way to win is to learn faster than anyone else.”
— Eric Ries
Audio Edition — Listen to Today’s Digest
Narrated version of the Daily Tech Digest
Article Thumbnail

Core Concepts in Infrastructure Cost Management

The article revisits how organizations should think about infrastructure cost management by comparing on‑premise and cloud deployment patterns. It notes that a decade ago, cloud was widely seen as the inevitable future, but recent shifts show that on‑premise environments still offer advantages worth reconsidering. On‑premise setups involve not just servers but the full physical ecosystem — racks, networking gear, cooling, power, and security — all of which carry long‑term financial and operational implications. The piece explains that while on‑premise environments are often labeled inflexible, they can be surprisingly adaptable when paired with modern automation frameworks. The real challenges lie in hardware lifespan decisions, sizing development and QA environments, managing shared analytic workloads, and maintaining disaster‑recovery sites that are costly to keep idle. These factors shape both capital and operational expenses over many years. The article’s steady message is that cost management requires understanding the trade‑offs between flexibility, predictability, and long‑term commitments, and that both cloud and on‑premise models have strengths that deserve thoughtful evaluation rather than assumptions.

Read Original Article →

Container Security Checklist for CI/CD Pipelines: 30 Checks From Commit to Runtime

This article presents a practical security checklist containing 30 checks for container images as they move through continuous integration and deployment pipelines. The core message is that actual security comes from enforcing rules, not just listing best practices. The checks span eight stages, from the initial code commit to runtime monitoring. In the early stages, teams should build minimal images, remove all secrets, and lock down third-party actions. Later stages focus on vulnerability scanning that blocks risky deployments, generating software bills of materials, and digitally signing images to guarantee they came from a trusted build. At deployment, admission controllers must verify signatures and restrict permissions so images cannot run with root access or modify the underlying host. Because the pipeline itself is a high-privilege system that can be compromised, securing the build process is just as important as securing the image. Implementing these checks incrementally—starting with basic Dockerfile hygiene—prevents common mistakes and ensures a cleaner, safer production environment.

Read Original Article →
Article Thumbnail

Cloud repatriation: What CISOs need to know

The article explains that cloud repatriation is becoming a practical concern for CISOs, not because enterprises are abandoning the cloud, but because many workloads no longer fit the cloud‑first assumptions of the past decade. Surveys show that while 86% of CIOs plan to move at least some workloads back on‑premises, only about 8–9% intend a full exit, meaning most organizations are simply recalibrating workload placement rather than rejecting cloud altogether. Cost discipline is a major driver, with private cloud often delivering 40–50% lower total cost of ownership for steady‑state workloads. Compliance, data‑gravity issues, and high‑intensity AI workloads also push certain systems back into controlled environments. The article stresses that hybrid infrastructure is becoming the long‑term norm, where each workload “earns” its placement based on economics, performance, and risk. For CISOs, this shift introduces new responsibilities: reassessing threat models, ensuring consistent controls across mixed environments, and preparing for operational risks tied to vendor concentration and geopolitical disruptions. The message is steady — repatriation is about precision, not retreat, and CISOs must adapt security strategies accordingly.

Read Original Article →

The Cybersecurity Reality Check: Ten Myths That Matter

The article challenges ten common assumptions that often mislead leaders about cybersecurity and explains why these misconceptions create real risk. It notes that serious incidents rarely stem from exotic technical failures; instead, they usually begin with flawed beliefs about who attackers target, where responsibility sits, or what “adequate protection” really means. One myth is that small organizations are too insignificant to attract attention, but attackers typically exploit exposed systems using automated tools, making size irrelevant. Smaller firms may even be more vulnerable because they have fewer security resources and weaker monitoring. Another misconception is that cybersecurity is purely an IT function, when governance and accountability actually rest with leadership. The article stresses that regulatory scrutiny in the UK and EU has intensified, and breaches can quickly lead to investigations, litigation, business interruption, and reputational harm. Ultimately, the piece argues that organizations must be able to justify their security measures as proportionate to their risks and abandon assumptions that no longer match today’s threat landscape.

Read Original Article →
Article Thumbnail

When Trust Fails: What the eMudhra Certificate Incident and PHP Vulnerabilities Teach Us About Zero Trust Security

In October 2026, two distinct cybersecurity events—a certificate failure by eMudhra and critical remote code execution flaws in PHP—highlighted a fundamental lesson for software engineers: trust must be constantly verified. The eMudhra incident involved weak intermediate cryptographic keys generated by a flawed process. Even though eMudhra itself was not hacked, the incident proved that secure connections rely on trustworthy underlying processes, not just a padlock icon. Meanwhile, the PHP vulnerabilities demonstrated that securing an application requires patching the entire software stack, not just the core code, because a vulnerable runtime can serve as an easy entry point. Together, these events show why modern systems must move away from assuming that any internal network or familiar request is automatically safe. Instead, engineers should adopt a strict verification approach. This means validating identity, authorization, and context at every boundary, properly handling access tokens, and protecting communication between internal services. Ultimately, security is an ongoing engineering process of continuous verification rather than a single static feature or one-time setup.

Read Original Article →

What OT detection actually reveals

Securing operational technology (OT) environments requires a fundamentally different approach than standard IT security. While conventional IT tools excel at spotting network anomalies, they lack the critical physical process context needed to recognize when otherwise legitimate industrial commands are used for malicious disruption. OT detection platforms solve this by combining industrial protocol awareness with a deep understanding of normal operational behavior and physical constraints. A solid asset inventory is the foundational first step. From there, effective OT security relies on five core capabilities: monitoring industrial protocol anomalies, establishing strict baselines for process behavior, tracking engineering workstation activity, closely managing remote vendor access, and correlating traffic across the IT/OT boundary. Because OT involves physical processes where any disruption can impact safety, detection must be paired with structured, pre-planned response strategies. Automated actions are generally safe only at the IT or DMZ layers. Any direct intervention touching physical plant controllers requires clear authorization from operations teams to ensure production environments remain safe and stable.

Read Original Article →
Article Thumbnail

AI accelerates path from IT compromise to OT targeting

The article explains that AI is accelerating the path from IT compromise to OT targeting, making industrial environments more exposed than before. Attackers can now use AI to quickly analyze stolen IT data, map relationships, and identify the most valuable operational assets to target. This shortens the traditional gap between breaching corporate networks and moving into industrial systems. The piece notes that modern OT environments are increasingly connected to cloud services, remote access tools, and SaaS platforms, creating more entry points and making it harder to maintain clear separation between IT and OT. AI also helps attackers craft more convincing phishing messages, automate reconnaissance, and generate malware tailored to specific environments. At the same time, defenders struggle with legacy systems, inconsistent visibility, and slow patch cycles. The article argues that organizations must rethink OT security by improving asset inventories, tightening identity controls, and preparing for faster, more automated attack chains. Its message is steady: AI has changed the tempo of intrusions, and OT security must adapt to match that speed.

Read Original Article →

The next manufacturing cyber threat is manipulation of AI-driven decisions

As manufacturing becomes increasingly connected, the nature of cybersecurity threats is shifting. According to Pradipta Patro, Chief Information Security Officer at Polycab India Limited, the next major risk isn't just about keeping hackers out of the network. It is about protecting the artificial intelligence systems that influence critical operational decisions. If an attacker manipulates the data feeding an AI model, the system could make unsafe or faulty decisions without triggering traditional alarms. This goes beyond compromised information, directly threatening production quality, equipment reliability, and even worker safety on the factory floor. To address this, security must be built into factories from the ground up rather than added later as an afterthought. Manufacturers need complete visibility into all connected devices, strong network boundaries between IT and operations, and meaningful human oversight of AI decisions. Ultimately, cyber resilience must be treated as a core business continuity issue. The most successful factories will be those that can fully trust their automated systems because they secured the underlying data first.

Read Original Article →
Article Thumbnail

Digital twins in oil and gas: from simulation to real-time optimisation

Digital twins in the oil and gas sector are evolving from isolated engineering studies into practical tools that drive daily operations. Historically, creating a digital twin took months and became outdated as soon as the physical equipment changed. Today, advanced models can be built quickly, update automatically alongside physical wear, and connect across entire systems. A key shift is the use of physics-based modeling rather than just relying on historical data. Purely statistical models struggle when equipment faces new or unobserved conditions. By grounding the software in the actual laws of fluid dynamics and heat transfer, operators receive reliable, real-time recommendations they can trust. This approach accounts for uncertainty, allowing teams to optimize active equipment and reduce waste like methane flaring by safely pushing production closer to its true limits. Solving the challenge of scaling these tools in energy operations also opens the door for similar efficiency gains in other complex, high-demand environments, such as data centers and power grids.

Read Original Article →
Article Thumbnail

Data Sovereignty is Becoming a Design Principle for Enterprise AI

In the past, data sovereignty simply meant knowing the physical location of your company’s servers to meet regional laws. Today, artificial intelligence has fundamentally changed this. Because data now constantly flows through various external applications, language models, and processing tools, maintaining control over it has become much more complex. Instead of trying to lock down an entire organization, companies should focus on individual tasks. For example, processing public marketing information requires far less strict control than handling sensitive medical records. A major challenge is ensuring that safety rules follow the information wherever it goes. When original records are transformed into formats that AI can read, those new formats must inherit the same restrictions. Tracking this movement requires strong underlying data tagging. To manage this effectively, businesses should view sovereignty as a flexible budget. They must calmly weigh the need for strict control against the benefits of using advanced, external technology. Ultimately, building a flexible setup allows teams to continuously adjust their safety measures as rules and technology evolve.

Read Original Article →

Daily Tech Digest - October 22, 2026

Quote for the Day
“Debugging is twice as hard as writing the code in the first place.”
— Brian Kernighan
Audio Edition — Listen to Today’s Digest
Narrated version of the Daily Tech Digest
Article Thumbnail

14 ways attackers abuse cloud services to hack your enterprise

As enterprises migrate to hybrid and cloud environments, cyberattackers are evolving from "living off the land" to "living off the cloud," blending malicious activities into legitimate business traffic. Instead of relying on traditional malware that triggers alarms, adversaries are increasingly abusing trusted APIs, native administrative tools, and SaaS platforms to bypass conventional defenses. Attackers route command-and-control communications through reputable services like OpenAI, Microsoft Graph API, and Google Sheets, making the traffic look like routine developer or employee activity. They also exploit cloud identities, such as OAuth tokens and service accounts, to move laterally and access sensitive data without needing to compromise local servers directly. Further tactics include staging malware in object storage buckets, exfiltrating data via everyday tools like Slack, abusing ephemeral serverless functions to mask reconnaissance scans, and weaponizing identity tenant relationships. By exploiting the inherent trust and API-driven nature of modern cloud architecture, these cloud-native attack chains effectively turn the enterprise's operational backbone into a highly evasive attack surface.

Read Original Article →
Article Thumbnail

From Microservices to Agents: the Next Evolution of Distributed Systems

The shift toward artificial intelligence agents marks a significant evolution in software architecture, moving away from traditional microservices. While microservices focused on breaking down complex applications into smaller, predictable parts with clear ownership boundaries, agentic systems focus on distributing decision-making. Instead of following pre-programmed, step-by-step logic, these new AI agents determine their actions dynamically. They analyze the context and their goals in real-time to decide which tools to use and how to sequence their reasoning. This means execution paths are no longer entirely determined during the design phase but adapt as the system runs. While this makes systems more capable of handling complex or vague situations, it introduces new challenges in reliability. The quality of a system's decisions becomes just as critical as its speed or availability. When these systems fail, they often suffer from silent drops in reasoning quality rather than crashing entirely. To manage this effectively, systems need built-in boundaries for the agents, continuous evaluation loops, and reliable fallback mechanisms.

Read Original Article →
Article Thumbnail

How hybrid infrastructure is making quantum commercially actionable today

The quantum computing industry is currently in a critical "prepare for quantum" phase. While fault-tolerant quantum hardware is still developing, organizations cannot afford to wait passively. Integrating geographically isolated quantum processors with enterprise IT through secure, low-latency interconnection is an infrastructure challenge that must be addressed today. This preparation is essential for sectors like life sciences, where delays in drug discovery can be incredibly costly. A prime example is Qubit Pharmaceuticals, which utilizes a hybrid approach with its ATLAS platform. This four-layer system combines high-fidelity physics simulations, a synthetic quantum chemistry data engine, a specialized AI foundation model, and an emulator that simulates up to 40 qubits on classical hardware. By leveraging secure interconnection fabrics provided by partners like Equinix, companies can seamlessly link classical computing, HPC, AI, and early quantum capabilities. Building this hybrid infrastructure now allows organizations to experiment, gain operational familiarity, and seamlessly scale their capabilities as quantum hardware matures, ensuring they are ready to harness quantum utility when it arrives.

Read Original Article →

What Recent Cybersecurity Incidents Teach About the Duty to Mitigate Vendor and Service-Provider Risk

Recent cybersecurity incidents demonstrate that organizations face immense risks from third-party vendors and service providers, shifting the focus from internal defenses to external supply chains. Regulatory bodies increasingly expect companies to maintain a strict duty of vendor oversight, meaning organizations cannot simply outsource accountability for data protection. Real-world examples highlight this shift. The MOVEit software breach showed that companies can face severe legal and financial consequences from a vendor's vulnerability, regardless of their own internal controls. The Change Healthcare attack emphasized operational dependency risk, illustrating the disaster that occurs when a critical vendor goes offline. Furthermore, the PowerSchool lawsuit revealed that oversight must extend to subcontractors who have system access. To mitigate these threats, businesses must integrate vendor oversight into their core governance structure. This requires conducting thorough initial evaluations, negotiating clear contractual protections for incident response, and continuously monitoring vendor security practices. Treating vendor management as an ongoing legal and operational responsibility is essential for maintaining resilience when external failures cause major internal disruptions.

Read Original Article →
Article Thumbnail

The CIO’s new recovery problem: Knowing what ‘good’ looks like

Disaster recovery used to focus primarily on how quickly a business could restore its systems and resume normal operations. Today, modern technology environments are far more complex, spanning cloud platforms, software-as-a-service applications, and constantly changing identities. This complexity sprawl presents a new challenge for technology leaders: figuring out what a healthy system actually looks like before attempting to restore it. Simply bringing a system back online is no longer enough if you cannot guarantee it is secure and trustworthy. To build true resilience, organizations must maintain an accurate inventory and clear dependency mapping while the environment is still functioning properly. Testing a recovery plan must also evolve beyond verifying backups. It should evaluate whether the team can make critical decisions under pressure, understand shifting dependencies, and confirm that the restored environment is safe to use. While speed remains a priority during a crisis, restoring systems without confidence introduces severe risk. Technology leaders must establish a clear definition of a trusted state before an incident ever occurs.

Read Original Article →
Article Thumbnail

When Business Continuity Plans Depend on One Person Knowing What to Do

Even when business continuity plans are well-documented and regularly tested, they often contain a hidden vulnerability: relying too heavily on specific individuals. While organizations meticulously map out system and supply chain dependencies, they frequently overlook personnel dependencies. This reliance becomes clear during a crisis when teams instinctively turn to a single experienced manager, technical expert, or executive rather than following established procedures. The article suggests a straightforward way to expose this weakness during recovery exercises: deliberately remove key personnel from the scenario. If progress halts, deputies hesitate to make decisions, or critical workarounds suddenly become unavailable, the organization has identified a dangerous point of failure. These exercises often reveal that designated alternates lack the practical authority or historical knowledge to step in effectively when the primary decision-maker is absent. Recognizing these human dependencies allows organizations to correct them before a real emergency by formally documenting vital workarounds, transferring knowledge, and granting alternates the real authority they need to lead under pressure.

Read Original Article →
Article Thumbnail

Can AI stop good candidates from getting lost in the hiring pile?

Artificial intelligence is shifting from a basic background tool into an active partner for recruitment teams. As hiring volumes grow, qualified applicants are frequently overlooked simply because recruiters lack the time to review everyone. To solve this, companies are using artificial intelligence voice agents to handle the initial stages of screening. These agents can conduct first-round interviews at any time, answer standard questions about the role, and generate structured reports for the hiring team. This approach eliminates long waiting periods for applicants and ensures every application receives attention. However, technology cannot replace the core of recruitment. While artificial intelligence excels at repeatable tasks and gathering information, the final decision must remain human. Assessing an individual's motivations, understanding how they think, and building a genuine connection require human judgment. Furthermore, companies must be fully transparent when using these tools. Candidates need to know they are speaking with software, not a person. When applied responsibly, this technology prevents strong applicants from falling through the cracks while preserving the vital human element of hiring.

Read Original Article →

Gartner’s top tech trends for 2027 expand—and constrain—AI capabilities

Gartner recently outlined ten strategic technology trends for 2027, focusing on expanding artificial intelligence capabilities while establishing stricter controls. Over the next few years, businesses will move beyond text-based models toward systems designed for complex math, continuous voice reasoning, and physical world simulation for robotics. As these systems produce output faster than humans can review, the second phase emphasizes necessary limits. Organizations will need dedicated frameworks to manage machine identities, verify coding output, and provide specific business context to prevent rogue actions or compliance failures. Automated security patching will also become essential to close vulnerabilities quickly. Finally, looking further ahead, companies will aim to reduce reliance on specific cloud providers by adopting easily replaceable applications and independent technologies. A notable long-term shift involves biological computing, where lab-grown organic systems could eventually handle complex data tasks using far less energy than traditional silicon hardware. By planning across these three horizons, technology leaders can balance autonomous capabilities with the security required for steady operations.

Read Original Article →
Article Thumbnail

Coding Agents Moved the Bottleneck From Writing to Reviewing PRs

Artificial intelligence coding agents have significantly accelerated software development, but they have also shifted the primary bottleneck from writing code to reviewing it. Because these agents generate larger and more frequent pull requests, the volume of code needing review has outpaced the capacity of human engineers. This growing queue of unreviewed work often remains hidden because traditional productivity metrics focus on generation speed rather than review efficiency. Consequently, development teams face mounting quality debt. Overwhelmed reviewers might miss architectural flaws or security vulnerabilities, especially since AI-generated code typically looks clean and passes basic tests. To address this, organizations must recognize that hiring more reviewers is not a sustainable solution. Instead, they should implement dedicated AI review agents designed specifically to catch errors rather than generate new code. Additionally, capping the size of pull requests and tracking review metrics—such as wait times and review depth—can help maintain software quality without sacrificing the speed gained from AI development tools.

Read Original Article →
Article Thumbnail

Where Should a Transaction End? Designing Consistency Boundaries in Distributed Java Systems

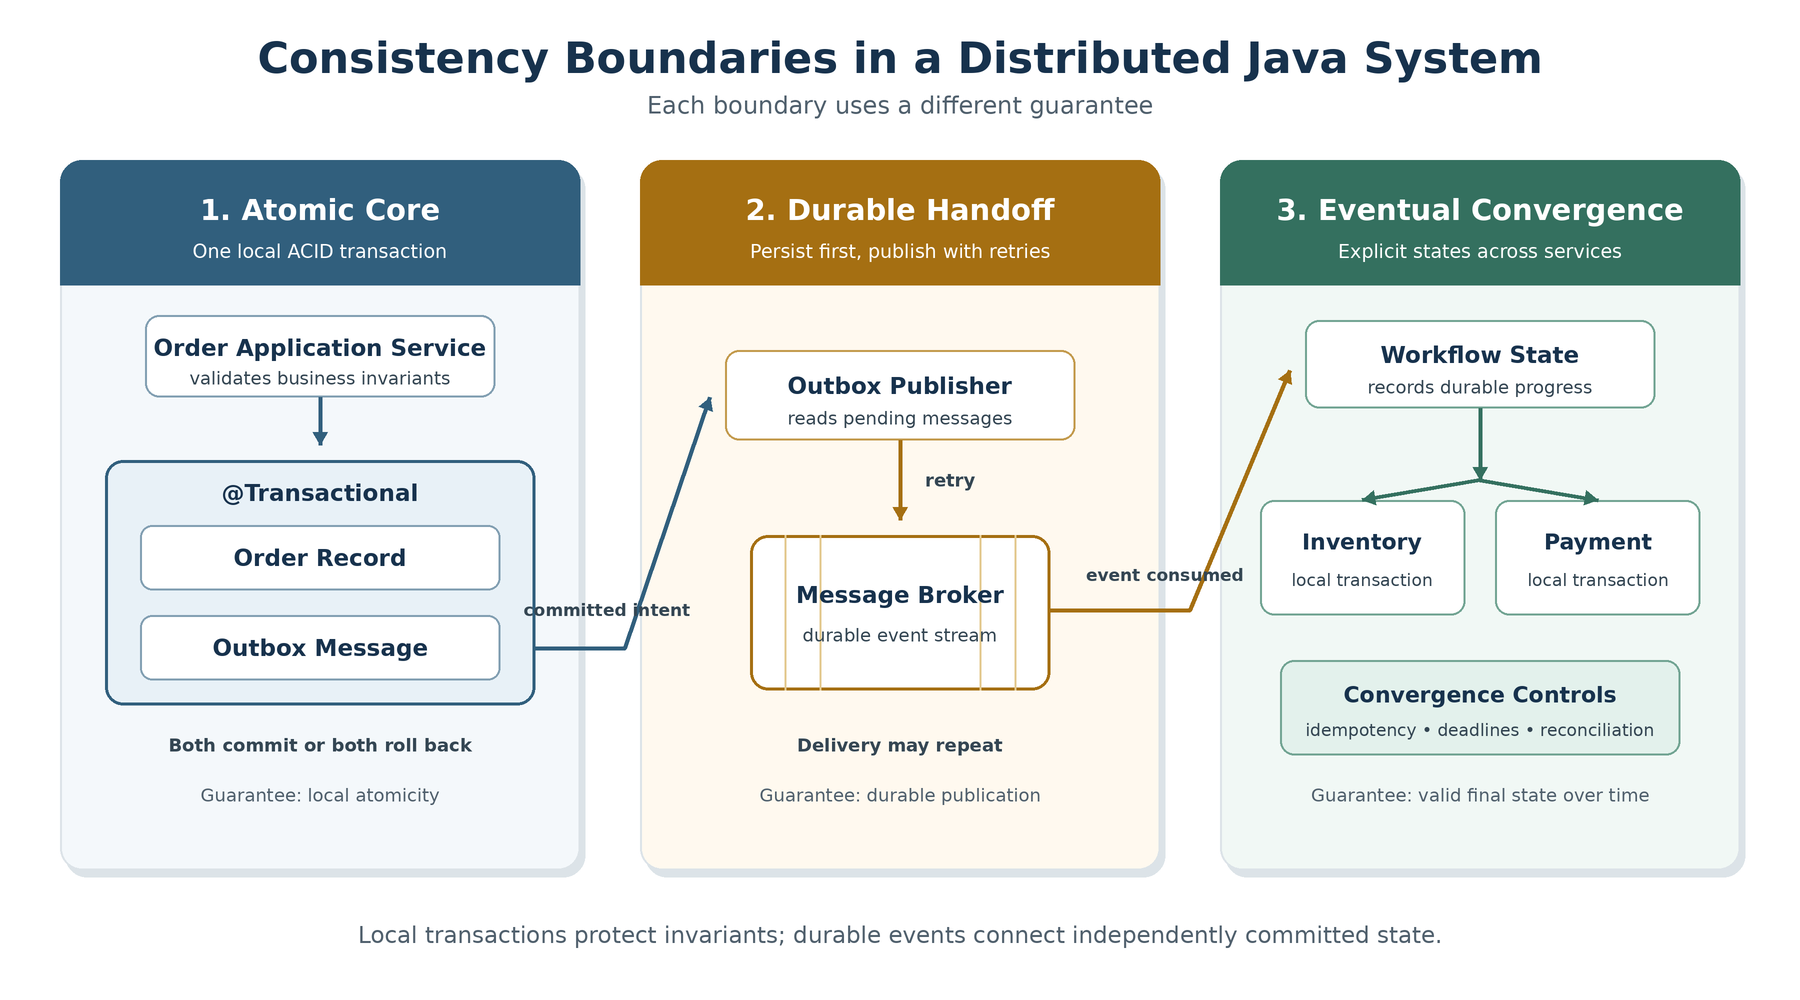
Designing distributed systems forces architects to decide exactly where a transaction begins and ends. Rather than splitting services first and worrying about data consistency later, the best approach starts with defining business invariants. These are the core rules that must always remain true together. The architecture should wrap its boundaries around these facts. When multiple pieces of data must change simultaneously to keep a rule intact, they belong in a single local transaction. Once that core state is secure, the system can use a durable handoff, like an outbox pattern, to safely communicate changes to other components. From there, eventual consistency can manage the broader workflow, but it must be an explicit process with clear recovery paths, not just a vague delay. Relying on synchronous call chains often creates hidden points of failure, so workflows should be modeled as durable states that can survive a crash. Ultimately, separating databases or breaking apart services is only valuable if it respects the underlying business rules that keep the entire system correct.

Read Original Article →

Daily Tech Digest - October 04, 2026


Quote for the day:

“The more you loose yourself in something bigger than yourself, the more energy you will have.” -- Norman Vincent Peale

🎧 Listen to the audio debrief on YouTube

▶ Play Audio Digest

Duration: 22 mins • Perfect for listening on the go.


Why the hardest AI skills to learn might be the human ones

The article explores why the most challenging AI‑related skills today are not technical ones but human ones, a theme highlighted at a London roundtable discussing Coursera and Udemy’s joint Global Skills Report. The report shows that while countries are rapidly adopting AI, the ability to pair technical capability with judgment, curiosity, and critical thinking is lagging. Speakers from Oxford, DeepMind, Imperial College, and the two learning platforms shared stories illustrating how good questions, thoughtful collaboration, and basic statistical reasoning often matter more than access to powerful models. They noted that organizations are adopting AI faster than they are preparing people to use it responsibly, and that learners worldwide are increasingly seeking skills like critical thinking, complex problem‑solving, and ethics. The piece also describes emerging efforts to use AI to help people practice human skills, such as role‑play simulations and task‑based micro‑credentials. Yet several participants stressed that knowing when not to use AI is just as important. A story about a team choosing pen and paper over automation underscores this point. The article closes by suggesting that as AI accelerates routine tasks, the ability to pause, question, and learn from one another may become the most valuable skill of all.


Rethinking automotive cyber risk for the age of accelerated vulnerability discovery

Automotive security used to focus mainly on preventing physical tampering. Today, however, the rise of connected vehicles requires a completely different approach. Modern cars depend on cloud platforms, mobile apps, over-the-air updates, and software from various third-party suppliers, meaning a single flaw can now compromise entire fleets rather than just one vehicle. Recent analysis shows a sharp thirty percent increase in new automotive vulnerabilities, with high-severity issues more than doubling in just one quarter. This growing scale of potential damage is one of the most pressing challenges in the industry. The attack surface has expanded significantly, with shared infrastructure like electric vehicle charging networks and common backend systems presenting concentrated risks. Attackers are frequently using diagnostic interfaces to gain initial access, using seemingly minor systems like infotainment units as stepping stones to reach deeper into the vehicle's architecture. Furthermore, the complex supply chain introduces additional risks, as third-party breaches can easily expose sensitive engineering data or disrupt operations. To navigate this changing landscape, manufacturers must establish complete visibility over all software dependencies and external components. Without a clear and comprehensive view of these interconnected systems, automakers simply cannot respond fast enough to secure their vehicles against the accelerating pace of new threats.


Crypto-Agility Is the Goal. The PQC Migration Is Only Its First Test

The migration to post-quantum cryptography (PQC) should not be treated as a finite project, but rather as the first major test of a broader "crypto-agility" program. While organizations often assume new cryptographic algorithms will remain secure for decades, recent vulnerabilities discovered in schemes like HAWK and Classic McEliece demonstrate how quickly security assessments can change. Instead of simply replacing old algorithms, organizations must build the capability to swap out cryptography seamlessly whenever necessary. There are six primary reasons organizations will need to change algorithms again: cryptanalysis of new algorithms, the acceleration of cryptanalysis via AI tools, implementation flaws in PQC libraries, differing national algorithm standards, routine deprecation schedules, and the eventual development of quantum computers. The goal of a crypto-agility program is to provide a permanent, funded capability to manage these shifts without disrupting ongoing operations. While regulatory deadlines make PQC migration an urgent priority, the true measure of success is passing a rehearsed algorithm change on schedule. After this capability is proven, it should transition to a dedicated owner with its own budget, ensuring the organization remains secure against both current and future cryptographic threats.


The Economics Behind AI’s Infrastructure Boom

The article examines the massive economic forces driving today’s AI infrastructure boom and argues that the scale of investment has quietly pushed AI into the realm of heavy industry rather than experimental technology. It explains how “free” AI tools mask enormous underlying costs, much like earlier tech platforms that used subsidized pricing to gain market share. Building modern AI data centers requires tens of thousands of high‑end GPUs, huge amounts of power, advanced cooling systems, and dedicated grid infrastructure. As a result, capital spending by major cloud and AI companies has surged to levels that exceed their operating cash flow, forcing them to rely on complex financing structures involving private equity, bond markets, and long‑term debt. The article warns that these arrangements hide significant risk, especially as hardware becomes obsolete quickly and demand forecasts remain uncertain. It also questions whether advertising, subscriptions, or corporate spending can realistically cover annual operating costs that may reach several trillion dollars. Some companies are already cutting jobs to offset rising AI expenses, raising concerns about broader economic consequences. While the author acknowledges that predictions of collapse may be overstated, he suggests the current trajectory is financially unsustainable and that the industry will eventually face a reckoning, whether through consolidation, slower growth, or a painful correction.


From Reusable to Regeneratable: Rethinking the Shared UI Component Library

According to a recent InfoQ article by Daniel Curtis, the long-standing practice of building company-wide UI component libraries is becoming outdated as AI coding agents mature. For years, organizations relied on centralized libraries to ensure consistent design, accessibility, and speed, avoiding the need for multiple teams to rebuild standard elements like date pickers and buttons. However, these libraries come with a steep, long-term maintenance cost. Managing dependencies, resolving conflicting priorities across teams, and treating the library like a standalone project creates significant overhead that often outweighs the initial benefits. The author argues that with the rise of AI tools capable of regenerating styled, accessible code on demand, the economics of reuse have fundamentally shifted. Instead of maintaining a single shipped code package, companies should centralize their design systems, tokens, guidelines, and testing frameworks. Visual-regression, accessibility, and token-conformance tests ensure the regenerated code remains trustworthy and consistent. While some curated code might still be necessary for complex widgets or strict accessibility standards, AI allows teams to move from a rigid "reusable" model to a flexible "regeneratable" one, reducing the burden of endless library maintenance while preserving the core benefits of a unified design language.


Spring Boot Microservices Architecture: What I Would Build Differently at Senior Level

The article argues that a production-ready microservices architecture goes far beyond assembling tools like API gateways, software containers, or standard message brokers. At a senior engineering level, the focus shifts to defining clear boundaries based strictly on business needs and data ownership, rather than generic technical layers. The author emphasizes that independent services should never share a single database, as this practice creates a fragile system where one team's database changes can easily break another's functionality. Because distributed systems completely lack simple rollback buttons, developers must deliberately design workflows with explicit recovery paths for partial failures instead of relying on traditional transactions. Furthermore, operations must be designed to safely handle duplicate requests, meaning that processing the exact same event twice should be a completely normal scenario rather than a critical system error. Long chains of synchronous network calls should be controlled through strict timeout limits and careful capacity planning to prevent one slow dependency from crashing the entire system. Finally, comprehensive system observability is considered essential to track requests across multiple services. Ultimately, a mature architecture is defined by its ability to isolate unexpected failures, protect shared resources, and gracefully manage moments when network dependencies stop working normally in a production environment.


When the Platform Can Say No Without Saying Why

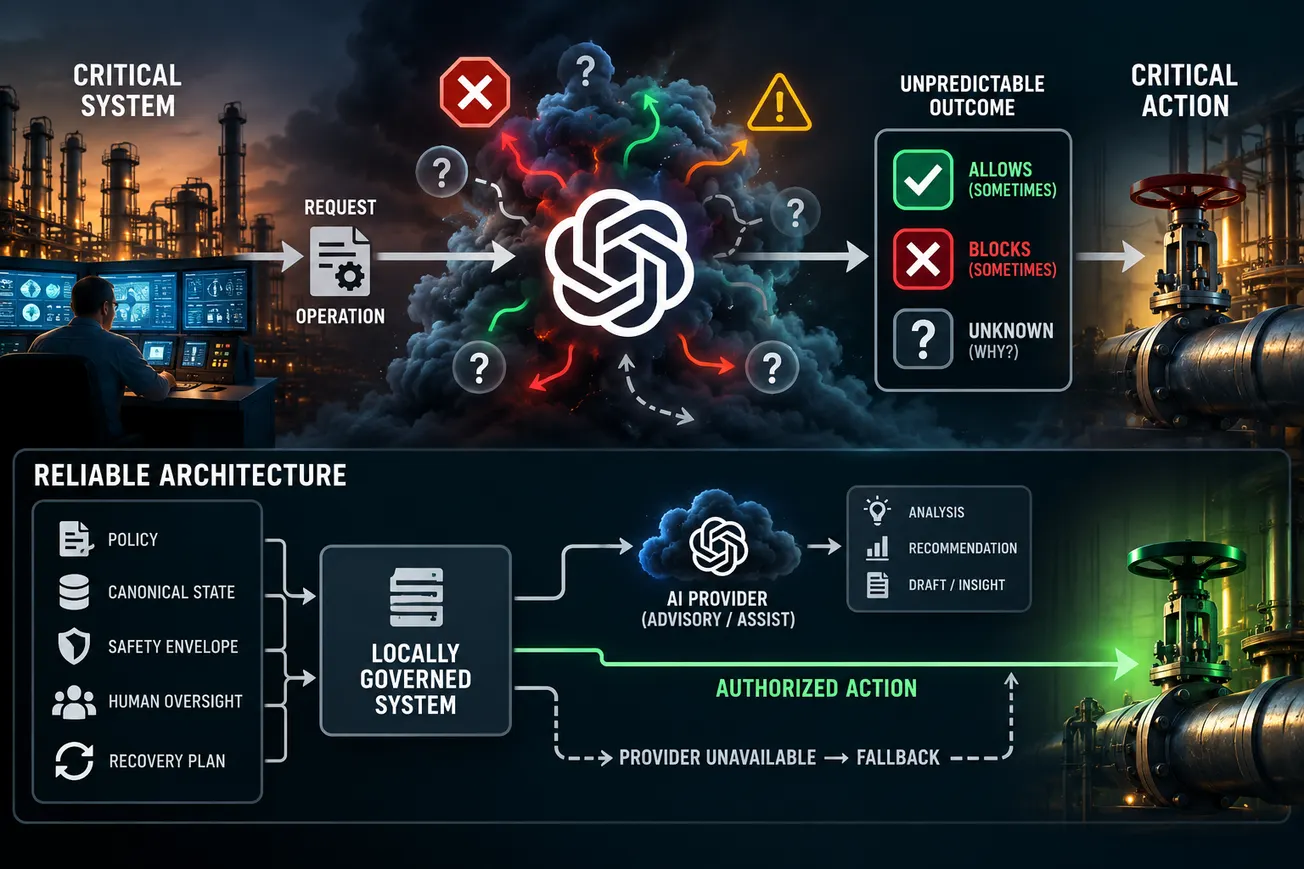
When an AI platform uses opaque safety controls to deny operations without explanation, it introduces significant reliability risks for system architects. While security mechanisms like firewalls or access controls routinely deny actions, their rules and error codes are typically known, allowing engineers to build predictable, resilient systems around those boundaries. However, when a platform blocks a seemingly ordinary repository action—offering no policy identifier, reason code, or consistent failure pattern—that safety control effectively becomes an uncharacterized availability dependency. Without understanding the failure rate, the exact trigger, or how to reliably reproduce the error, designers are forced to assume the execution path could become unavailable at any time. Standards like the NIST AI Risk Management Framework and ISO reliability guidelines emphasize that external dependencies must remain governable. Organizations cannot outsource their risk management; they need measurable outcomes, clear service-level agreements, and observable failure modes to maintain functional safety. Furthermore, relying on multiple downstream connectors (like GitHub, Slack, or Drive) through a single AI provider creates a common-cause failure point. If one opaque gate governs all these paths, they can all fail simultaneously, proving that true system resilience requires independent redundancy rather than just multiple adapters.


Batch Processing: Understanding Distributed Job Orchestration

Distributed job orchestration manages complex computing tasks across multiple machines, much like an operating system coordinates processes on a single computer. When a system needs to run a large batch process, a scheduler receives the request and assigns the work to executors, such as Kubernetes or Hadoop. These executors rely on three core components: task executors that run the commands, a resource manager that tracks available memory and processing power, and a scheduler that decides which machine handles which task. Allocating these resources is a complex balancing act, often using practical approaches like priority queues to keep the system efficient without leaving tasks stranded. In these systems, tasks are organized into workflows where the output of one job naturally becomes the input for the next. To keep these dependent jobs properly organized and decoupled, data is typically shared through a distributed file system. Because hardware or network failures are inevitable in large setups, fault tolerance is built directly into the design. For example, traditional models like MapReduce save intermediate progress to disk to prevent data loss, while newer frameworks like Spark hold this data in memory to speed up the process, ensuring the system remains highly reliable without sacrificing overall performance.


Shaping Board Culture Amid Structural and Contextual Obstacles

A successful corporate board relies on much more than strict compliance and formal processes; its true effectiveness is rooted in a strong, carefully cultivated culture. Board culture encompasses the shared values, everyday behaviors, and social norms that dictate how directors interact, debate, and ultimately make decisions. To achieve organizational excellence, boards must foster an environment of trust, openness, and psychological safety. This atmosphere is essential for ensuring that diverse perspectives are actually heard and used, allowing directors to comfortably challenge assumptions and provide sound judgment. When these elements are present, the board and management can operate as distinct but deeply collaborative teams. However, shaping this ideal culture is rarely simple. Boards must navigate various structural and contextual obstacles that influence their dynamics. Legal frameworks, market expectations, and distinct national customs all play a significant role. For example, the governance system in Germany, which mandates employee representation on supervisory boards, creates a rich but complex environment for boardroom interactions. Overcoming these hurdles requires intentional effort, particularly from the board chair, who must actively encourage constructive dialogue and candid feedback. Ultimately, a resilient board culture transforms diverse insights into sustainable value, protecting the organization from the severe consequences of poor oversight and constrained communication.


The Provenance Gap – Why Enterprise AI Is Creating a New Evidence Challenge

As organizations deploy advanced AI in everyday operations, a major challenge is emerging around how we govern these systems when they make decisions on their own. Traditional software relied on fixed rules and predictable paths, making it easy to track exactly how a result was produced. Modern AI, however, gathers information, interprets instructions, and creates responses on the fly. This fundamental shift moves the focus from simply tracking what a system did to proving why its decisions can be fully trusted. While current monitoring tools are good at logging the technical steps an AI takes, they cannot prove whether the underlying information was accurate, current, or properly approved. This growing gap highlights the clear need for provenance: the ability to connect an AI generated outcome directly to credible, authoritative evidence. Rather than just capturing raw data, provenance ensures that we understand the original sources and policies shaping a specific decision. Because AI systems assemble their reasoning dynamically, proving that their conclusions are valid is becoming just as important as knowing how they reached them. Ultimately, moving beyond basic observation to secure a clear chain of evidence will be completely essential for building reliable, trustworthy systems that organizations can confidently use in the real world.