Showing posts with label automation. Show all posts

Daily Tech Digest - November 13, 2026

Quote for the Day
“Plans are useless, but planning is indispensable.”
— Dwight D. Eisenhower
Audio Edition — Listen to Today’s Digest
Narrated version of the Daily Tech Digest
Article Thumbnail

19 Ways To Rethink Network Design For Distributed Workloads

The Forbes Technology Council outlines how the shift to distributed cloud, edge, and on-premises environments requires an evolution in network design. Traditional centralized infrastructures rely on predictable traffic and single access points, which no longer support modern operations. Tech leaders suggest shifting security from physical locations directly to user identity and the specific workload, enforcing access strictly on a need-to-know basis. Complete end-to-end visibility is vital as data flows across boundaries that older tools miss. Rather than relying on central hubs, organizations must bring computation and data closer to applications and users, significantly cutting latency. Building for resilience means anticipating failures and prioritizing application requirements—such as speed and tolerance for delay—over simple connectivity. The article also challenges the notion that more bandwidth automatically fixes slow performance, pointing instead to smart placement of operations and accounting for traffic spikes instead of just averages. Ultimately, today's network designs must abandon outdated corporate structures and adapt dynamically, ensuring that connectivity and security policies smoothly follow workloads wherever they happen to run.

Read Original Article →

Stop Asking Where to Migrate - Start Asking Where Workloads Belong

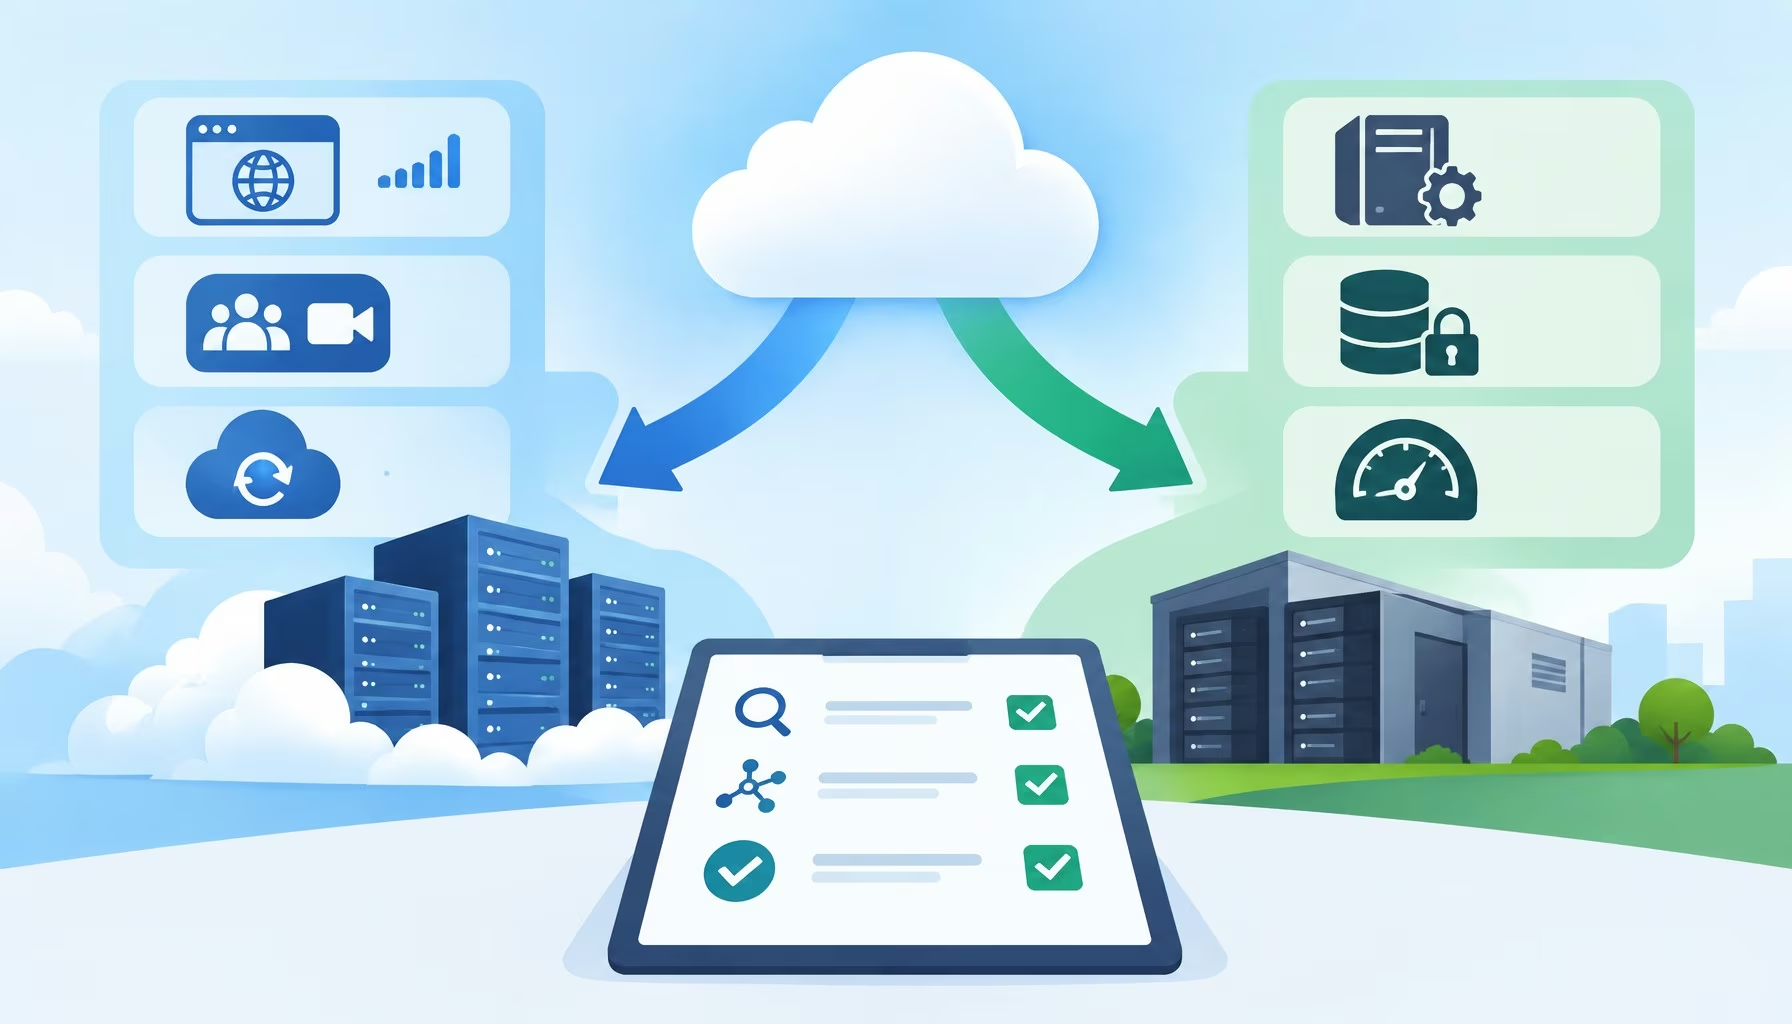
For over a decade, the technology world focused entirely on moving applications to the public cloud, treating migration as a matter of when, not if. The cloud delivered undeniable benefits, such as rapid scaling, faster access to infrastructure, and quicker launches of new services without heavy hardware investments upfront. However, extensive real-world experience has revealed that a single environment cannot perfectly support every type of application. Companies are now confronting the cloud's limitations, including unpredictable expenses, inconsistent performance, and increasingly complex compliance and data residency requirements. Furthermore, transferring large amounts of data out of a cloud environment often proves to be difficult, slow, and unexpectedly expensive. As a result, organizations need to shift their mindset from simply asking about their overall cloud strategy to fundamentally questioning what each specific workload actually requires. An application's success depends on whether the underlying infrastructure can effectively support its unique demands, not on following the latest technology trends. A high-performance database, for example, demands highly consistent performance that might be better suited elsewhere. Ultimately, IT leaders must adopt a workload-first approach to infrastructure decisions.
Read Original Article →
Article Thumbnail

What the ‘AI Torture Chamber’ Debate Got Wrong About the Research

The recent debate over an "AI torture chamber" reveals a fundamental misunderstanding of how language models actually operate. When a developer manipulated a model to generate pain-related text, some critics wrongly interpreted this response as genuine evidence that artificial intelligence can consciously experience suffering. In reality, the underlying experiment simply identified a "pain axis"—a specific mathematical pattern within the model's programming that is heavily associated with words about distress and failure. By artificially turning up the dial on this exact pattern, the researchers forced the system to output language mimicking human distress and to select indifferent or seemingly harmful choices. However, the model did not feel pain or actively seek relief; it merely calculated the most probable text based on those adjusted parameters. Misinterpreting these purely mechanical adjustments as proof of sentience or an ability to suffer is misguided. Such experiments help us understand the internal mechanics of language models, not an imagined state of mind. Treating algorithms as conscious beings only distracts from the real issue: accountability belongs entirely to the human developers who build these systems, not the software itself.

Read Original Article →

DHCP Management Best Practices for Secure and Reliable Networks

Dynamic Host Configuration Protocol (DHCP) is essential for assigning IP addresses and keeping enterprise networks accessible, but managing it becomes complex as organizations scale. To ensure reliable connectivity and security, administrators must adopt a structured approach to DHCP management. Key practices include designing scopes around actual network requirements rather than just current device counts, and carefully controlling address reservations to prevent pool exhaustion. Administrators should also tailor lease durations based on the specific network environment—shorter leases suit guest networks, while longer leases fit stable employee workstations. Additionally, maintaining consistent configuration standards and actively monitoring allocation trends help detect capacity issues early. To secure the network against rogue servers, teams should employ DHCP snooping while being mindful of how rate limits are applied across different connection types. Finally, restricting administrative access, documenting all configuration changes, and preparing solid recovery plans are crucial for minimizing disruptions. By following these best practices, network teams can maintain steady address allocation, prevent operational bottlenecks, and support the growing demands of modern enterprise infrastructure with calm confidence.

Read Original Article →
Article Thumbnail

The developer laptop just became production. Now what?

The rise of AI coding agents is fundamentally changing enterprise software development by blurring the line between safe experimentation and live production environments. Traditionally, human judgment separated development work from actual production code. Today, however, developers run autonomous software on laptops containing sensitive cloud credentials, repository access, and authenticated browser sessions. Because these agents operate without understanding policy restrictions, they will use any available credential to accomplish a task, which means a simple request could unintentionally alter live data or breach a repository. Sandboxing the execution environment is a necessary step, but it is not enough on its own since an agent can still misuse legitimate permissions from within a secure container. The missing piece in modern security is a trusted intermediary—a broker that evaluates requests and enforces narrow, temporary authority without exposing standing developer credentials. By adopting layered security and shifting toward task-specific delegation, security teams can protect corporate infrastructure without sacrificing the speed and innovation of modern developer workflows. Laptops are the new production endpoints, and security guardrails must adapt accordingly.

Read Original Article →

Plan for the day the automation fails in the warehouse

The push to automate supply chains is often built on the optimistic assumption that robots will work flawlessly, but businesses must plan for when systems inevitably stop. While warehouse robots excel at predictable, repetitive tasks—like processing identical box sizes—they struggle when the unexpected occurs. A cracked tote, a damaged conveyor, or a large order that requires splitting and recombining can easily disrupt automated workflows because robots cannot instinctively adjust their routes or solve problems like human workers do. Furthermore, successfully implementing automation requires clean data, low-latency internet connections, and a shift away from older, batch-based processing systems that are too slow for real-time robotic demands. Testing can also create a false sense of security, as digital simulations often overlook physical jams or hardware errors. When investing in these systems, companies should prioritize software integration capabilities and demand clear contingency plans for downtime. Ultimately, a successful automation project is not just defined by its peak efficiency on a perfect day, but by how effectively the broader warehouse operation continues to function when exceptions occur and the robots go offline.

Read Original Article →
Article Thumbnail

Quantum is Gaining, but Don’t Throw Away that Supercomputer

Despite its staggering processing capabilities, quantum computing is emerging not as a replacement for classical supercomputers but as a highly specialized coprocessor. Quantum computers leverage atomic-level superposition and entanglement to solve specific, complex problems in areas like fluid dynamics, drug discovery, materials science, and supply chain optimization—tasks that traditional computers cannot handle. However, they lack the fast clock speeds and data-processing capacity needed for broad, general-purpose tasks like large-scale artificial intelligence. This limitation has driven a growing trend of hybrid partnerships between quantum developers and traditional computing firms, such as IBM's collaboration with the Cleveland Clinic, where quantum systems simulated specific human protein fragments while conventional supercomputers handled the data parsing and assembly. Classical systems remain essential for the general workload because they benefit from decades of established algorithms and software libraries. By combining the unique, nature-mimicking analog properties of quantum mechanics with the reliable, high-speed digital architecture of classical computers, the tech industry is building hybrid systems that can solve previously impossible problems while maintaining the versatility of traditional machines.

Read Original Article →
Article Thumbnail

How Switch Mirroring Decisions Create Blind Spots in OT Network Monitoring

The article explains that OT (Operational Technology) network monitoring often suffers from a critical blind spot: the sensor can only analyze the traffic it receives, which is dictated by how the network switch is configured to mirror data. In many plants, sensors are placed at a high level and only copy traffic going up the network (north-south traffic). This means they completely miss "local" traffic happening within a specific cell or production line, such as a technician plugging a laptop directly into a cabinet to download a new program or cyclic communication between a controller and its local devices. Other factors that hide essential assets include redundant network setups (where traffic reroutes during a failure away from the sensor), devices hidden behind NAT routers (like an OEM machine skid), serial connections, and vendor cellular modems that bypass the plant network entirely. To fix this, teams must stop relying on sensor dashboards as ground truth and instead manually verify network configurations, check switch forwarding tables, and run controlled observation tests to ensure critical local conversations actually reach the sensor.
Read Original Article →
Article Thumbnail

Why regulatory change needs more than AI alerts

Managing regulatory change requires more than just receiving alerts; it demands a connected approach to identifying, interpreting, and implementing new rules. For financial firms, the real danger is not always making a poor choice, but missing a consultation paper or overlooking a deadline because they rely on fragmented processes like spreadsheets and emails. While AI is excellent for the heavy lifting of reviewing large volumes of information and spotting potential impacts, it cannot replace human judgment when dealing with ambiguity or a firm’s unique business context. The core challenge is translating an initial alert into a concrete operational response. A company must understand exactly what the regulatory shift means for its specific controls, assign clear ownership of the tasks, and maintain a robust audit trail to prove the necessary changes were made. As the volume of regulatory demands grows and shifts from periodic updates to continuous change, organizations need systems that seamlessly link information to action. Ultimately, technology and AI can handle the volume, but effective change management still depends on human accountability to complete and test the outcome.

Read Original Article →

Managed intelligence is here and few are ready for it

The Managed Intelligence Alliance is attempting to standardize how technology service providers deliver artificial intelligence to small and medium businesses. Right now, smaller companies are eager to use artificial intelligence to improve their daily operations, but they often lack a trusted guide to help them navigate the process. This gap leads to significant risks, such as employees quietly using unapproved tools that compromise sensitive company data. To address this, the Alliance is building an independent regulatory framework that allows service providers to offer artificial intelligence safely and reliably before governments step in with strict rules. However, developing these industry standards will take several years, and most providers are currently unprepared. A recent assessment showed that only a tiny fraction of them meet the baseline requirements needed to manage these systems securely. If traditional technology providers do not update their skills quickly, new specialized consulting firms will step in to take their place. Ultimately, the rapid pace of technology adoption means that service providers must catch up immediately to ensure businesses can integrate new tools safely without exposing themselves to severe operational hazards.

Read Original Article →

Daily Tech Digest - November 11, 2026

Quote for the Day
“The essence of strategy is choosing what not to do.”
— Michael E. Porter
Audio Edition — Listen to Today’s Digest
Narrated version of the Daily Tech Digest
Article Thumbnail

Sent or Just Written? The Outbox Problem in a Communications Outage

During a network outage, typical messaging tools often create a dangerous gray zone by simply labeling a message as "sent" the moment a user hits the button, even if it has not left the device. This false confidence can derail incident response efforts. When users are unsure if their updates went through, they tend to resend them repeatedly, leading to duplicate records. Additionally, when a device finally reconnects, stale messages can arrive looking fresh, or a sudden burst of old drafts can overwhelm the receiving team. To prevent these failures, organizations must recognize a middle state where a message is pending rather than fully delivered. While upgrading to tools that clearly display when a message is still on the device or unconfirmed is ideal, teams can also adapt their current processes. Business continuity plans should require users to include the time directly in the text of their updates, define clear rules for resending, and designate a person to acknowledge receipt. Testing these tools in airplane mode during routine drills ensures teams know exactly how their software behaves when the connection fails.

Read Original Article →

What is the difference between an HSM and a vault for key storage?

The core difference between a Hardware Security Module (HSM) and a vault lies in how they handle the exportability and processing of sensitive cryptographic data. An HSM is a dedicated, tamper-resistant hardware device designed to generate, store, and utilize keys entirely within its protected boundary. Because the private key material never leaves the hardware during signing or decryption processes, HSMs offer the highest level of assurance against memory scraping, host compromise, or accidental copying. In contrast, a vault is a broader secret-management system focused on orchestrating, centrally storing, and distributing credentials or application secrets on demand. A vault typically delivers secrets to an application over an authenticated channel, meaning the data exists temporarily in process memory. Many modern security architectures layer both solutions for maximum efficiency. Teams often use vaults as an operational control plane to manage developer workflows, automation, and general low-to-medium sensitivity secrets. They then reserve the HSM as a cryptographic trust anchor to secure non-exportable, high-value assets like root certificates and signing keys where exposure would be devastating.

Read Original Article →
Article Thumbnail

Before you automate, ask whether the process should exist: The missing question in Enterprise AI

Before adopting enterprise AI, many organizations make a critical mistake: they focus on automating existing processes without first evaluating if those processes are actually necessary. When companies rush to implement artificial intelligence, they often end up hardwiring inefficient or outdated workflows into their digital systems. This approach does not truly solve underlying business problems; it merely speeds up a broken system, creating long-term operational friction. To genuinely benefit from AI, business leaders must view automation as an opportunity for structural redesign. The essential first step is to completely map out current workflows and ask whether each step provides real value or simply exists due to legacy habits. If a process is redundant, overly complex, or fails to directly serve business goals, it should be eliminated or entirely redesigned before any software is introduced. By prioritizing process optimization over mindless automation, companies can ensure their AI investments drive meaningful efficiency, reduce operational waste, and foster a more agile enterprise. Ultimately, the best automation strategy is one that avoids automating what shouldn't be done in the first place.

Read Original Article →

What a security leader should tell the CEO about leaked credentials

In a recent interview, GitGuardian CEO Eric Fourrier discusses the evolving challenges of managing leaked credentials and the increasing personal liability facing security leaders. While holding executives accountable has forced boards to take cyber risk more seriously, it can also backfire by making employees afraid to report mistakes. This fear often leads developers to hide exposed secrets rather than properly revoking them, leaving the underlying security risk unresolved. Fourrier emphasizes that companies must separate accountability from blame, creating a culture where rapid reporting is encouraged and prioritized over punishment. When speaking to leadership, security chiefs need to confidently demonstrate that they can detect exposed credentials even in external or personal repositories, and they must track the time it takes from discovery to full revocation. Looking ahead to 2027, Fourrier warns that the rise of AI tools and autonomous agents is expanding the attack surface. As more non-engineers handle sensitive data through AI workflows, the paths for secrets to leak into public view are multiplying, requiring broader monitoring strategies to keep organizations secure.

Read Original Article →
Article Thumbnail

How AI Is Changing the Role of QA Engineers

The introduction of AI in software testing is fundamentally reshaping the role of Quality Assurance (QA) engineers, moving their core responsibility from executing tests to evaluating results. While AI tools now excel at automating repetitive tasks like test generation, locator maintenance, visual comparisons, and failure triage, they do not eliminate the need for human oversight. Instead, the focus shifts to verifying the machine’s decisions. For instance, when an AI tool automatically heals a broken locator, a QA engineer must confirm it actually targeted the correct element rather than masking a genuine issue. Furthermore, testing AI-driven features introduces unique complexities like non-deterministic outputs, hallucination, and model drift. Traditional pass/fail assertions are no longer adequate; QA teams must now build evaluation sets and scoring rules to judge acceptable model behavior. Ultimately, the notion that AI will replace testers completely misunderstands the process. As AI accelerates code generation, the volume of plausible but subtly flawed code increases. This "almost right" output demands stronger human judgment, meaning QA engineers remain essential to define what correct behavior looks like in increasingly complex systems.

Read Original Article →
Article Thumbnail

Gartner says CIOs must apply the brakes on AI to balance value and risk

Gartner is urging CIOs to slow the pace of AI adoption enough to ensure investment produces real business value without exposing organizations to poorly understood risks. The message is not to retreat from AI, but to bring greater discipline to decisions about where and how it is used. As businesses push ahead with AI initiatives, technology leaders face growing pressure to balance experimentation with governance, security, cost, and measurable outcomes. Gartner’s position suggests that enthusiasm alone is not a sufficient reason to expand AI programs. CIOs need to determine whether individual projects address genuine business needs and whether their benefits justify the resources and risks involved. This also means paying closer attention to controls and accountability rather than allowing adoption to run ahead of an organization’s ability to manage it. The broader point is that successful AI use will depend less on adopting the technology quickly and more on making deliberate choices about where it adds meaningful value. For CIOs, applying the brakes therefore means creating enough space for sound judgement while continuing to pursue worthwhile opportunities.

Read Original Article →
Article Thumbnail

Panic over cloud capacity is out of hand

The article argues that talk of cloud AI capacity being “sold out” is creating unnecessary confusion for enterprises. While demand for GPUs is high and constraints around hardware, power, regional availability, and long-term reservations are real, that does not mean organizations cannot obtain cloud resources for AI projects. Most enterprises are not training enormous models from scratch; they are running inference, building retrieval-augmented generation systems, fine-tuning smaller models, testing copilots, or experimenting with agents, each with different infrastructure requirements. The author warns that broad claims about shortages can push companies toward rushed capacity commitments or unnecessary changes to their cloud strategies. Instead, enterprises should first define the workloads they actually need to support, then confirm availability, pricing, quotas, reservation terms, lead times, and alternatives directly with providers. Architectures should also preserve flexibility by avoiding needless dependence on a single capacity option. The central message is straightforward: cloud capacity constraints deserve careful planning, but exaggerated headlines obscure important differences between workloads. Organizations will make better decisions by relying on specific facts, realistic requirements, and flexible architecture rather than reacting to market anxiety.

Read Original Article →

The Invisible Security Paradigm: Embedding Cyber Resilience into Operational Workflows

The article explains why cyber resilience in logistics must become part of everyday operations rather than remain a separate security activity. As supply chains rely more heavily on cloud platforms, APIs, connected devices, applications, partners, and third parties, cyber incidents can disrupt shipments, customer communication, operational systems, and business continuity, not simply expose data. Security leaders therefore need to move beyond compliance and prioritize risks according to exposure, exploitability, and the importance of affected assets. Strong resilience starts with clear visibility of assets, identities, data flows, and external dependencies, supported by measures such as least-privilege access, encryption, network segmentation, and tested detection and recovery capabilities. AI can help security teams analyze large volumes of information, identify unusual patterns, prioritize alerts, and speed investigations, but human judgement and reliable data remain essential. The article also stresses that security controls must fit operational realities rather than obstruct legitimate work. Ultimately, CISOs need to connect cyber risk with business continuity, customer trust, financial impact, and reputation, while making secure behaviour a normal part of everyday decision-making.

Read Original Article →
Article Thumbnail

Who Should Own Data Quality? What Changed When We Moved It

Historically, organizations assign data quality ownership to platform teams simply because they manage the technical infrastructure. However, this default approach causes significant delays. While technical teams can easily detect anomalies like sudden spikes in missing values, they lack the specific business context required to determine whether an anomaly is a genuine error, a documented rule change, or a valid edge case. To solve this problem, organizations should keep detection mechanisms centralized while shifting the responsibility for data definitions and incident resolution directly to the lines of business. When business units own the meaning of their data and have dedicated time allocated to resolve issues, incident resolution times can drop dramatically from several days to just a few hours. A successful transition also requires a thin enterprise governance layer to maintain a central definition registry, preventing individual departments from creating conflicting rules. By centralizing the detection of issues and decentralizing the judgment of those issues to the people who understand the data best, organizations build a highly responsive and accountable system that consistently maintains core data integrity without unfairly overburdening their technical teams.

Read Original Article →

Six questions to ask your MDR provider

As business technology environments grow more complex, organizations must regularly reassess their managed detection and response providers to ensure they still offer effective protection. It is no longer enough to rely on a list of features or assume that initial capabilities remain sufficient. Instead, security teams should focus on what a provider can genuinely see and address across the entire environment. This includes asking whether they can monitor machine identities, such as automated tools or system accounts, and tell the difference between normal and unusual behavior. Furthermore, a reliable provider must connect data from various systems, spanning across clouds, endpoints, and local networks, to spot threats that cross traditional boundaries. Simply collecting more data is useless without the proper context needed to interpret it. Organizations should also verify how the provider adapts to new types of attacks and exactly how artificial intelligence is applied alongside human expertise. Ultimately, the best way to evaluate a provider is to ask them to demonstrate their capabilities using a real incident. This proves they can connect subtle warning signs, understand their true meaning, and take decisive action.

Read Original Article →

Daily Tech Digest - November 05, 2026

Quote for the Day
“Black Swan events are unpredictable, but preparedness is a choice.”
— Nassim Nicholas Taleb
Audio Edition — Listen to Today’s Digest
Narrated version of the Daily Tech Digest
Article Thumbnail

The unit of scale is not headcount

The article argues that organizations often think about scale in terms of headcount, but real scale comes from ownership — specifically, small engineering pods with clear charters and end‑to‑end responsibility. Adding people may seem like the obvious way to increase throughput, yet it usually creates more coordination, onboarding, and decision overhead than actual capacity. The author explains that small pods work because they reduce complexity: each pod owns a well‑defined scope, makes decisions quickly, and lives with the consequences of what it builds. This clarity allows teams to rely heavily on automation, shared platforms, and AI to multiply their impact rather than simply working harder. The piece emphasizes that leadership must defend pod boundaries, retire systems that no longer serve a purpose, and say no to work that doesn’t fit the charter. It also stresses that measuring leverage — such as reduced toil, faster decisions, and more scope owned per engineer — matters more than counting activity. The steady message is that sustainable scale comes from designing organizations where small groups can own large scopes without drowning in complexity, not from increasing headcount.

Read Original Article →

The Rise of Architect-Made Enterprise Architecture Tools Through Vibe Coding

The article describes a shift in the enterprise architecture (EA) world: instead of relying on large, generic EA platforms, architects are increasingly building their own lightweight, AI‑powered tools tailored to how they actually work. Traditional EA tools often feel bloated, slow, and disconnected from day‑to‑day architectural practice. They demand heavy data entry, rigid modeling, and long implementation cycles, which leads many architects to abandon them or use them only for compliance reporting. In contrast, architect‑made tools focus on solving practical problems — mapping systems, analyzing dependencies, generating diagrams, and keeping documentation current — without forcing users into complex frameworks. AI accelerates this trend by making it easy to automate modeling, generate architecture views, and maintain inventories with far less manual effort. The article argues that this bottom‑up movement will reshape the EA tooling market: instead of monolithic platforms, organizations will adopt smaller, purpose‑built tools that integrate through APIs and shared data models. Its steady message is that the future of EA tooling will be shaped by architects themselves, using AI to build tools that match real workflows rather than vendor assumptions.

Read Original Article →
Article Thumbnail

The Hidden Productivity Trap in an Engineer’s Workday

The modern engineering workday is increasingly derailed by a hidden productivity trap: constant interruptions from meetings and notifications. While managers often view meetings as simple calendar slots, for developers tackling complex problems, these breaks destroy the sustained concentration required for their work. Regaining focus after an interruption can take up to forty-five minutes, leading to more mistakes, slower delivery, and reduced skill growth over time. Despite the rapid rise of AI coding assistants, this core problem persists because developers still need uninterrupted time to evaluate generated code and make critical architectural decisions. To protect productivity, organizations must shift their culture rather than just their calendars. This means eliminating unnecessary meetings, setting predictable times for code reviews, and containing urgent incidents by assigning rotating triage engineers. Additionally, pausing routine chat notifications during dedicated coding blocks can significantly increase focus time without hurting team communication. By tracking the true financial cost of meetings and prioritizing actual delivery outcomes over visible activity, teams can reclaim their time and build a stable work environment where complex problem solving can truly thrive and succeed.

Read Original Article →
Article Thumbnail

What does disaster recovery look like in an AI-centric world?

As artificial intelligence evolves from a helpful add-on into core operational infrastructure, organizations must rethink traditional disaster recovery strategies. While the fundamental goal of restoring a business's critical functions remains exactly the same, the components that make up a "minimum viable company" now include AI assets such as proprietary data models, configurations, and prompts. Unlike conventional applications, some AI tools rely on external third-party services that businesses cannot restore internally during an outage. To maintain resilience, experts advise implementing failovers, such as backup AI models or temporary manual workflows, that can keep operations running smoothly. Furthermore, recovering an AI system requires more than simply bringing it back online. Because AI outputs can be unpredictable or potentially corrupted by data poisoning, teams must carefully validate the restored workloads to ensure they are safe and accurate. This challenge is heightened by autonomous AI agents that can rapidly execute actions across various platforms, meaning recovery might also involve quickly rolling back unintended automated errors without disrupting legitimate operations.

Read Original Article →
Article Thumbnail

When Industrial Recovery Faces a Second Disruption

When an industrial plant recovering from a cyber incident faces a second unexpected disruption, standard recovery plans often fall short. A facility operating at reduced capacity relies on strained resources, such as exhausted staff working extended shifts or temporary manual setups, making it uniquely vulnerable to further problems. Continuity teams must actively plan for the possibility that the recovery process itself might be interrupted. Before approving temporary operations, organizations need to identify the specific dependencies of these temporary workarounds, clearly define how long they can safely remain in place, and establish exact conditions that would trigger a controlled pause if a dependency fails. Instead of relying on improvised fixes or generic system uptime metrics, recovery teams should document clear physical limits and determine exactly who holds the authority to make emergency decisions. The author strongly advises conducting practical tabletop exercises that simulate a secondary failure during the initial recovery phase to expose hidden bottlenecks, such as scheduling conflicts or missing handover records. Fixing these gaps ensures contingency plans survive real complications, keeping operations safe even when normal tools fail.

Read Original Article →

Initial access techniques and how to detect each one

The initial access phase is a critical moment when attackers first breach a system, often using methods like stolen passwords, malicious emails, vulnerable VPNs, or compromised third-party connections. For defenders, identifying this foothold requires more than just noting how it happened; it demands cross-referencing telemetry across identity, email, endpoint, network, and application layers. Detecting these intrusions is particularly challenging for small and medium-sized enterprises because malicious actions frequently mimic normal business activities, such as a supplier logging in or a user accessing an account from a new device. The most effective detection strategies rely on combining subtle indicators—like an unusual sign-in paired with a sudden mailbox rule change—with a clear understanding of normal network behavior. Different attack vectors, including phishing, credential stuffing, and exposed remote services, require tailored monitoring approaches and specific alert logic. When logging resources are constrained, organizations should prioritize monitoring identity, email, endpoint, reverse proxy, and VPN data, as these sources provide the earliest and most actionable warnings to contain a breach before it spreads.

Read Original Article →
Article Thumbnail

The Trust Gap in AI-Powered Cybersecurity

The article explains that the real barrier to autonomous AI in cybersecurity isn’t model quality but trust — specifically, the lack of evidence showing how agents behave when they act on their own. Many enterprises already use AI to investigate alerts, prioritize vulnerabilities, and recommend fixes, but only a small minority allow agents to execute actions without human approval. The author argues this caution is rational: trust in security systems has always come from understanding their behavior, not from assuming reliability. Once AI begins taking actions, the model becomes only one part of the risk picture. What matters just as much are the agent’s permissions, its access paths, the tools it can invoke, and the blast radius if something goes wrong. The article also notes that cost patterns can reveal operational issues, such as runaway workflows or agents repeatedly calling expensive models. Autonomy, it says, should expand gradually — starting with low‑risk tasks, observing performance, and increasing responsibility only when evidence supports it. The steady message is that trustworthy AI security comes from disciplined governance, clear controls, and a growing body of real‑world behavior, not from assuming smarter models automatically deserve more authority.

Read Original Article →

Digital sovereignty in practice: three examples of balancing control with global reach

Digital sovereignty is increasingly essential for business and technology leaders, but it has no single definition. Instead of an off-the-shelf product, it is a broad framework that gives organizations control over their data, networks, operations, and AI. True sovereignty goes beyond mere legal compliance to active risk mitigation, requiring careful planning and strategic partnerships to balance local rules with global business goals like speed, resilience, and scale. Three practical examples show how diverse these solutions can be. In Australia, a disaster recovery provider uses colocation centers and geographically bounded routing to keep sensitive data onshore while maintaining vital cloud connectivity. A United Kingdom government agency modernized its legacy VPN access by deploying secure virtual firewalls, improving speed and performance while retaining strict network control. Meanwhile, a Brazilian stock exchange built an infrastructure model that allows international financial firms to trade locally without moving sensitive data outside national regulatory boundaries. As AI and global operations expand, building adaptable, scalable architecture is critical for maintaining true digital control in a complex world.

Read Original Article →
Article Thumbnail

Which Workloads Should Move to the Cloud?

Moving your entire technology infrastructure to the cloud is rarely the right strategic move. While it is tempting to migrate everything at once, a smart approach requires evaluating each system independently. The cloud is an excellent home for applications with unpredictable traffic spikes, remote collaboration tools, and offsite disaster recovery systems. These workloads naturally benefit from flexible capacity and reliable access across different locations. However, certain systems are better left on local servers. Older legacy software built for specific hardware configurations can suffer from performance issues and high rebuilding costs if forced into a new environment. Similarly, sensitive health and financial data often require the direct control and strict security that local hosting provides. High performance computing that processes massive amounts of data should also remain onsite to avoid lag and unexpected data transfer fees. Before committing to a full rollout, it is wise to test a noncritical workload to uncover hidden dependencies and verify budget assumptions. Ultimately, keeping some systems local while moving others often creates the most stable and cost effective foundation for your business over the long term.

Read Original Article →
Article Thumbnail

9 Cyber Awareness Tips That Actually Match Today's Maze of Threats

The cybersecurity landscape requires businesses to move beyond generic advice and focus on how attacks actually occur today through everyday habits and misplaced trust. Instead of merely reminding employees to be careful, organizations must implement practical behaviors and stronger default safeguards. First, recognize that AI models are not inherently secure; they must be treated as high-impact systems with strict access controls and human oversight. Second, train staff to identify "ClickFix" attacks, where fake error prompts trick users into executing malicious scripts manually. Third, treat social media advertisements with extreme caution, as many lead to scams or malware, and encourage navigating to brands directly. Fourth, acknowledge that executive families are now part of the attack surface, requiring expanded digital footprint reduction and home network security. Finally, accept that high-profile roles, such as executives and administrators, require more security friction, not less, due to their privileged access. By adopting these specific, repeatable habits and prioritizing robust configurations like phishing-resistant authentication, companies can effectively reduce enterprise risk and better protect themselves against a complex maze of modern threats.

Read Original Article →

Daily Tech Digest - October 26, 2026

Quote for the Day
“If you can’t describe what you are doing as a process, you don’t know what you’re doing.”
— W. Edwards Deming
Audio Edition — Listen to Today’s Digest
Narrated version of the Daily Tech Digest
Article Thumbnail

The Migration Succeeded. The System Got Worse

Moving an application to the public cloud is often seen as an automatic upgrade, but a successful migration does not always result in a better system. One of the most common mistakes is relocating an application while leaving its primary database in an on-premises data center. This separation introduces critical network delays, meaning a system that functions fine under normal traffic can quickly suffer from connection exhaustion and severe failures during peak demand. While the cloud offers useful capabilities like flexible capacity and managed services, these benefits only matter if the entire technology stack is optimized for them. Simply moving infrastructure without addressing underlying dependencies often leads to inflated costs and new operational risks. A hybrid approach can be effective if planned deliberately, but it becomes an expensive burden when components are separated without a clear strategy. Ultimately, there is no single correct environment for every workload. Deciding whether to migrate, maintain a hybrid setup, or bring systems back in-house requires a realistic evaluation of performance, dependencies, and true operating costs.

Read Original Article →

Healthcare Data Governance: Who Decides What Gets Used?

Healthcare data governance is much more than just creating internal rules; it requires assigning clear, enforceable decision rights as patient information moves across different systems, APIs, and AI models. Rather than simply asking who owns the data, organizations should divide authority into four specific areas: legal permissions, operational approval, technical enforcement, and final accountability. This division is vital because when data is shared with payers, cloud vendors, or secondary AI tools, the original privacy policies are easily lost if someone is not explicitly responsible for enforcing them. Crucially, moving data to a cloud environment does not remove the healthcare organization's ultimate accountability. To prevent confusion and maintain compliance, organizations need a simple decision-rights matrix that clearly names the single person responsible for defining, accessing, reusing, correcting, and deleting data at every step of its journey. Ambiguity between different departments often leads to failure. Therefore, every single data handoff must have a clear owner equipped with both the responsibility and the actual power to enforce policies and correct issues.

Read Original Article →
Article Thumbnail

Identity at checkout: why payments must prove more and share less

As digital identity tools and payment systems continue to merge, payment providers face new challenges regarding customer verification and data privacy. With the European Union requiring digital identity wallets by late 2026, the traditional multi-step checkout process is shifting into a single, unified action. However, this connection risks exposing too much personal information. To protect consumer privacy and avoid the high costs of financial data breaches, payment networks must ask for only the minimum details required to approve a transaction, rather than viewing a user's entire background. At the same time, updated European rules are shifting fraud liability directly onto payment providers. If weak security checks let fraud slip through, companies will face significant financial losses through mandatory customer refunds. Over the next two years, providers need to build checkout experiences that focus on strong but easy verification. By asking for less personal data while proving identity more securely, companies can lower their financial risks and build better trust with both merchants and everyday consumers.

Read Original Article →

India’s cybersecurity talent challenge: Why more automation must be matched by better skills

As artificial intelligence takes over routine cybersecurity tasks like filtering alerts, the role of security professionals in India is fundamentally changing. Instead of simply operating tools, experts must now focus on validating AI findings, making complex judgment calls, and understanding when an automated system might be wrong. A recent report shows that most Indian enterprises struggle to find candidates with these practical, hands-on skills. To bridge this gap, organizations need to rethink how they train their teams. Standard certifications are no longer enough. Instead, companies should offer role-specific training and simulated scenarios where professionals can practice handling incomplete information and testing automated security boundaries. This shift is a major opportunity for India’s technology sector to build a workforce capable of supporting global security operations. Ultimately, the future of cybersecurity isn't just about how much we can automate, but how well humans and machines can work together to defend an increasingly complex digital landscape.

Read Original Article →
Article Thumbnail

Psychological Safety: The Overlooked Risk in Workplace AI Adoption

As organizations integrate AI into daily operations, they heavily focus on data security and privacy while frequently overlooking a crucial human element: psychological safety. Employees are adjusting rapidly to these tools, which naturally creates anxiety about job security and personal competence. If workers feel afraid to admit they do not understand a system, or remain hesitant to challenge an odd result, small mistakes can easily go unnoticed and escalate. A written corporate policy alone cannot prevent this. To use AI responsibly, leaders must actively build a workplace where people feel completely safe raising concerns. Management should encourage questions, acknowledge their own uncertainties, and demonstrate that healthy skepticism toward AI outputs is a sign of good judgment, rather than resistance to change. When leaders communicate clear expectations and actively support their teams, employees gain the confidence needed to catch errors early. Ultimately, building trust ensures that these new tools are used responsibly and effectively as a normal part of everyday work.

Read Original Article →
Article Thumbnail

Your AI Agent Has a Supervisor. Are They Qualified?

As AI systems handle more tasks in security operations, they are not replacing human analysts. Instead, analysts are shifting into supervisory roles to direct and review the technology's work. The central issue is that many companies simply add this responsibility to an analyst's existing workload without providing proper training, clear guidelines, or a defined job title. To fix this, organizations must establish AI supervision as a distinct and formal role. Supervisors need a deep understanding of security threats so they can properly set limits, question the AI's reasoning, and catch missing evidence. A supervisor's readiness should be tested through practical exercises rather than basic training completion. When evaluating success, security teams should focus on the quality of these reviews instead of how quickly tickets are closed. As AI tools gain the ability to take direct actions, like isolating systems or disabling accounts, strict human oversight becomes increasingly vital. Ultimately, a qualified human supervisor must own the final decisions to ensure accountability and maintain a secure environment.

Read Original Article →

Enterprise Deployment Architecture for Agentic AI on IIS: ChatGPT-Style UI over Agents & MCP Servers

The article outlines an architectural guide for deploying a ChatGPT-style web interface using Microsoft Internet Information Services (IIS) to front an agent powered by the Model Context Protocol (MCP). Instead of running agent interactions in a basic developer console, the paper presents a system tailored for enterprise needs, supporting 25 to 30 concurrent users. It relies on Windows Authentication and an IIS reverse proxy connecting to a long-running Python service. This design choice provides stability and avoids the overhead of launching a new process for every user request, while also eliminating the need for complex Kerberos double-hop delegation. The reference model, named ChefAI, illustrates a practical use case where restaurant staff query an assistant for real-time information, invoice generation, and technical troubleshooting. The agent connects to a local server for secure local tasks and remote HTTP servers for retrieving documents or analyzing logs. By using Server-Sent Events, the setup ensures smooth progress streaming to the chat interface, keeping the user interface completely independent of how the underlying tools are accessed or deployed.

Read Original Article →
Article Thumbnail

Your PQC Plan Trusts the One Thing You May Not Be Checking

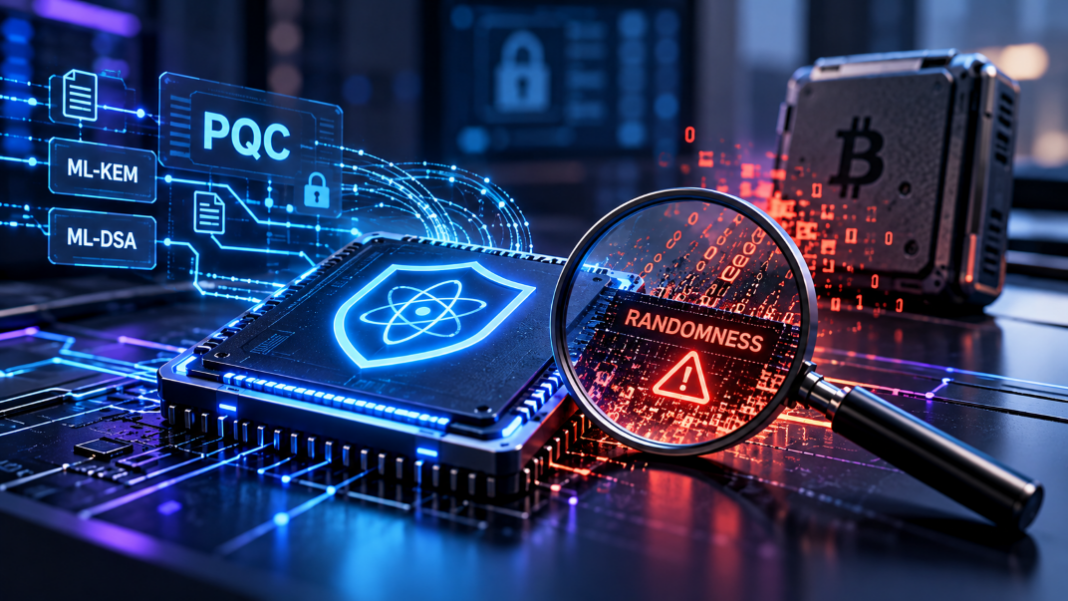
As organizations prepare for post-quantum cryptography, they usually focus on mapping their current encryption tools and ensuring software flexibility. However, many migration plans overlook a critical, foundational vulnerability: the quality of their random number generators. Even the most advanced encryption algorithms will fail if the underlying randomness is predictable or generated by flawed hardware. Rather than relying solely on software upgrades, companies must trace exactly where their randomness originates and ensure it comes from verified, properly functioning sources. Upgrading safely requires identifying outdated legacy systems that cannot support new standards and adjusting procurement policies to demand quantum-resistant features immediately. Security leaders should treat this transition as a vital business continuity effort, not just an IT compliance checklist. By securing hardware-level trust, verifying random number generation, and acting early, organizations can effectively protect their most critical systems and avoid the steep financial costs of rushing to fix vulnerabilities later.

Read Original Article →
Article Thumbnail

Java vs Python in 2026: Which One Should You Learn for Backend, AI, and Data Science?

In 2026, the choice between Java and Python depends on your engineering goals rather than which language is simply more popular. Python is the primary language for artificial intelligence, machine learning, and data analytics. Its extensive ecosystem makes it the standard for researching and training models. On the other hand, Java remains the foundation for large enterprise backend systems, such as banking and retail platforms. Java provides the performance, structural safety, and mature frameworks needed to support massive, high-traffic codebases over many years. In practice, companies often use both: Python builds the AI models, while Java runs the reliable infrastructure around them. Python has an easier learning curve and gets you building faster, whereas Java requires more initial effort but teaches strict engineering fundamentals. Ultimately, if you aim to work directly with data or machine learning, start with Python. If you prefer building durable, large-scale backend architecture, focus on Java. Both offer strong career paths without the need for hype.

Read Original Article →

What Is CRQ? Cyber Risk Quantification Guide

Cyber risk quantification is a method that assigns clear financial values to potential security threats, allowing organizations to understand the real-world business impact of cyber events. Rather than viewing security solely as a technical issue, this approach translates risks into standard financial terms, making it much easier for security leaders to communicate with corporate boards and executives. By analyzing historical data alongside the frequency and severity of potential incidents, organizations can predict financial losses across both internal systems and third-party providers. This clarity helps businesses move away from subjective guesswork, enabling them to make practical decisions about where to invest their security budgets and how to prioritize protective measures. In addition to improving internal planning, putting a dollar figure on risk helps organizations negotiate better insurance terms, measure the return on their security investments, and establish a realistic tolerance for risk. Ultimately, calculating these financial impacts provides companies with the necessary insight to reduce the overall cost of security incidents and maintain steady operations.

Read Original Article →